Run Nano Banana Locally?
A practical guide to the real deployment choices: Google's hosted Nano Banana API, open local models, and rented GPU infrastructure when your own hardware is not enough.
Choose the Right Route Fast
If you only want the practical answer, start here. These links jump to the safest matching section without changing this page's SEO structure.
Featured Models with Visual Examples
Use this preview to compare hosted-only releases with open models before going into setup commands.
Quick Model Overview
Common routes across closed cloud APIs and open, self-hostable models.
Nano Banana 2
ClosedLatest cloud route (Gemini 3.1 Flash Image). Cannot run locally.
ChatGPT Image 2
ClosedOpenAI's proprietary model. Cannot run locally.
Seedream 4.5
ClosedCloud alternative. Cannot run locally.
FLUX 3
Early AccessMultimodal image, video, and audio foundation model with action-aware research.
Qwen-Image 3.0
Hosted Only4.5K-token prompts, dense knowledge layouts, 10px text, and complex UI generation.
Qwen-Image-Edit-2511
Open20B BF16 image-editing model with an Apache-2.0 license and official Diffusers support.
Z-Image / Turbo
OpenFast local generation route. Can run locally.
GLM-Image
OpenKnowledge-heavy layouts and text rendering. Can run locally.
HunyuanImage 3.0
Open80B MoE with CoT reasoning and multi-image editing. Can run locally.
HiDream-O1-Image
Open8B pixel-level unified Transformer (no VAE). MIT license. Can run locally.
We use Artificial Analysis as a practical third-party preference reference. For this page, the more important distinction is whether a route is closed cloud-only or open and locally deployable.
| Model | Type | Best For | GPU Req | Deploy / Ranking Note |
|---|---|---|---|---|
| Nano Banana 2 | Closed | Latest cloud image route with reasoning-driven generation | — | Cloud only · cannot run locally · AA Apr 2026: T2I #2 / Edit #3 |
| ChatGPT Image 2 | Closed | OpenAI's proprietary image generation model | — | Cloud only · cannot run locally · AA Apr 2026: T2I #1 / Edit #2 |
| Seedream 4.5 | Closed | Alternative proprietary image route | — | Cloud only · cannot run locally |
| FLUX 3 | Early Access | Multimodal image, video, audio, and action-aware generation | — | Image access coming soon · private/API access and future open-weight FLUX 3 Dev roadmap |
| Qwen-Image 3.0 | Hosted Only | Dense layouts, 4.5K-token prompts, 10px text, and complex UI | — | Cloud preview · official weights and local deployment not released |
| Qwen-Image-Edit-2511 | Open | Image editing, subject consistency, LoRA-assisted workflows | Not specified in official model card | 20B BF16 · Apache-2.0 · official Diffusers pipeline |
| Z-Image / Turbo | Open | Fast local generation, 8-step efficiency, balanced quality/speed | 16GB+ | Local deployable · official GitHub release · not in current top AA snapshot |
| GLM-Image | Open | Text rendering, knowledge-heavy layouts, rich image-to-image tasks | CUDA required; official repository gives no fixed minimum | Local deployable · official Hugging Face release · not in current top AA snapshot |
| HunyuanImage 3.0 | Open | CoT reasoning, intelligent editing, multi-image fusion (up to 3 inputs) | Base ≥3×80GB; Instruct ≥8×80GB | Official repository recommendation · Tencent Community License |
| HiDream-O1-Image | Open | Long-text rendering, instruction editing, subject-driven personalization, storyboards | 24GB+ | AA open-weight T2I #8 (April 2026 snapshot) · MIT License |
⚠️ Important: Nano Banana is Closed-Source
Nano Banana 2 (Gemini 3.1 Flash Image) is a closed-source cloud API and cannot be deployed locally. If you're looking to run AI image generation on your own hardware, please scroll down to our Open-Source Alternatives section below — we provide detailed guides for HunyuanImage 3.0, GLM-Image, Qwen-Image, and Z-Image, all of which can run locally with the right GPU and software stack.
💡 No GPU? You Can Still Run Open Models
Hardware ranges from consumer GPUs to multi-node-class configurations. Check each official model card before renting a machine; a single 48GB or 80GB GPU is not enough for every model listed here.
See our Run Without a GPU guide for provider choices, configuration checks, and a process for verifying current costs before you rent.
Nano Banana 2
⚠️ Cloud API Only — Cannot Run Locally. The latest Gemini 3.1 Flash Image model with reasoning-driven generation, high-precision text rendering, and subject consistency across images. AA T2I #2 (Elo 1,256) · Edit #3 (Elo 1,245) as of April 2026.
pip install google-genai
from google import genai
client = genai.Client(api_key="YOUR_KEY")Prefer open models? Match the rental configuration to the official hardware requirements first; HunyuanImage 3.0, Qwen-Image-Edit-2511, and HiDream-O1-Image do not share the same footprint. See Run Without a GPU →
ChatGPT Image 2
⚠️ Cannot Run Locally. ChatGPT Image 2 is OpenAI's proprietary image generation model. OpenAI does not release model weights, which means there is no legal or technical way to deploy it on your own hardware. AA T2I #1 (Elo 1,307) · Edit #2 (Elo 1,273) as of April 2026.
Seedream 4.5
⚠️ Cloud API Only. Another cloud alternative with excellent quality.
Visit Official Site ↗HunyuanImage 3.0 Instruct
Tencent describes HunyuanImage 3.0 as an 80B-parameter MoE model with 13B active parameters per token. There are two variants: HunyuanImage 3.0 (text-to-image) and HunyuanImage 3.0 Instruct (editing + reasoning). The Instruct version excels at image editing via reasoning, prompt self-rewrite, and multi-image fusion (up to 3 inputs). A dated third-party snapshot placed it at AA open-weight Editing #1 (Elo 1,224) in April 2026; treat rankings as time-sensitive rather than a permanent product claim.
Planning cloud deployment? Follow the official hardware table, then use our cloud planning guide. Verify the provider's current multi-GPU price before launch.
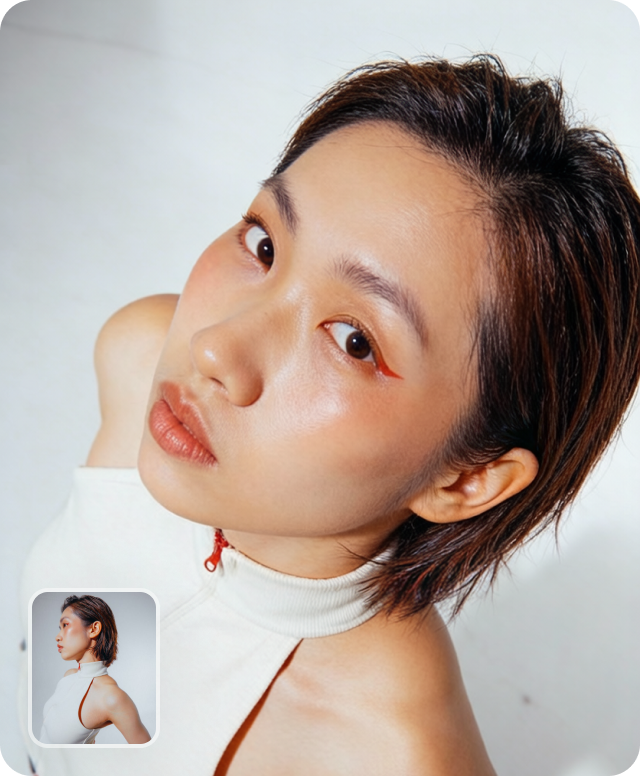
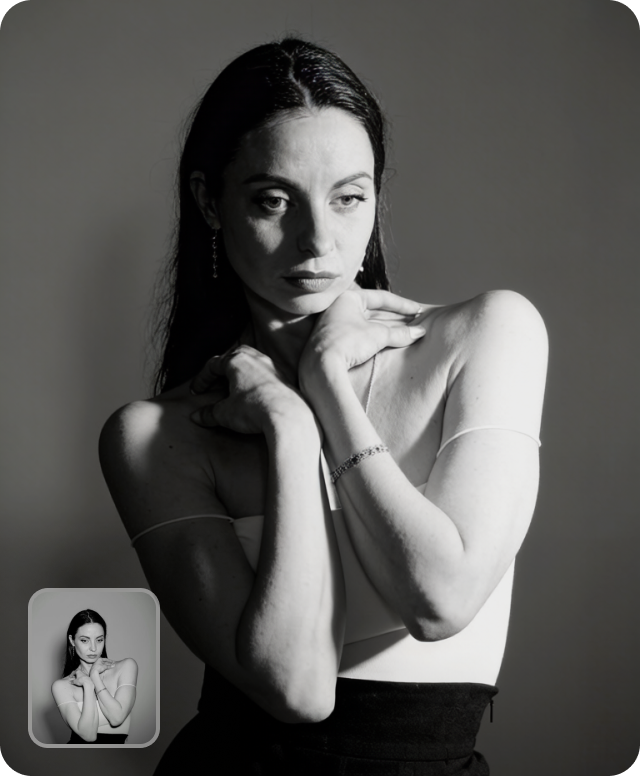
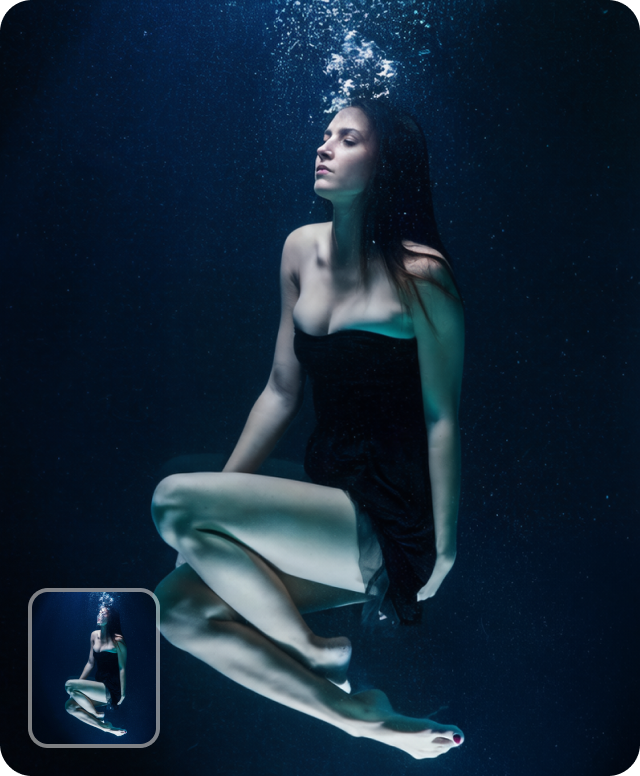
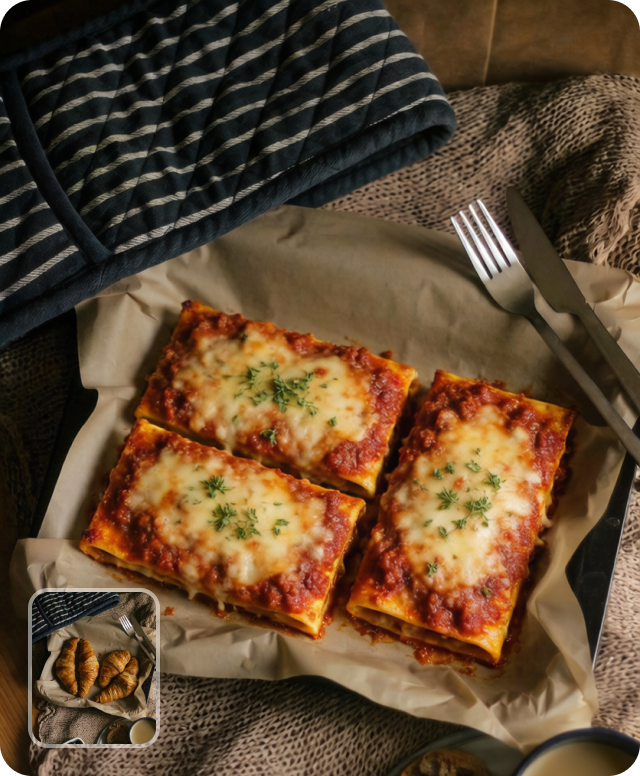
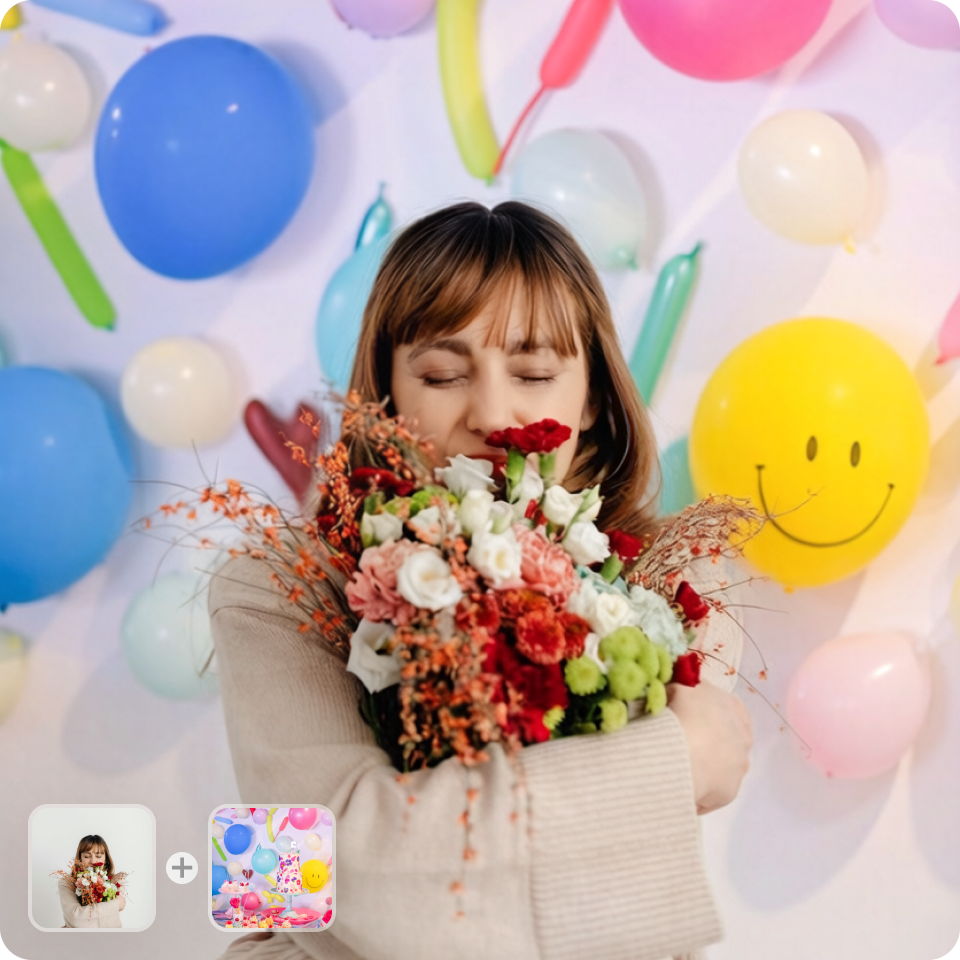
Reasoning-Level Image Editing: Transform at Your Command
Native multimodal models are capable of first analyzing the content of user-provided images and editing instructions before generating an edited result.
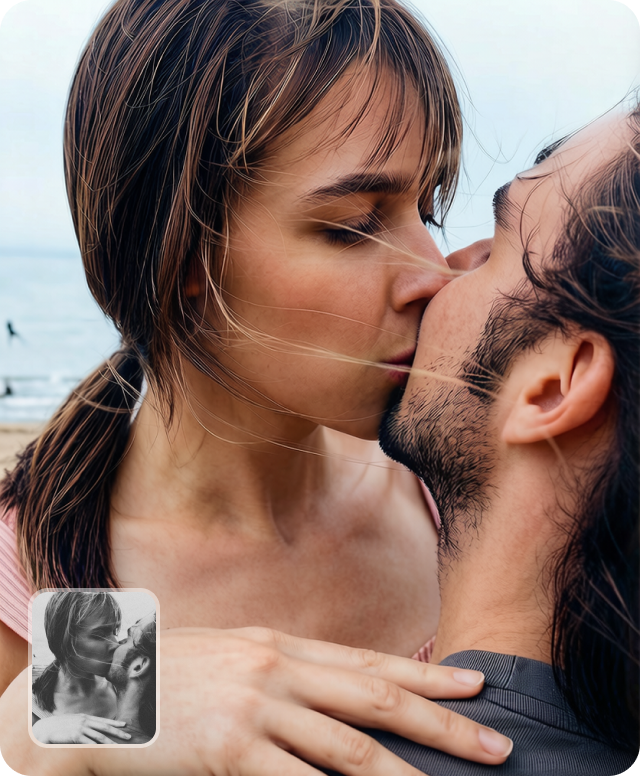
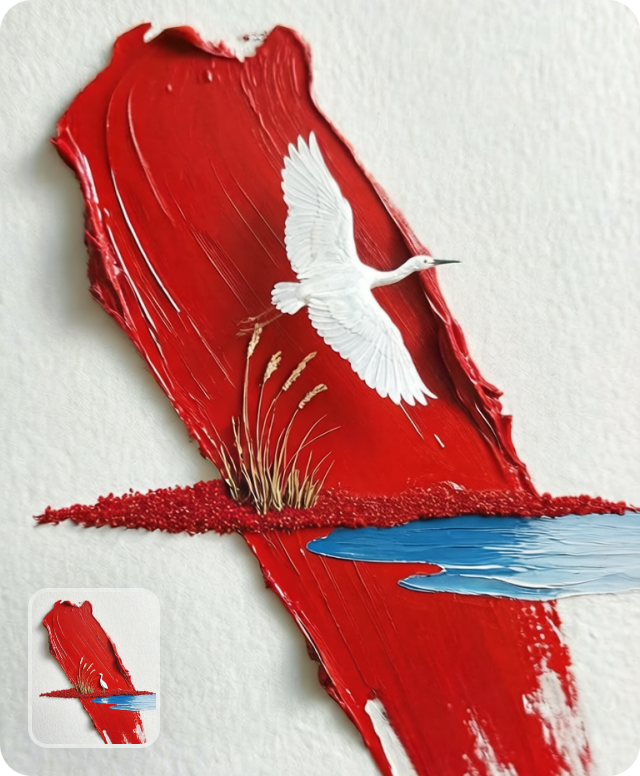
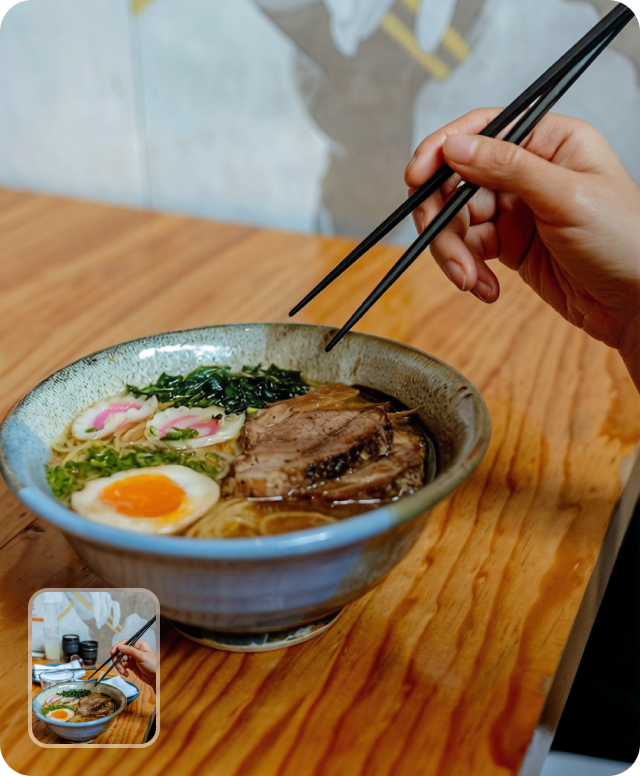
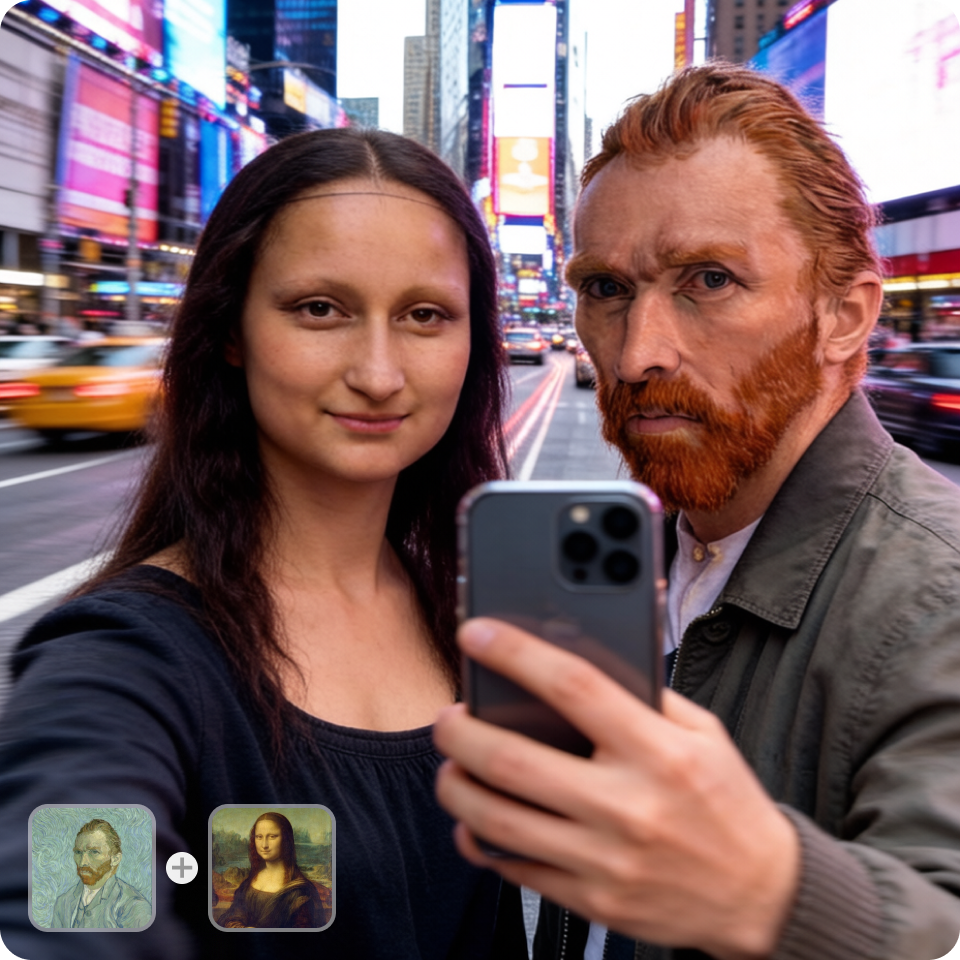
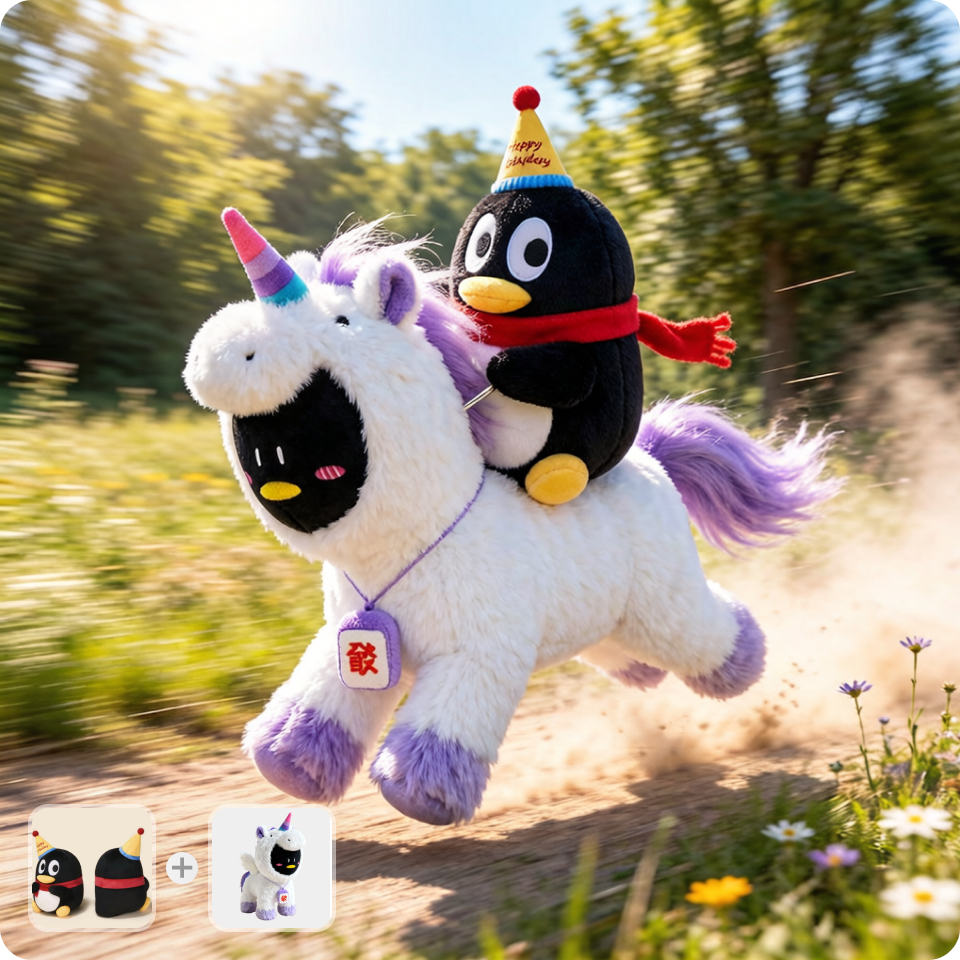
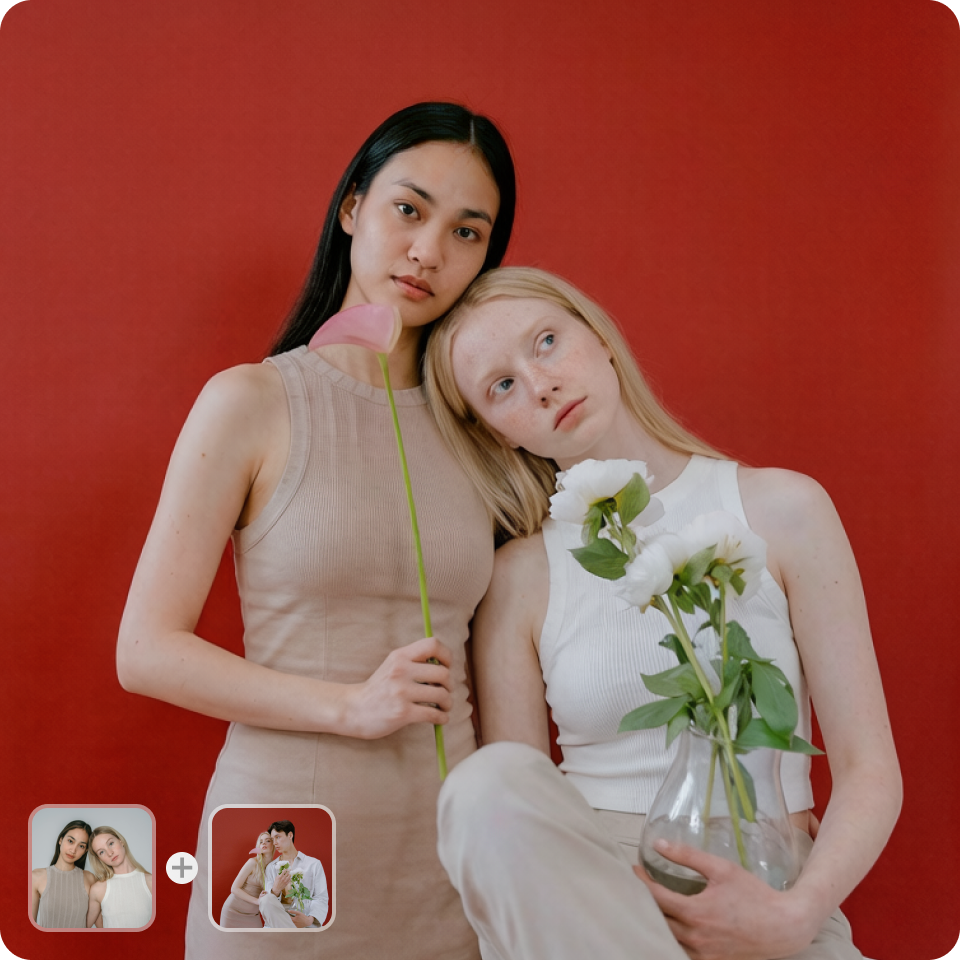
Multi-Image Fusion: Infinite Possibilities
Enables the fusion of up to three input images and generates outputs consistent with reference images.
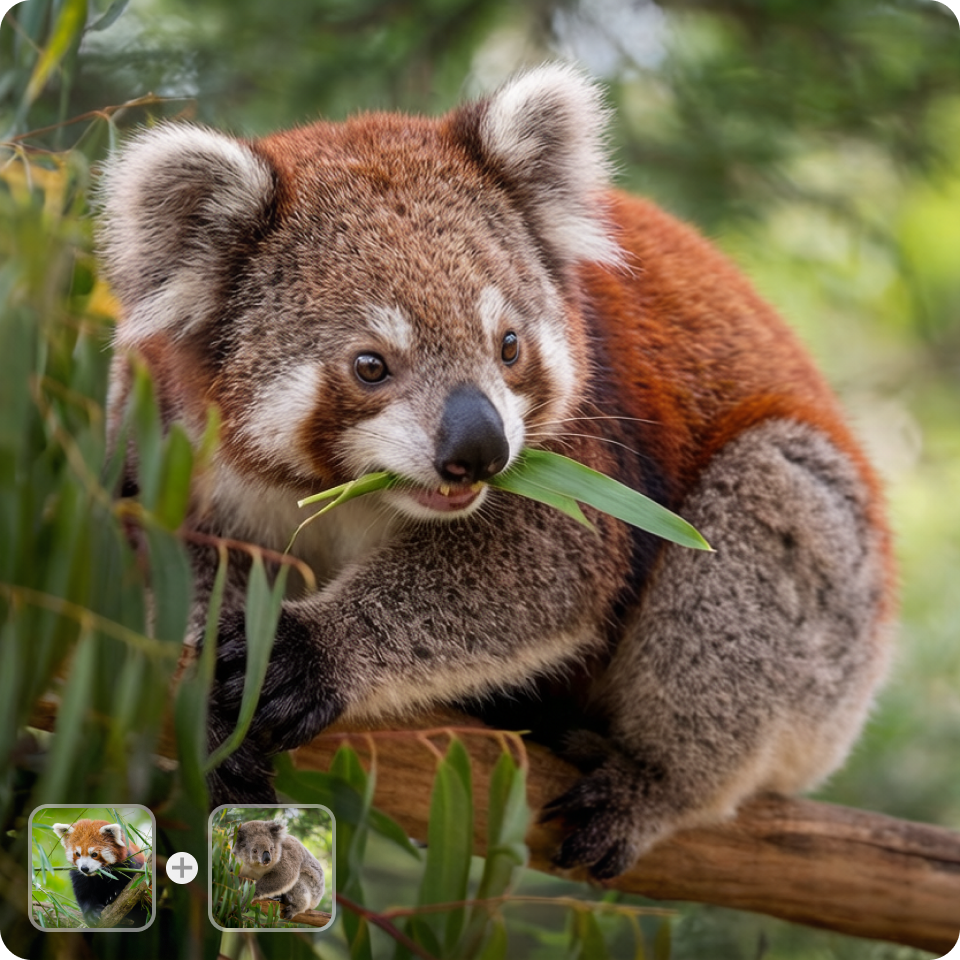
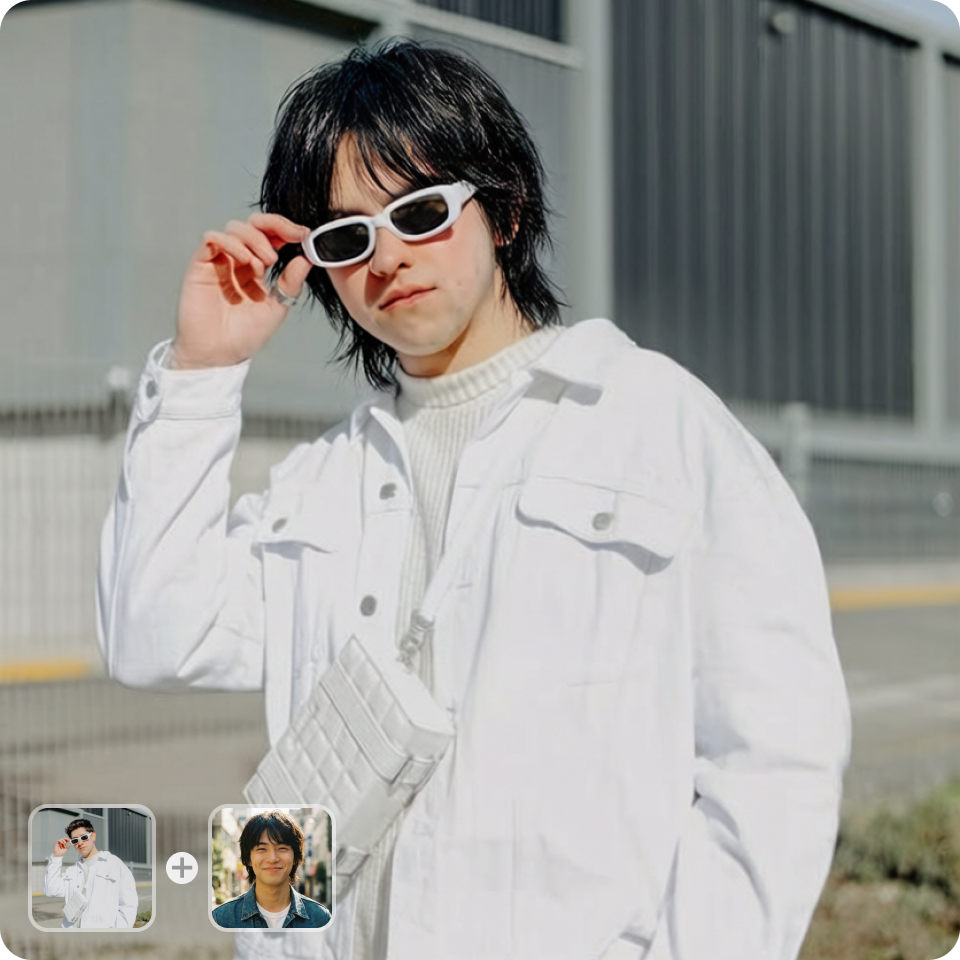
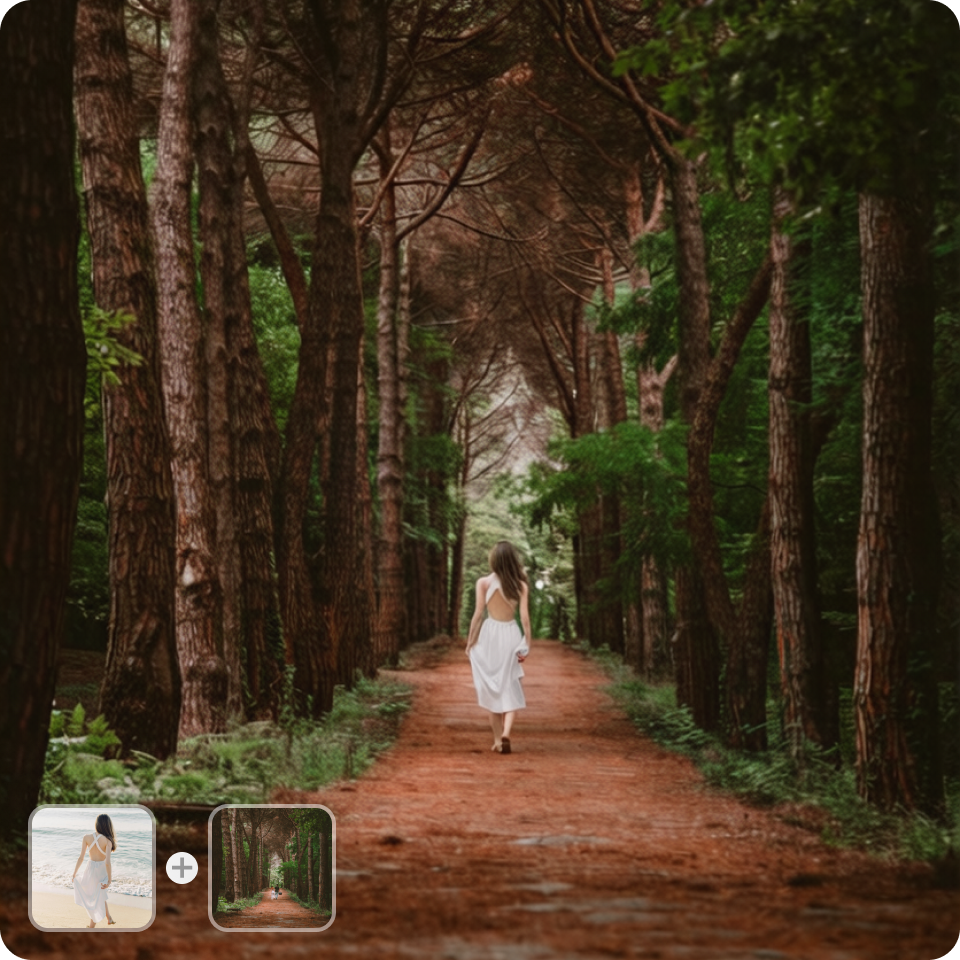
Technical Details
We use an MoE LLM as the base model and introduce image understanding and generation capabilities into the model. For image understanding tasks, we utilize a joint feature composed of VAE and ViT as the image input; for image generation tasks, we incorporate Diffusion-based image modeling into the LLM architecture based on the Transfusion approach. Through mixed training of different multimodal tasks, we are able to unleash the potential of the MoE architecture and enhance the model's generalization ability. HunyuanImage 3.0 is the image generation component of this model.
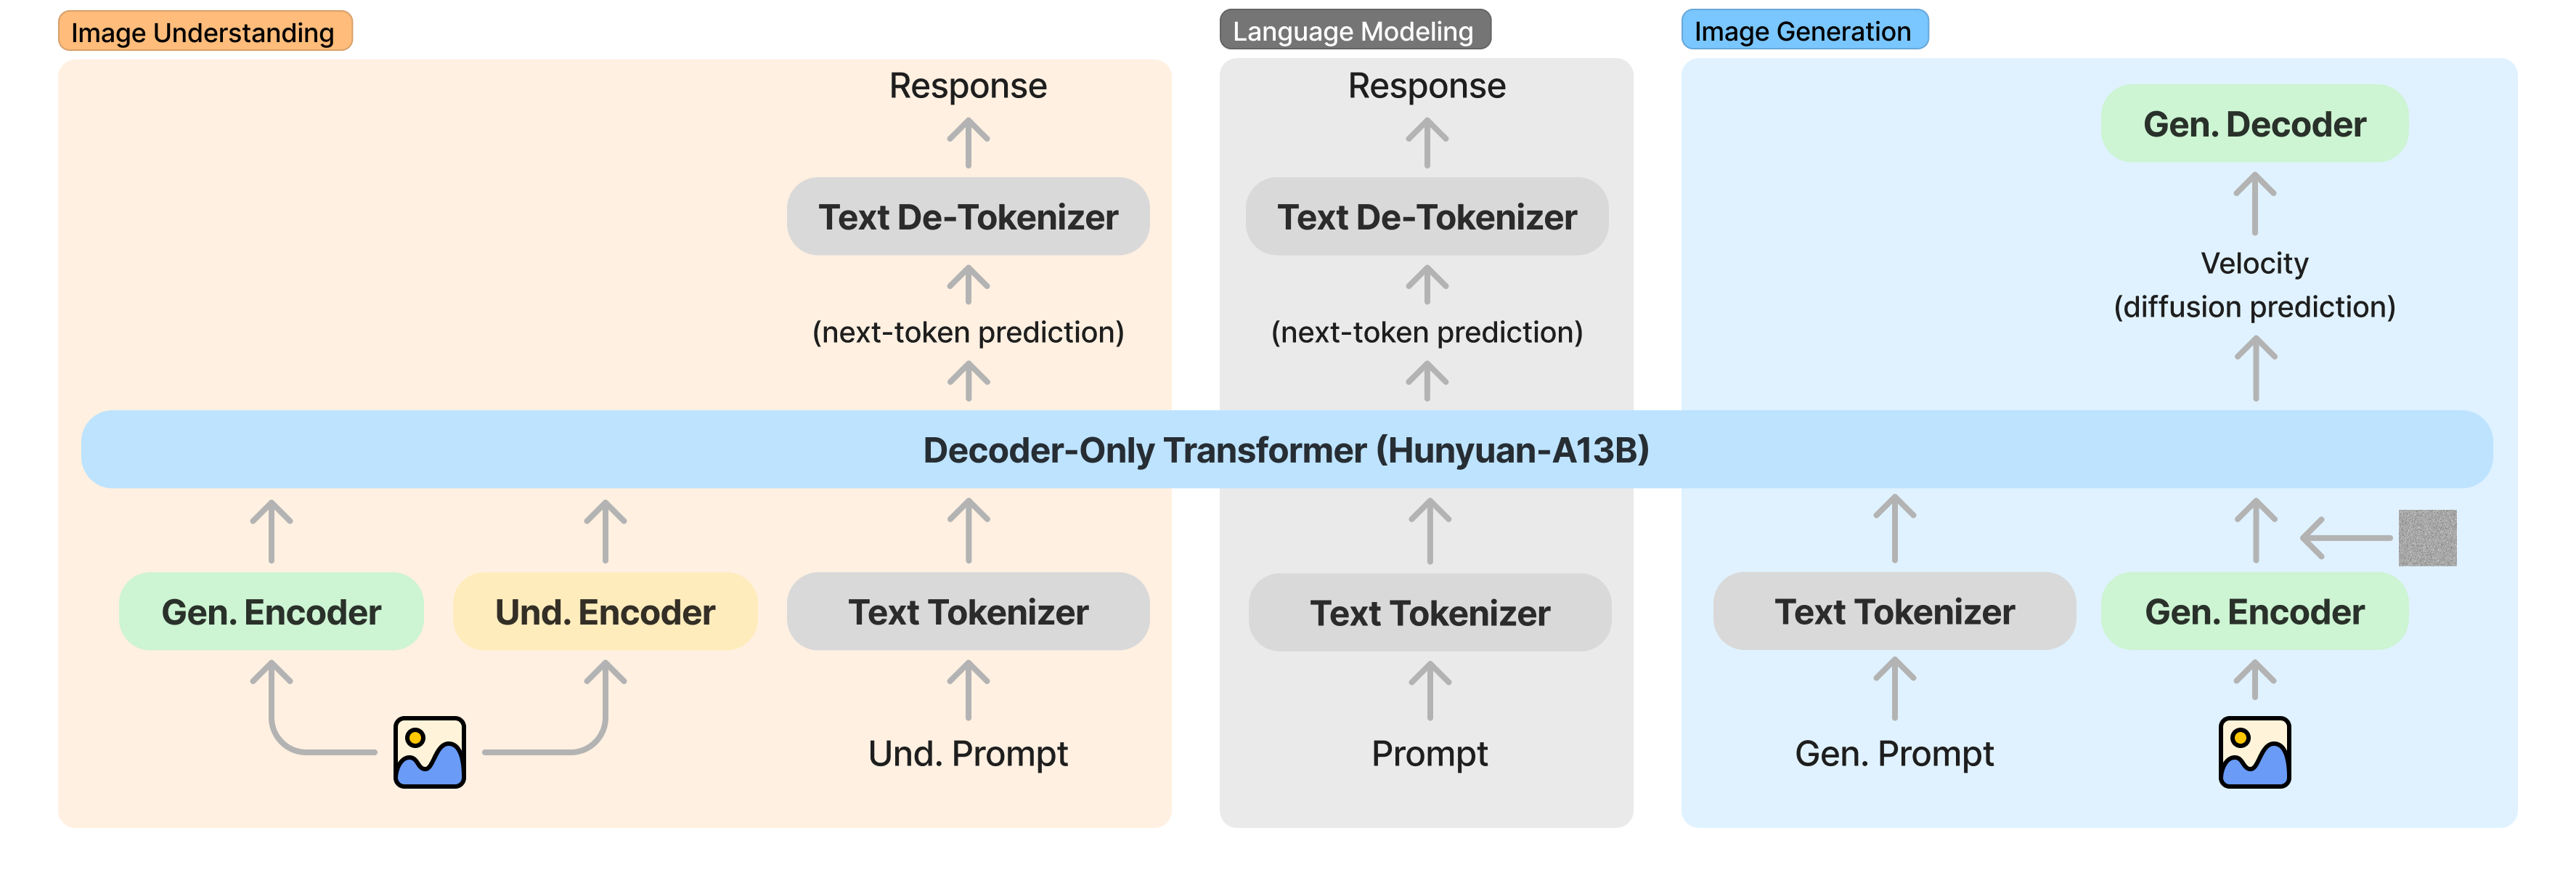
Decoder-Only Transformer (Hunyuan-A13B) — unified architecture for image understanding, language modeling, and image generation.
For multimodal data with intertwined text and images, we have specifically designed attention masks and 2D positional encoding. The attention mask isolates noisy images from clean images, ensuring that different images within a rich-text sequence do not interfere with each other. By employing 2D RoPE compatible with the original 1D RoPE of the LLM base model, we promote more efficient learning and convergence of image structures.
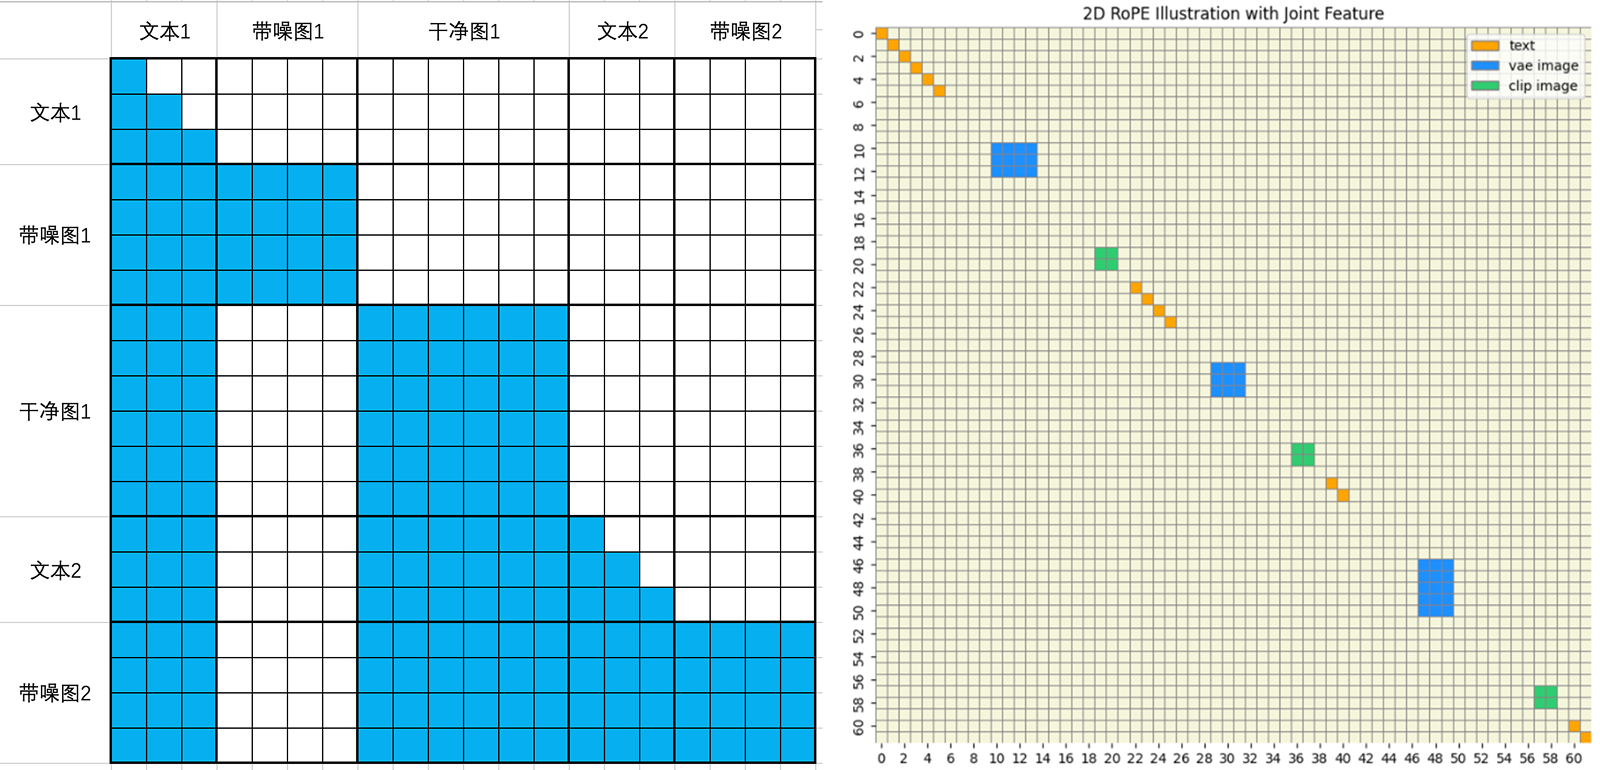
2D RoPE illustration with joint feature — attention mask design ensures text and image tokens do not interfere during training.
Native Chain-of-Thought (CoT) Generation: To leverage the advantages of native multimodal models, we have constructed a Chain-of-Thought process for every image-to-image data point. The model is guided to first analyze the features of the original image, then further decompose the user's instructions. By combining the image feature analysis with the user's intent, the model constructs a more complex and systematic fine-grained editing command. This command includes specific details on how to modify the areas requiring change, as well as which features from the original image must be preserved. Ultimately, the model expands the user's prompt into a complex, detailed, and structured instruction.
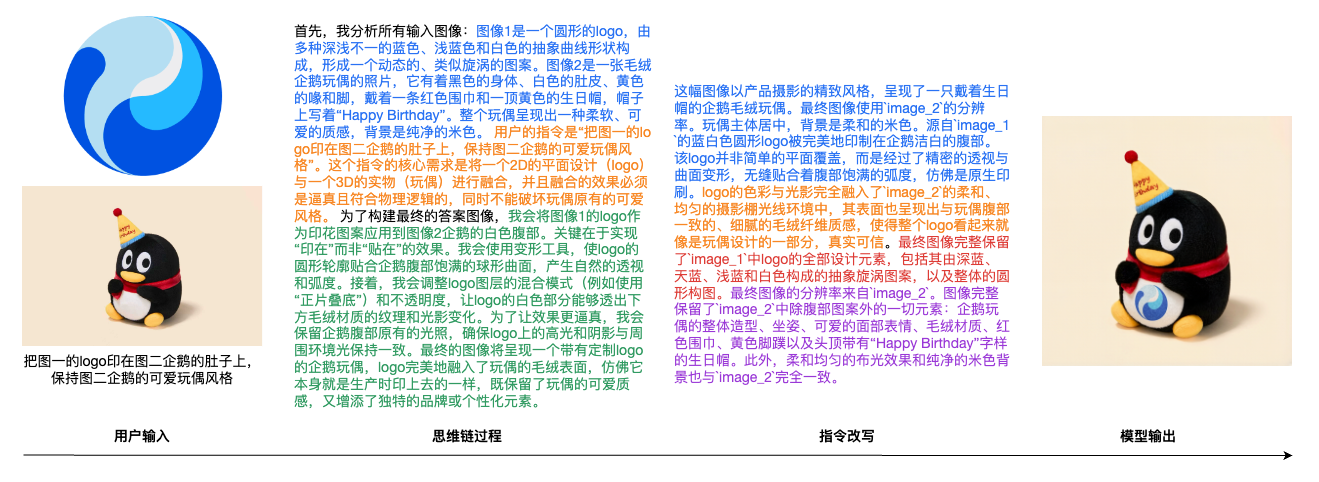
Native CoT Generation workflow — the model analyzes input images, decomposes instructions, and constructs structured editing commands before generation.
Model Variants
| Model | Focus | Steps | Link |
|---|---|---|---|
| HunyuanImage-3.0 | Text-to-Image | 50 | HF |
| HunyuanImage-3.0-Instruct | Editing + Reasoning | 50 | HF |
| HunyuanImage-3.0-Instruct-Distil | Fast Inference | 8 | HF |
Quick Start: Transformers
pip install torch==2.8.0 torchvision==0.23.0 --index-url https://download.pytorch.org/whl/cu128
from transformers import AutoModelForCausalLM

model_id = "./HunyuanImage-3-Instruct"
kwargs = dict(
    attn_implementation="sdpa",
    trust_remote_code=True,
    torch_dtype="auto",
    device_map="auto",
    moe_impl="eager",  # Use "flashinfer" if installed
    moe_drop_tokens=True,
)
model = AutoModelForCausalLM.from_pretrained(model_id, **kwargs)
model.load_tokenizer(model_id)

prompt = "A futuristic city at sunset with flying vehicles"
cot_text, samples = model.generate_image(
    prompt=prompt, seed=42, image_size="1024x1024",
    use_system_prompt="en_unified",
    bot_task="think_recaption",
    diff_infer_steps=50, verbose=2
)
samples[0].save("output.png")
License
Tencent Hunyuan Community License. Review the repository's current license terms and restrictions before commercial deployment.
Citation
@article{cao2025hunyuanimage,
  title={HunyuanImage 3.0 Technical Report},
  author={Cao, Siyu and Chen, Hangting and Chen, Peng et al.},
  journal={arXiv preprint arXiv:2509.23951},
  year={2025}
}
GLM-Image
A hybrid autoregressive model for dense information generation.
Full Technical Details (Repo Mirror)
Hybrid Architecture: AR Transformer (Semantic) + Diffusion Decoder (Detail).
Introduction
GLM-Image is an image generation model that adopts a hybrid autoregressive + diffusion decoder architecture. According to the official release, it shows significant advantages in text rendering and knowledge-intensive generation, while also supporting text-to-image and rich image-to-image workflows.
Architecture
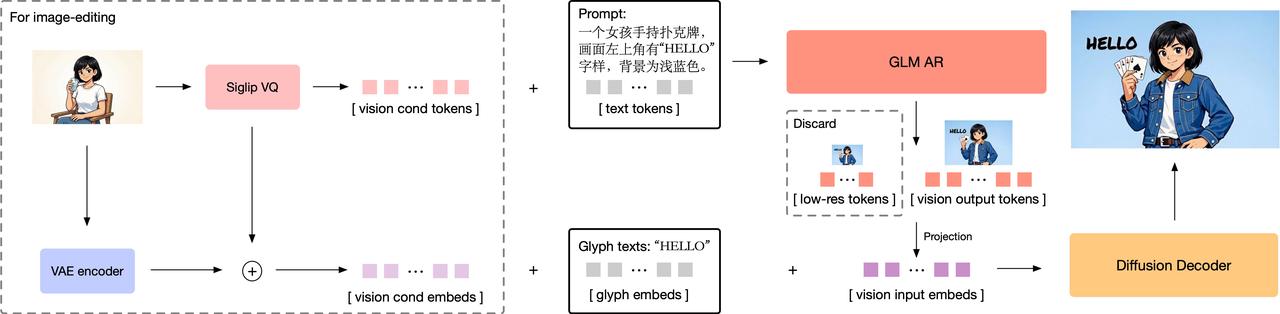
- Autoregressive Generator: 9B parameter model initialized from GLM-4-9B. Expands 256 compact tokens to 1K-4K visual tokens.
- Diffusion Decoder: 7B parameter single-stream DiT for latent decoding. Features a Glyph Encoder for text rendering.
Inference Cost (H100)
| Res | Batch | Time (s) | Peak VRAM |
|---|---|---|---|
| 1024x1024 | 1 | 64.34 | 37.82 GB |
| 2048x2048 | 1 | 252.59 | 45.08 GB |
| 512x512 | 1 | 27.30 | 34.26 GB |
Quick Start: Diffusers
pip install git+https://github.com/huggingface/diffusers.git transformers
import torch
from diffusers import GlmImagePipeline
pipe = GlmImagePipeline.from_pretrained("zai-org/GLM-Image", torch_dtype=torch.bfloat16).to("cuda")
image = pipe(prompt="A futuristic city", width=1024, height=1024).images[0]
Quick Start: SGLang Server
pip install "sglang[diffusion] @ git+https://github.com/sgl-project/sglang.git#subdirectory=python"
sglang serve --model-path zai-org/GLM-Image
# Client
curl http://localhost:30000/v1/images/generations -d '{"prompt": "hello world", "size": "1024x1024"}'FLUX 3
FLUX 3 is Black Forest Labs' new multimodal foundation model. It jointly learns from images, video, and audio in one architecture, aiming to understand the shared structure of the physical and digital world rather than treating each modality as an isolated task.

Official capability overview: FLUX 3 is presented as one multimodal foundation spanning image, video, audio, and action prediction. Served through the official Black Forest Labs CDN with automatic format optimization.
Capabilities, Release Plan, and Local Status
FLUX 3 is designed as one shared multimodal flow-matching foundation for content creation, perception, action prediction, and future physical-AI workflows.
Highlighted Capabilities
- Video with audio: Generates video clips up to 20 seconds with native audio generation.
- Reference-guided generation: Supports image-to-video, video-to-video, visual references, keyframes, and audio/video continuation.
- Multilingual and stylistic range: Handles multilingual dialogue, animation, cinematics, candid footage, and varied aspect ratios.
- Image generation and editing: The official announcement says complex prompt following and multilingual text rendering have improved over earlier FLUX generations.
- Action-aware research: The same backbone is being explored for action prediction and robotics partnerships such as FLUX-mimic.
Release Plan
- FLUX 3 Video: Video and audio generation/editing through APIs and private weight access after Early Access.
- FLUX 3 Image: Image synthesis and editing through APIs and private weight access; image Early Access is expected in the following weeks.
- FLUX 3 Dev: Black Forest Labs lists future open-weight access to a multimodal backbone for content creation and action prediction.
Benchmark Caution
The official comparisons against other video models are preliminary, use an evolving model and evaluation harness, and should not be treated as a stable leaderboard ranking. We will add reproducible results only after public access and fixed evaluation details are available.
Official Source
Read the Black Forest Labs FLUX 3 announcement for the current Early Access status, capability descriptions, evaluations, and launch plan.
Qwen-Image 3.0
Qwen-Image 3.0 is Alibaba's third-generation image foundation model. The official release focuses on rich content, authentic details, and deep knowledge: it accepts prompts up to 4.5K tokens, renders text as small as 10px, supports 12 languages, and targets dense layouts such as knowledge graphics, newspapers, academic pages, storyboards, and layered UI mockups.
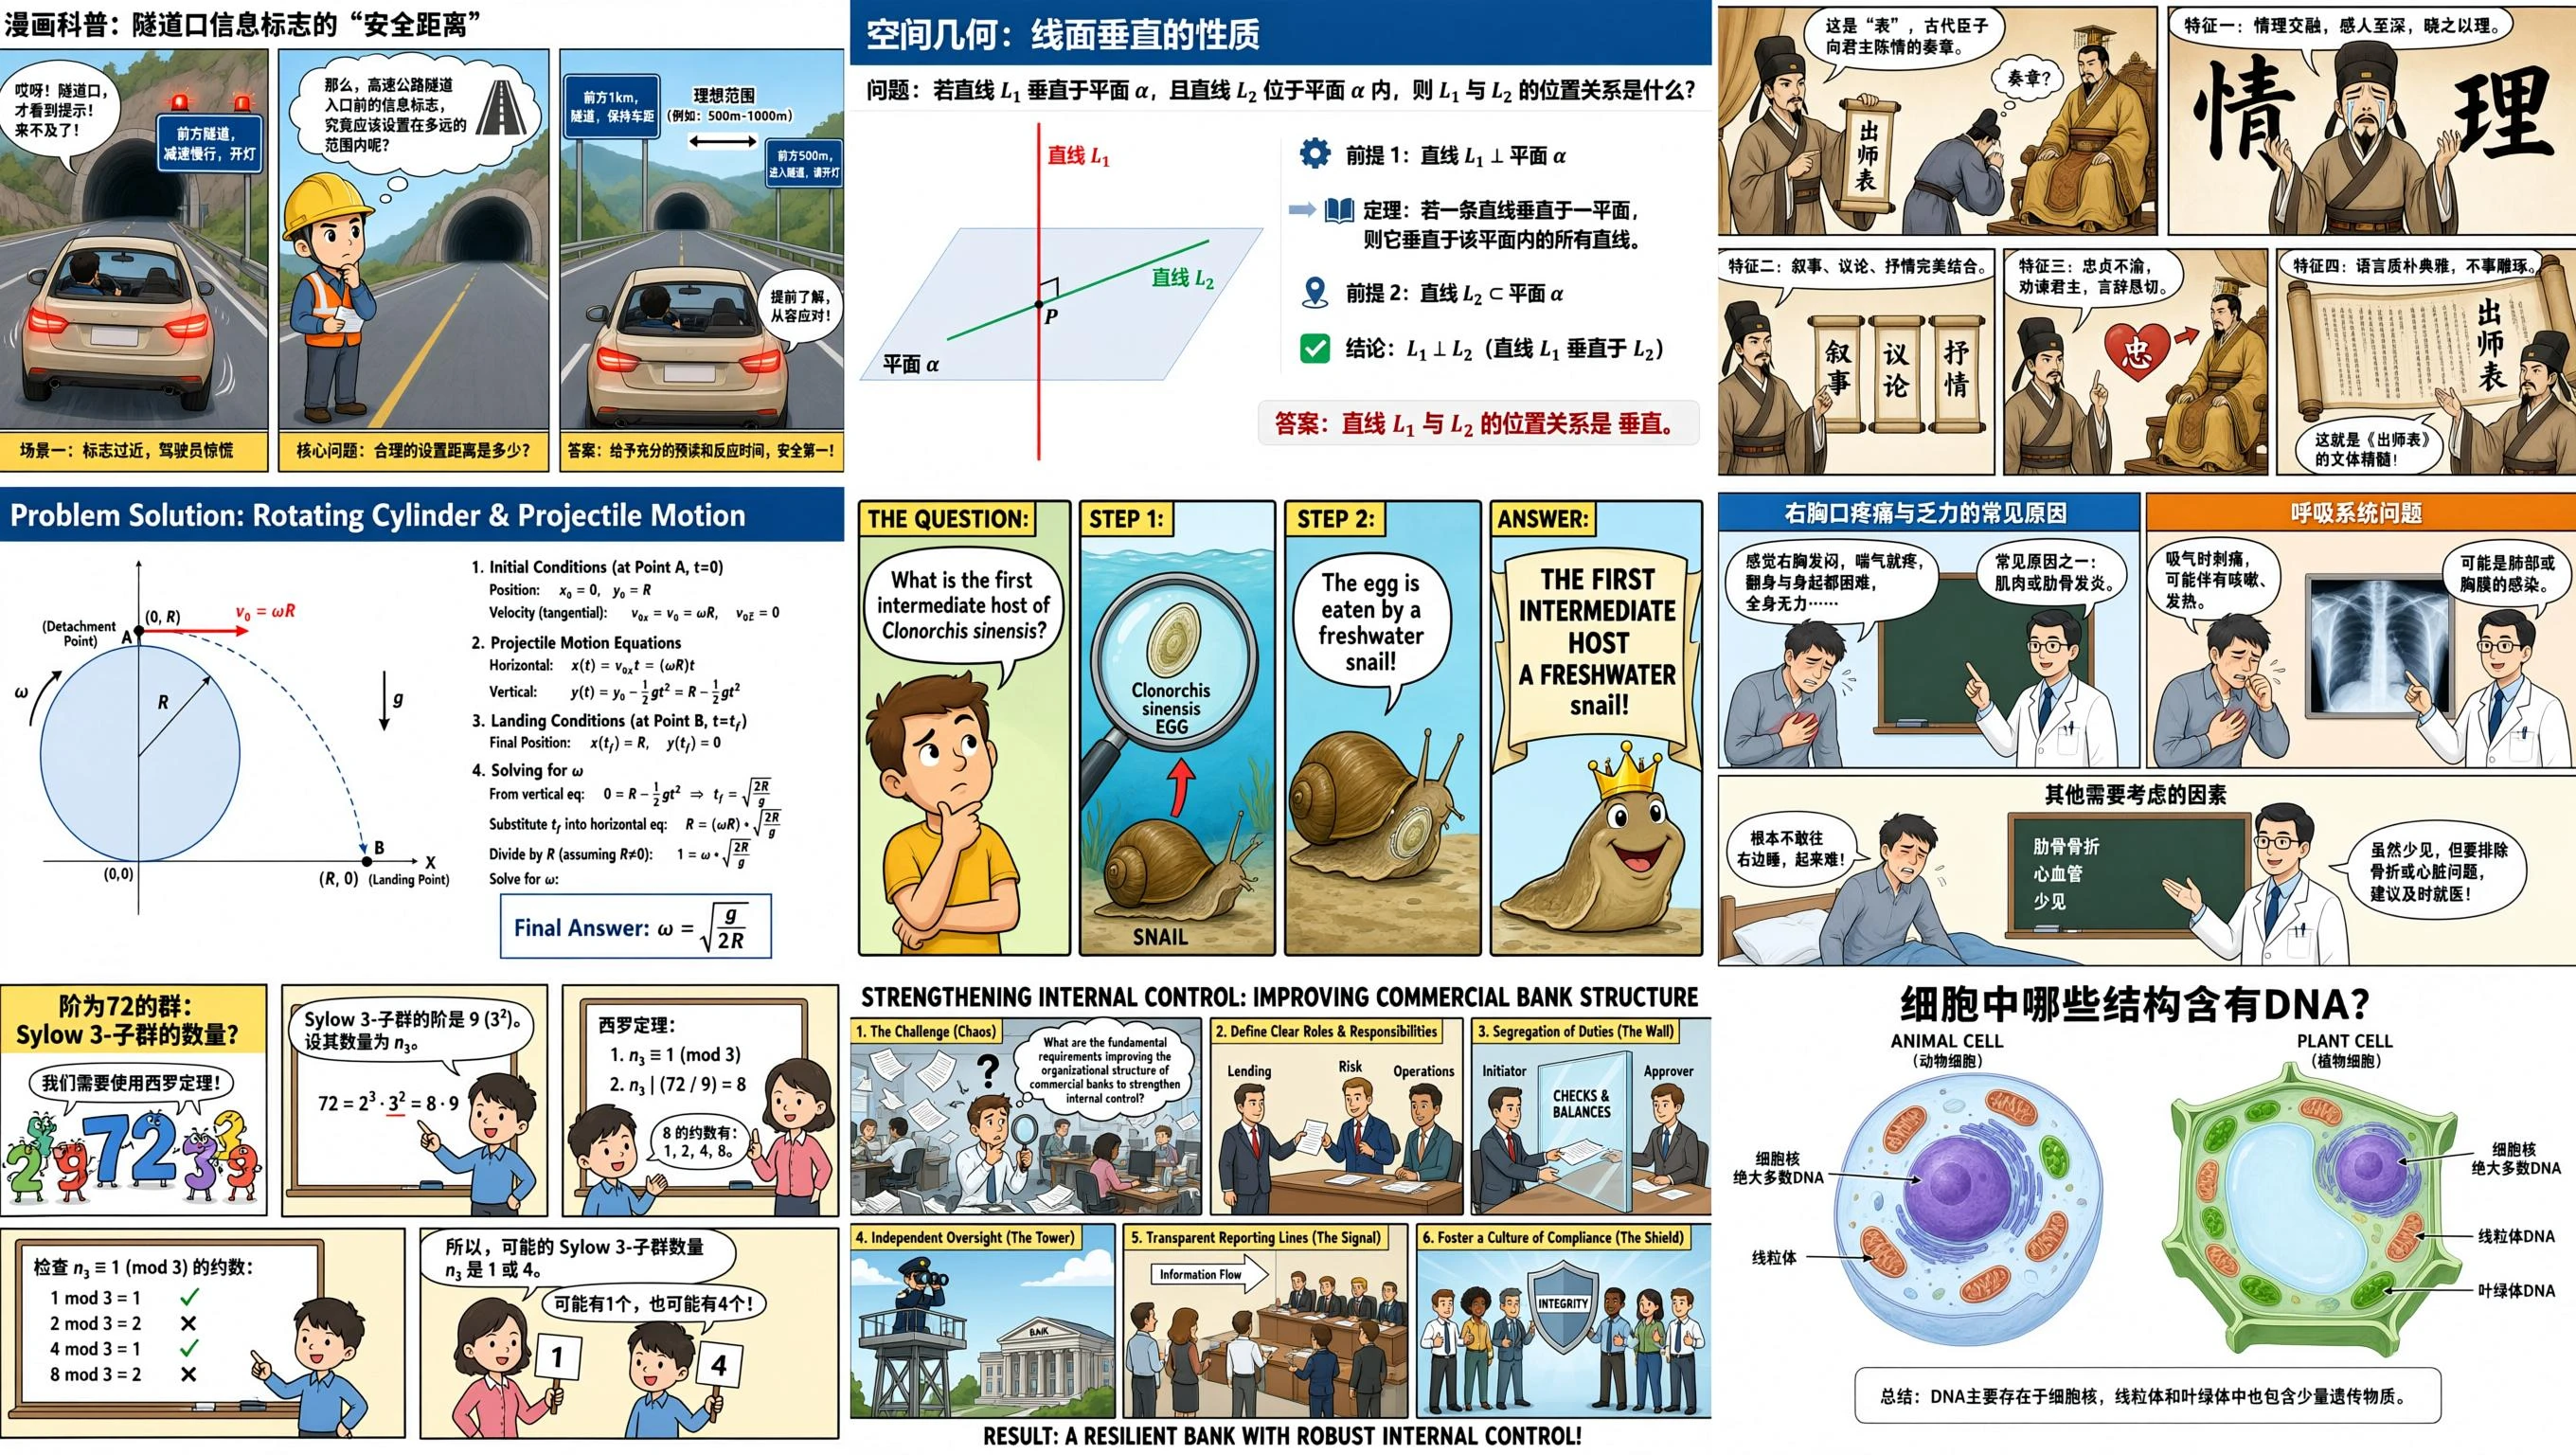
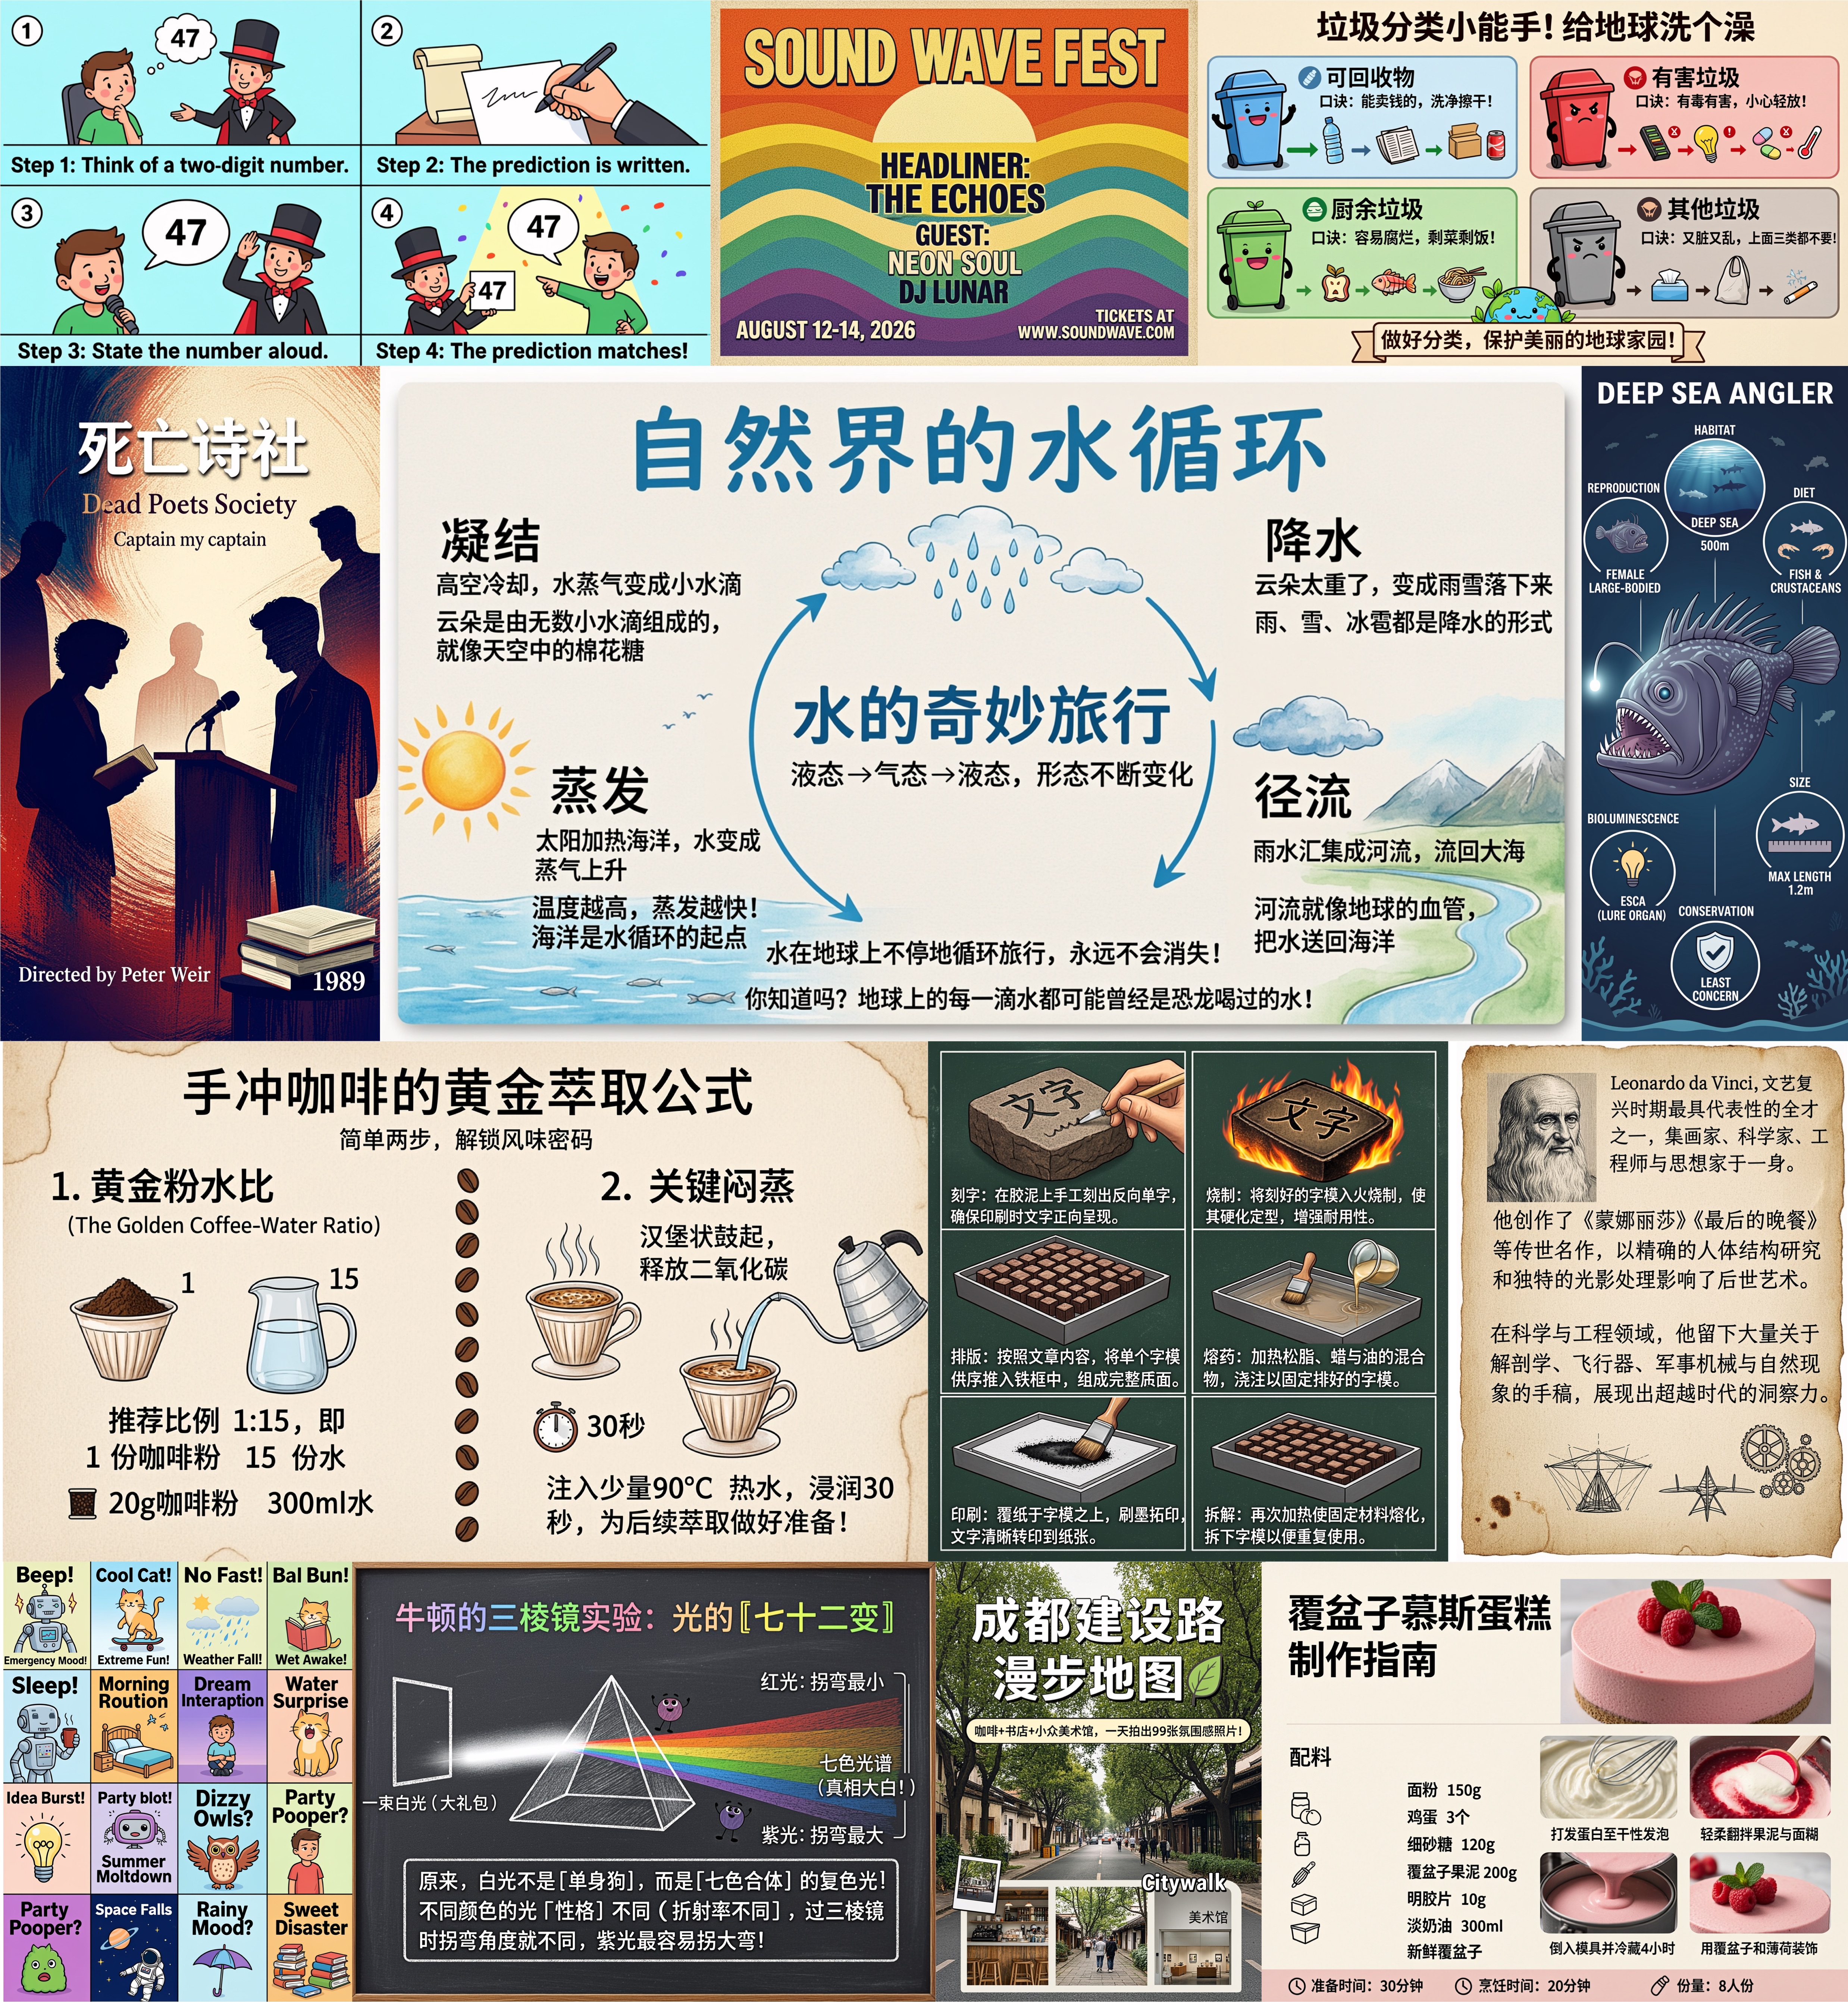
Rich content in one pass: nine knowledge panels combine diagrams, formulas, comics, and multilingual labels.
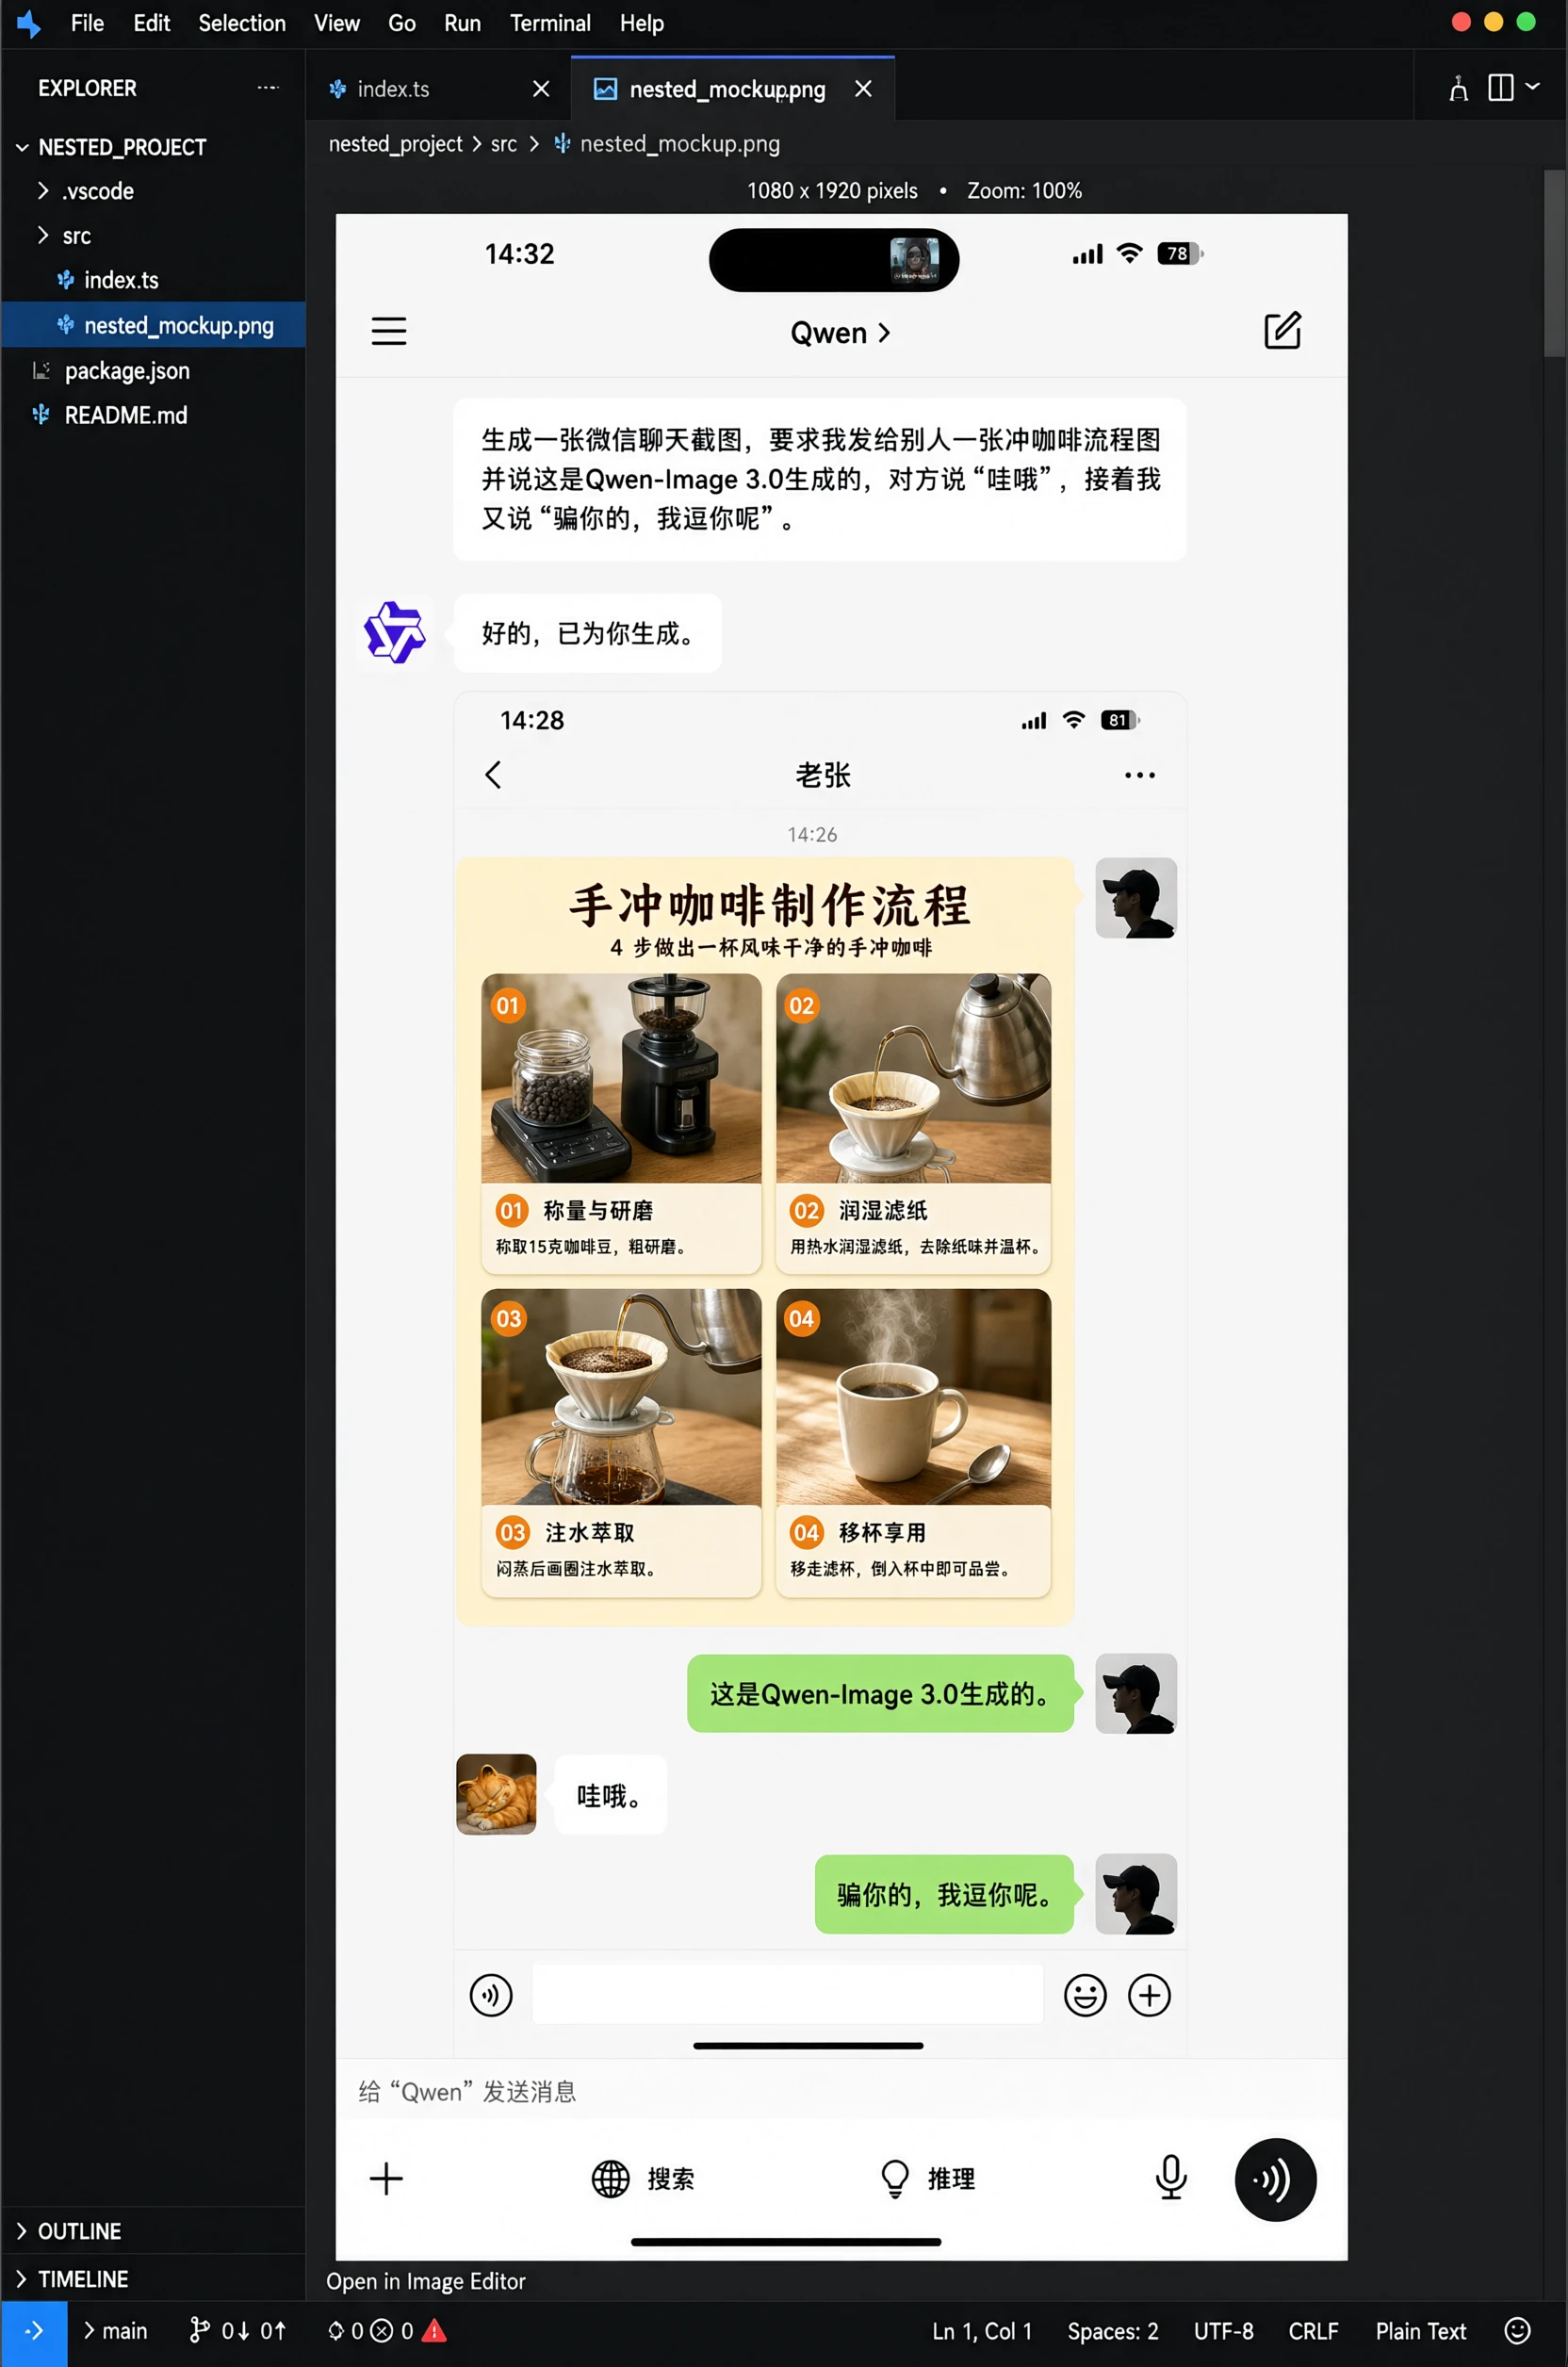
Vertical composition and nested interfaces: a Qwen conversation contains a structured coffee-making guide.
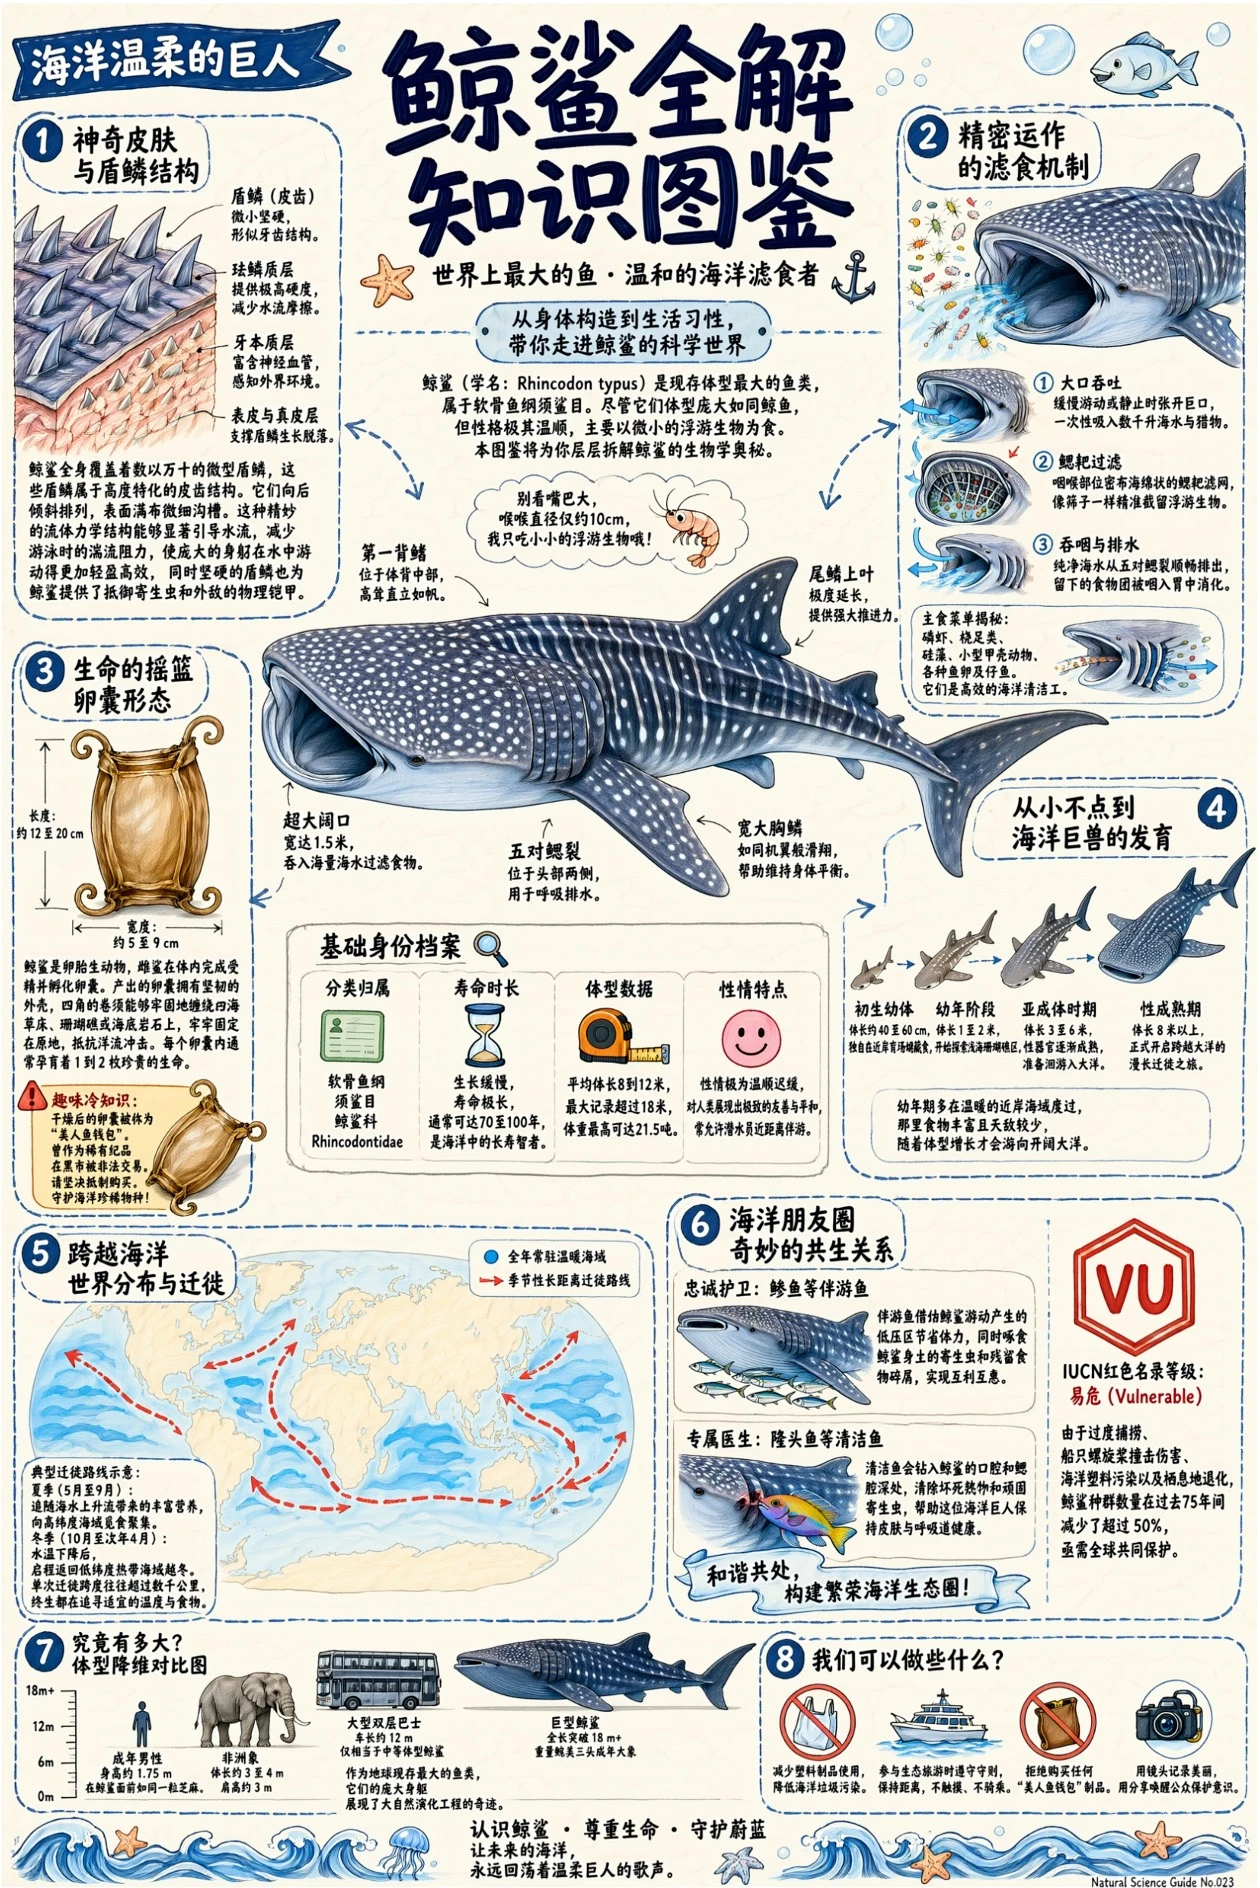
Knowledge-rich infographic: long Chinese text, classification details, diagrams, maps, and scale references stay organized.
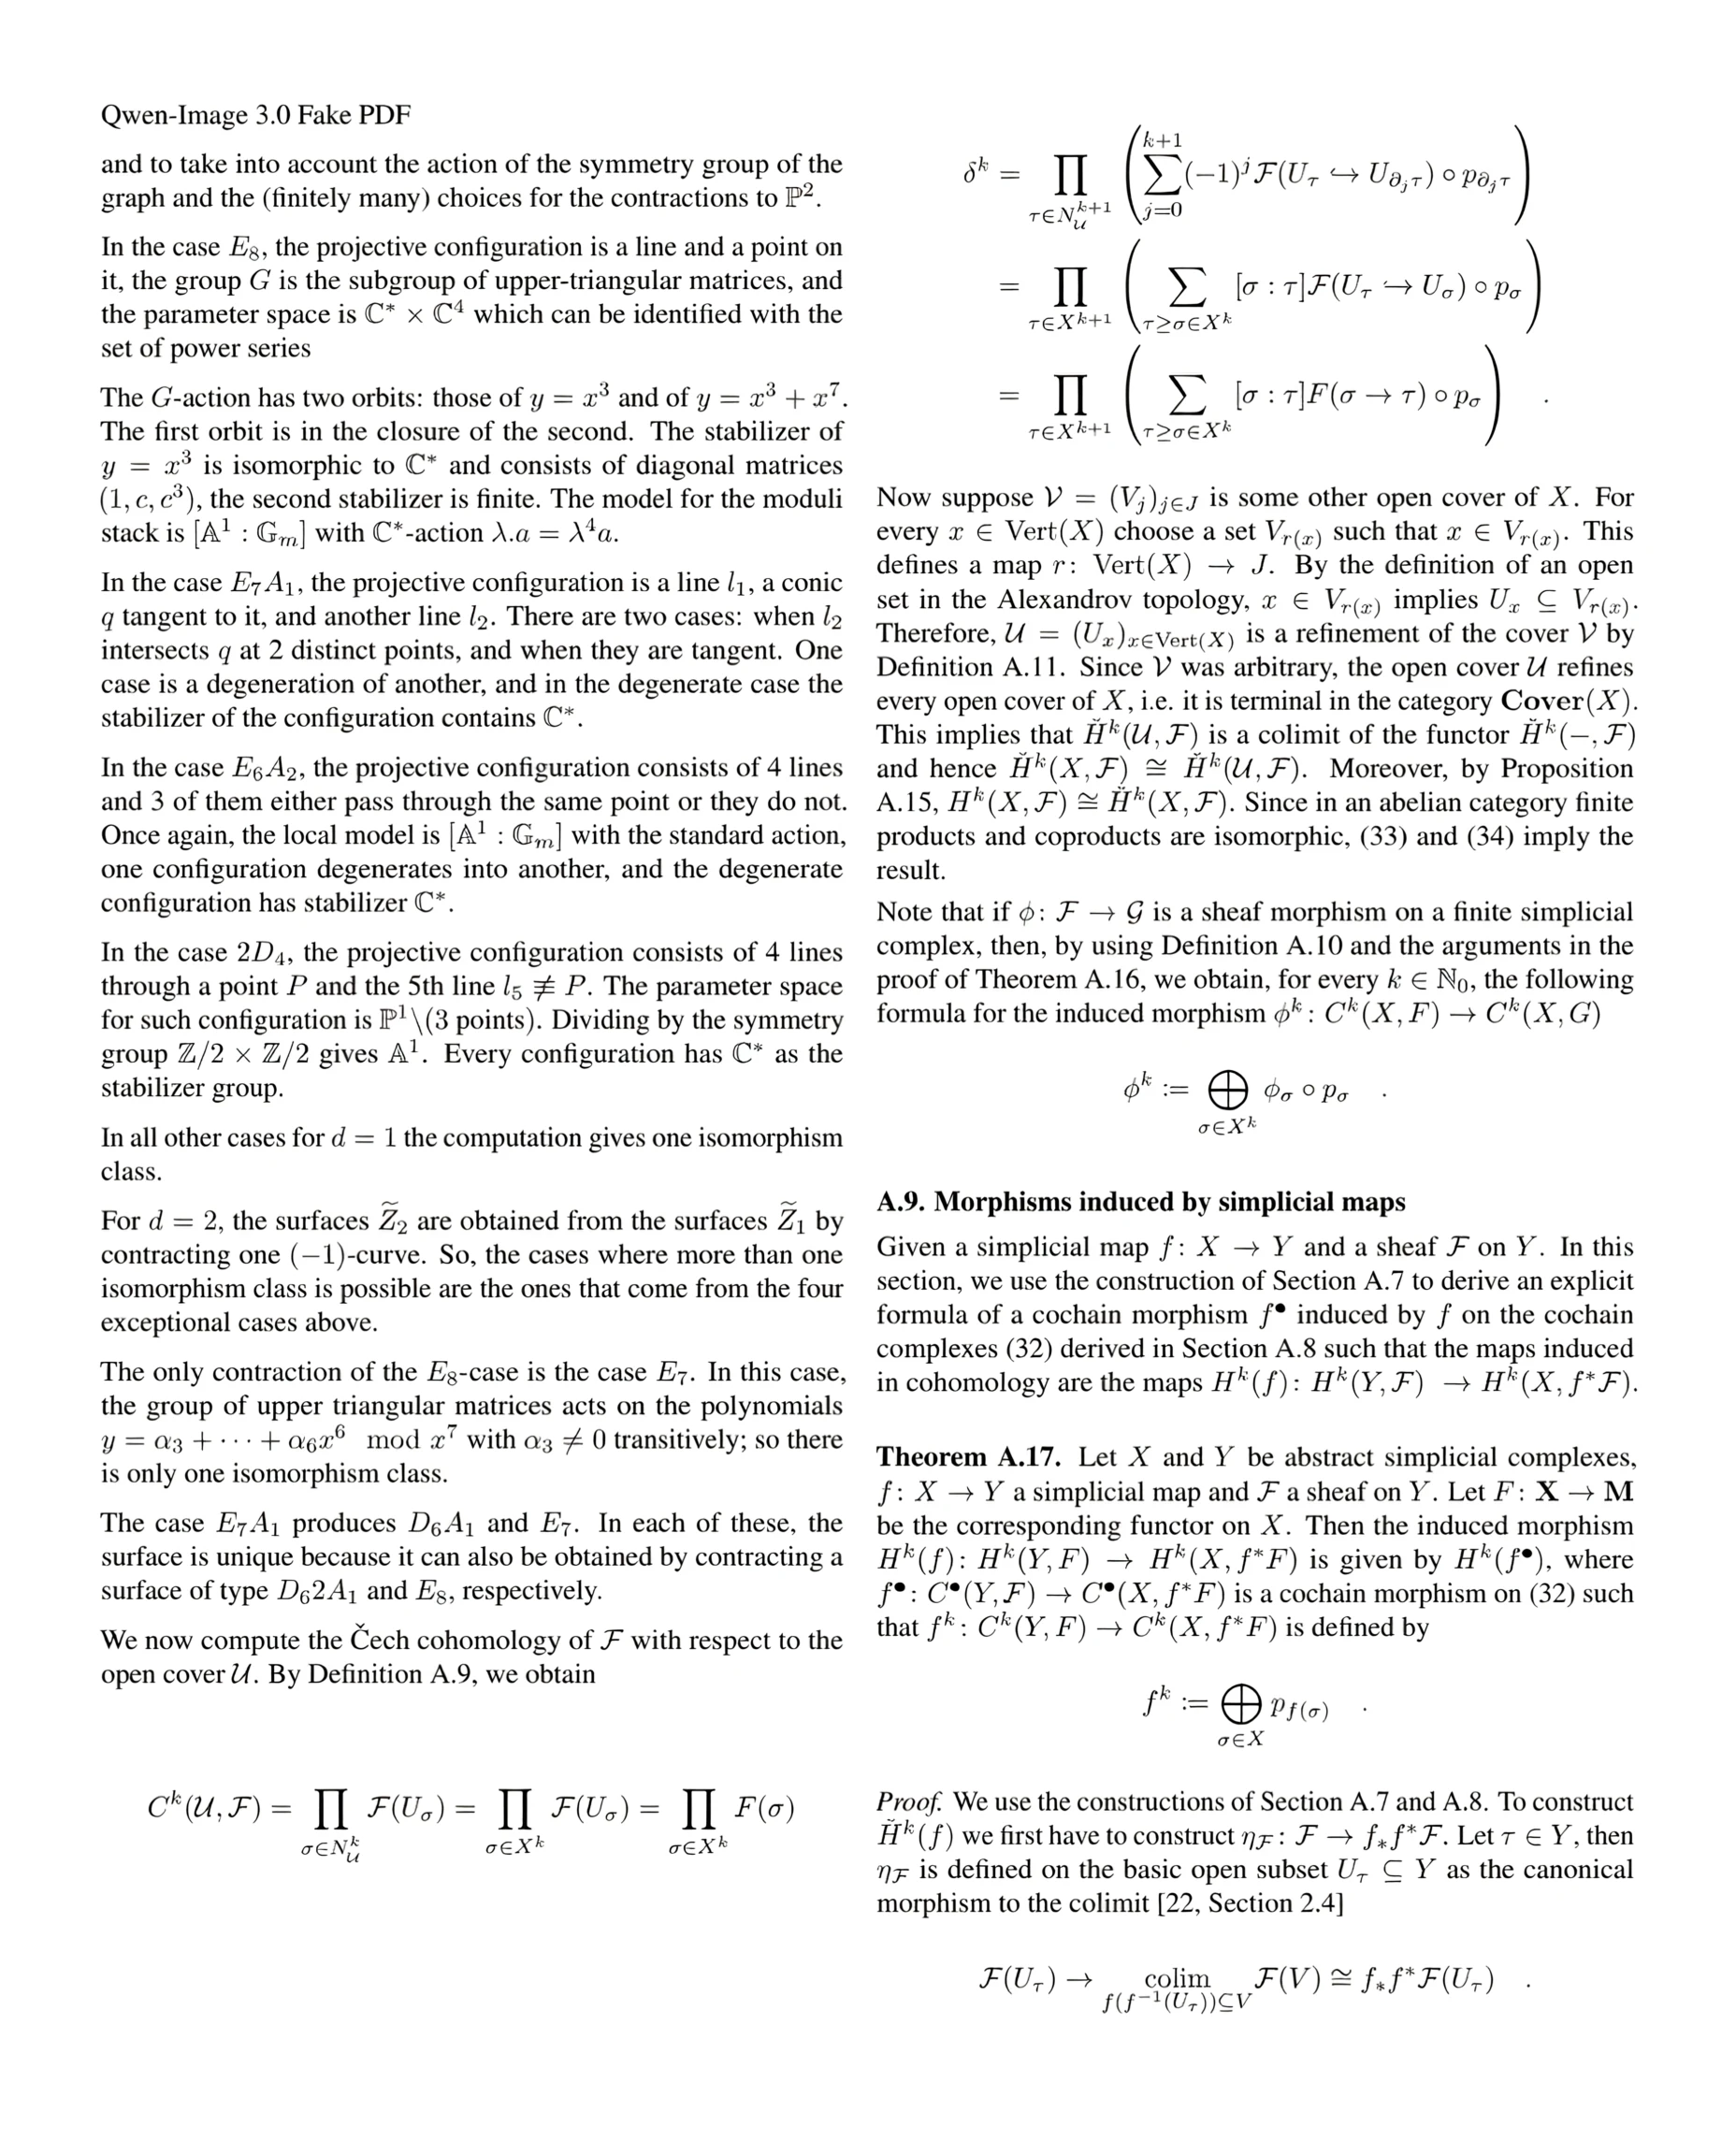
Small-text precision: dense mathematical prose, LaTeX formulas, superscripts, subscripts, and theorem notation.
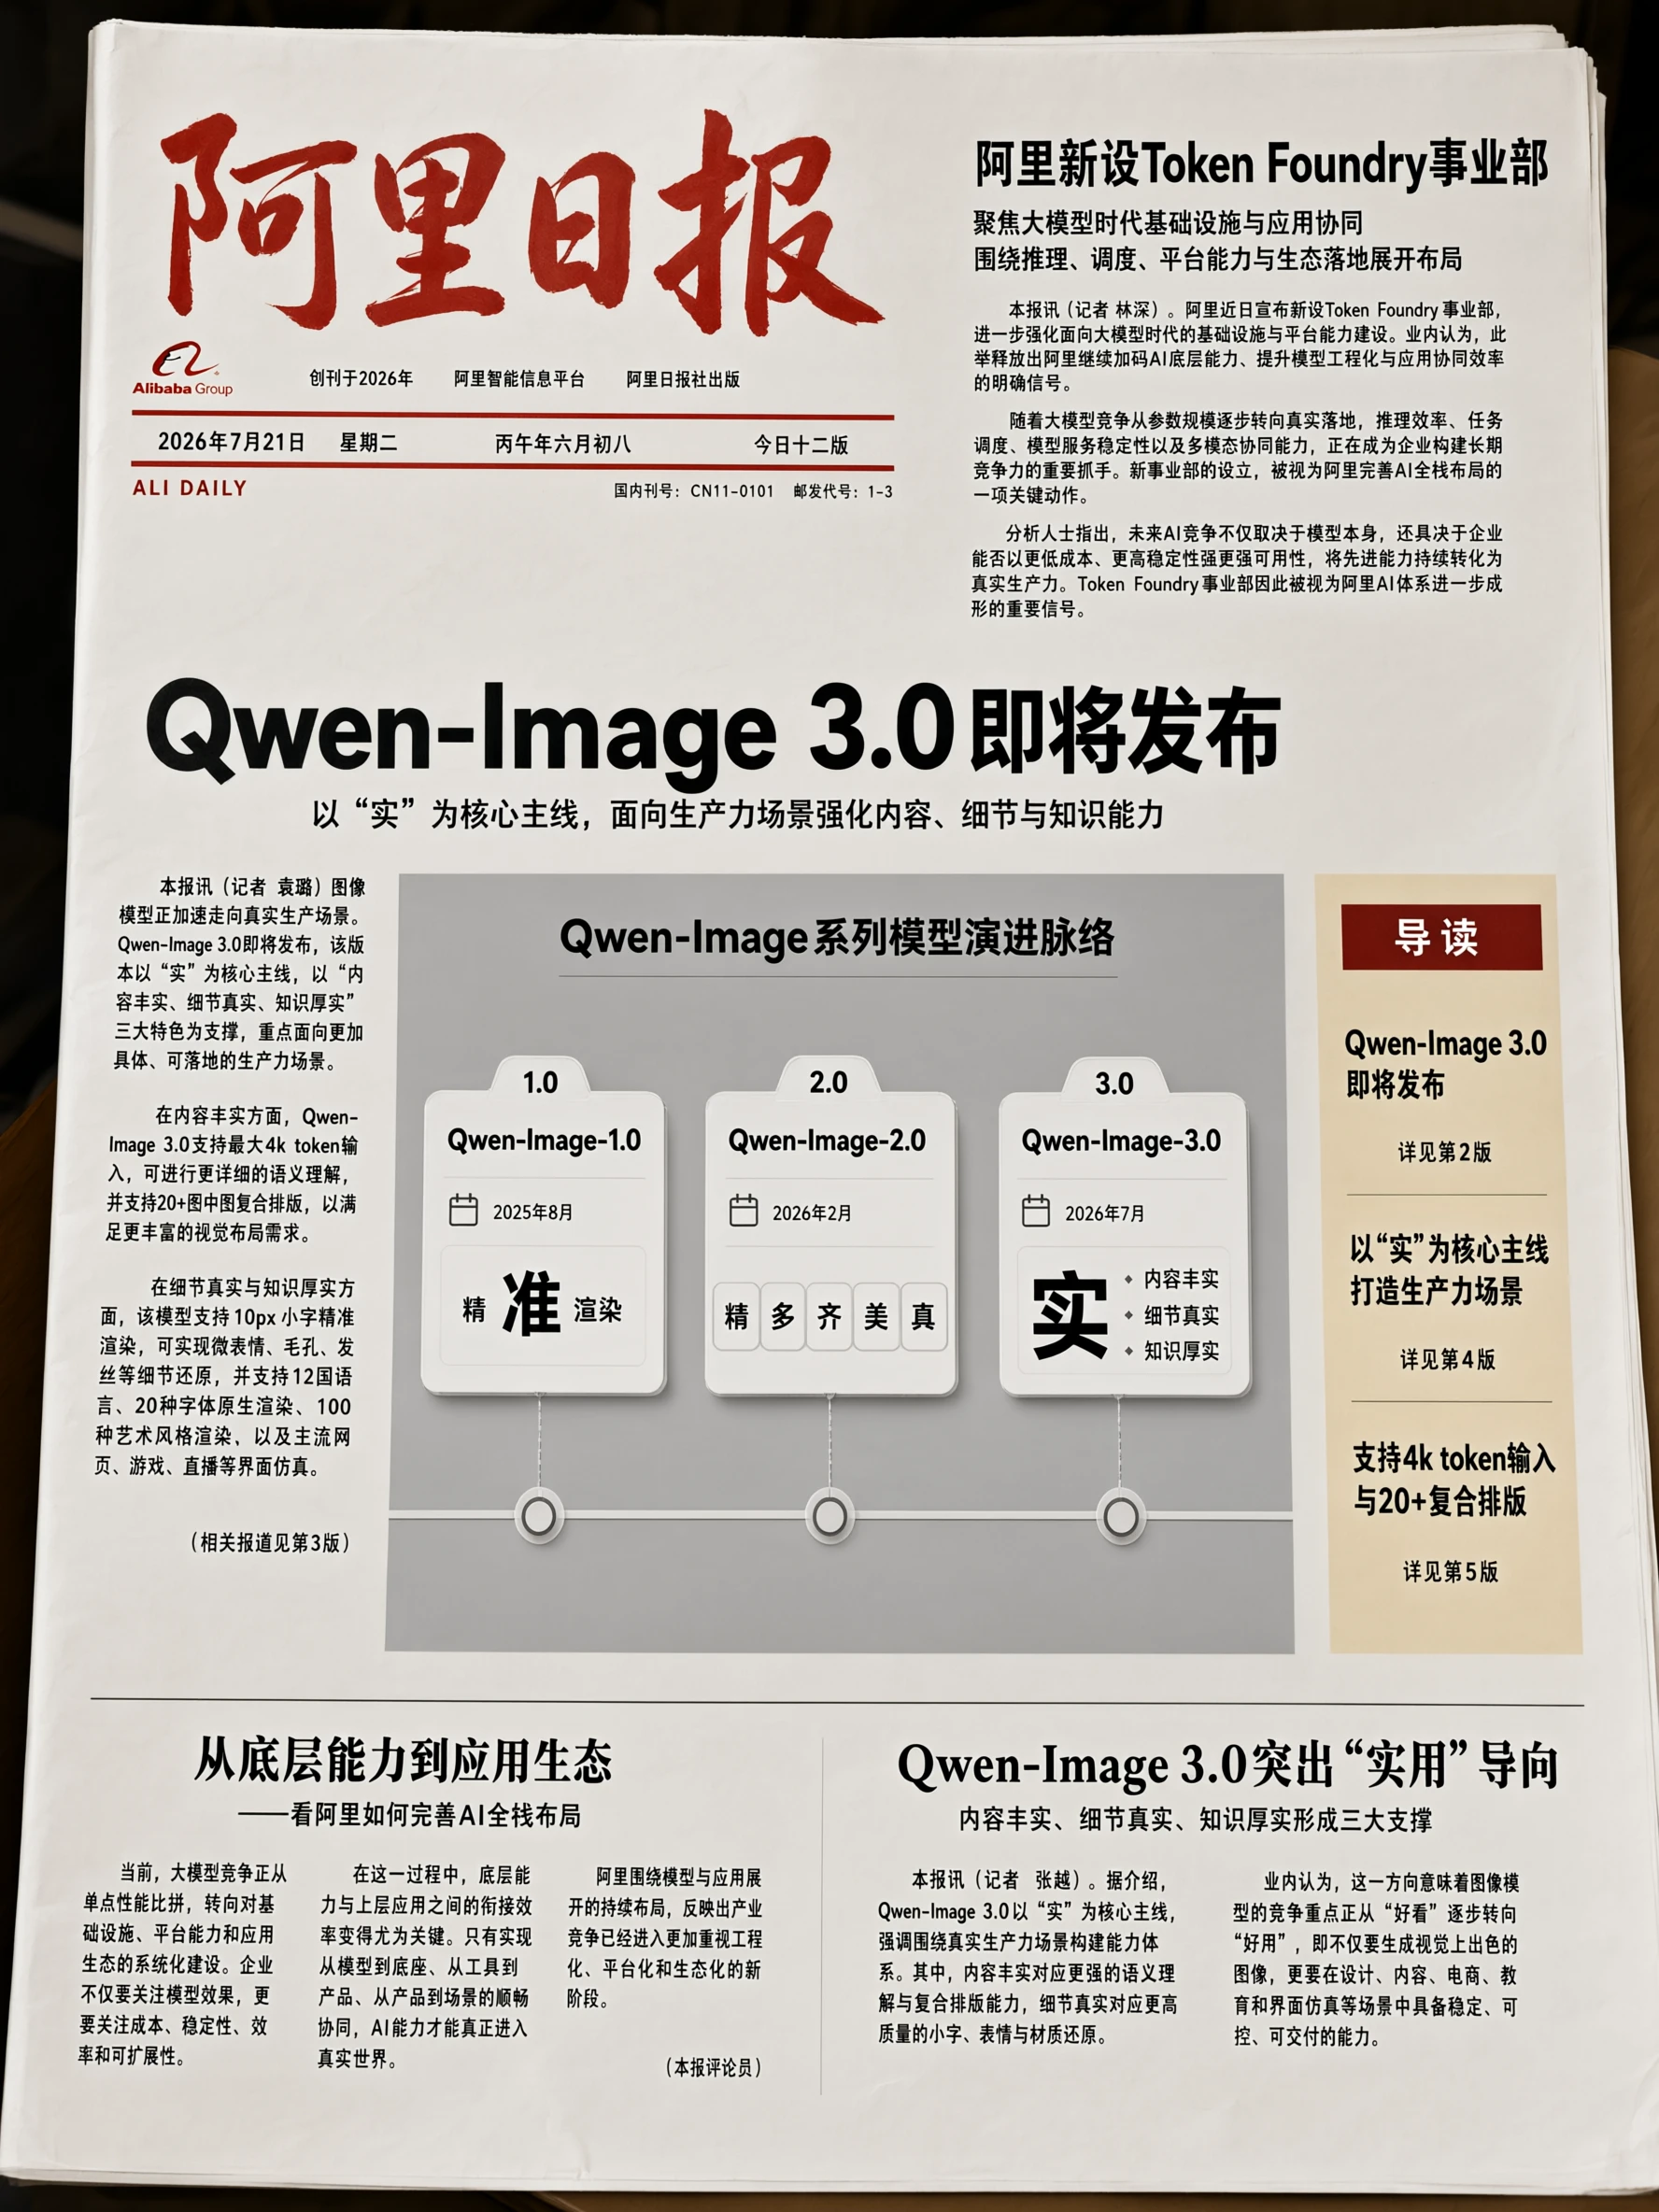
A realistic newspaper page demonstrates dense typography, editorial hierarchy, and practical production layouts.
Original page
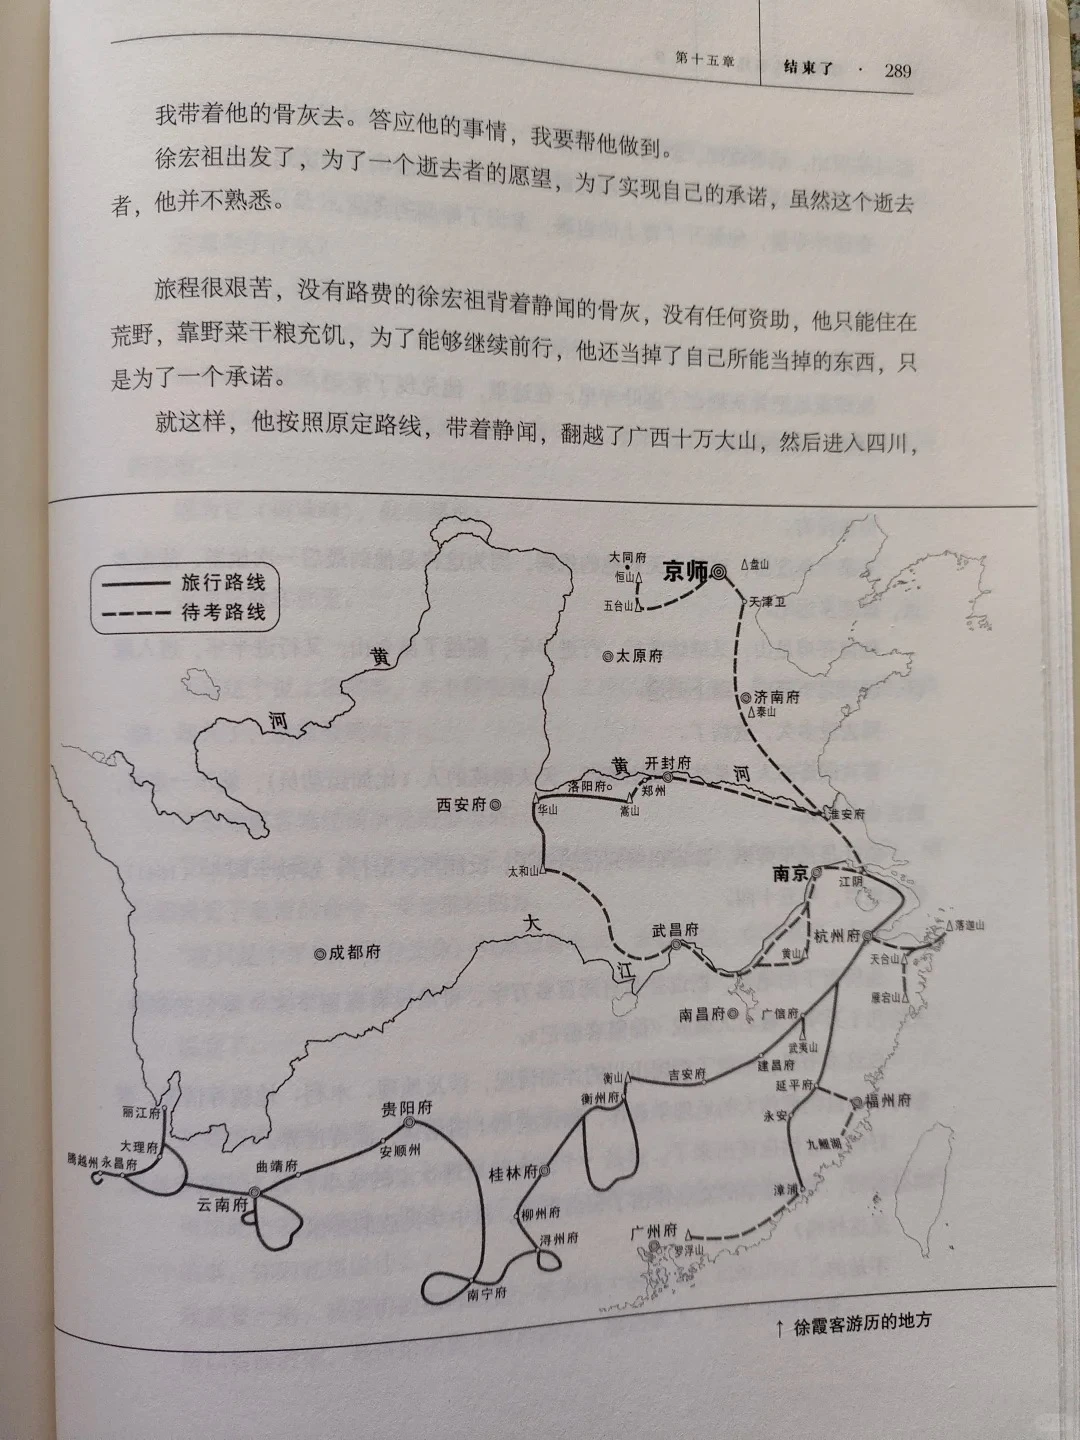
Edited with handwritten annotations
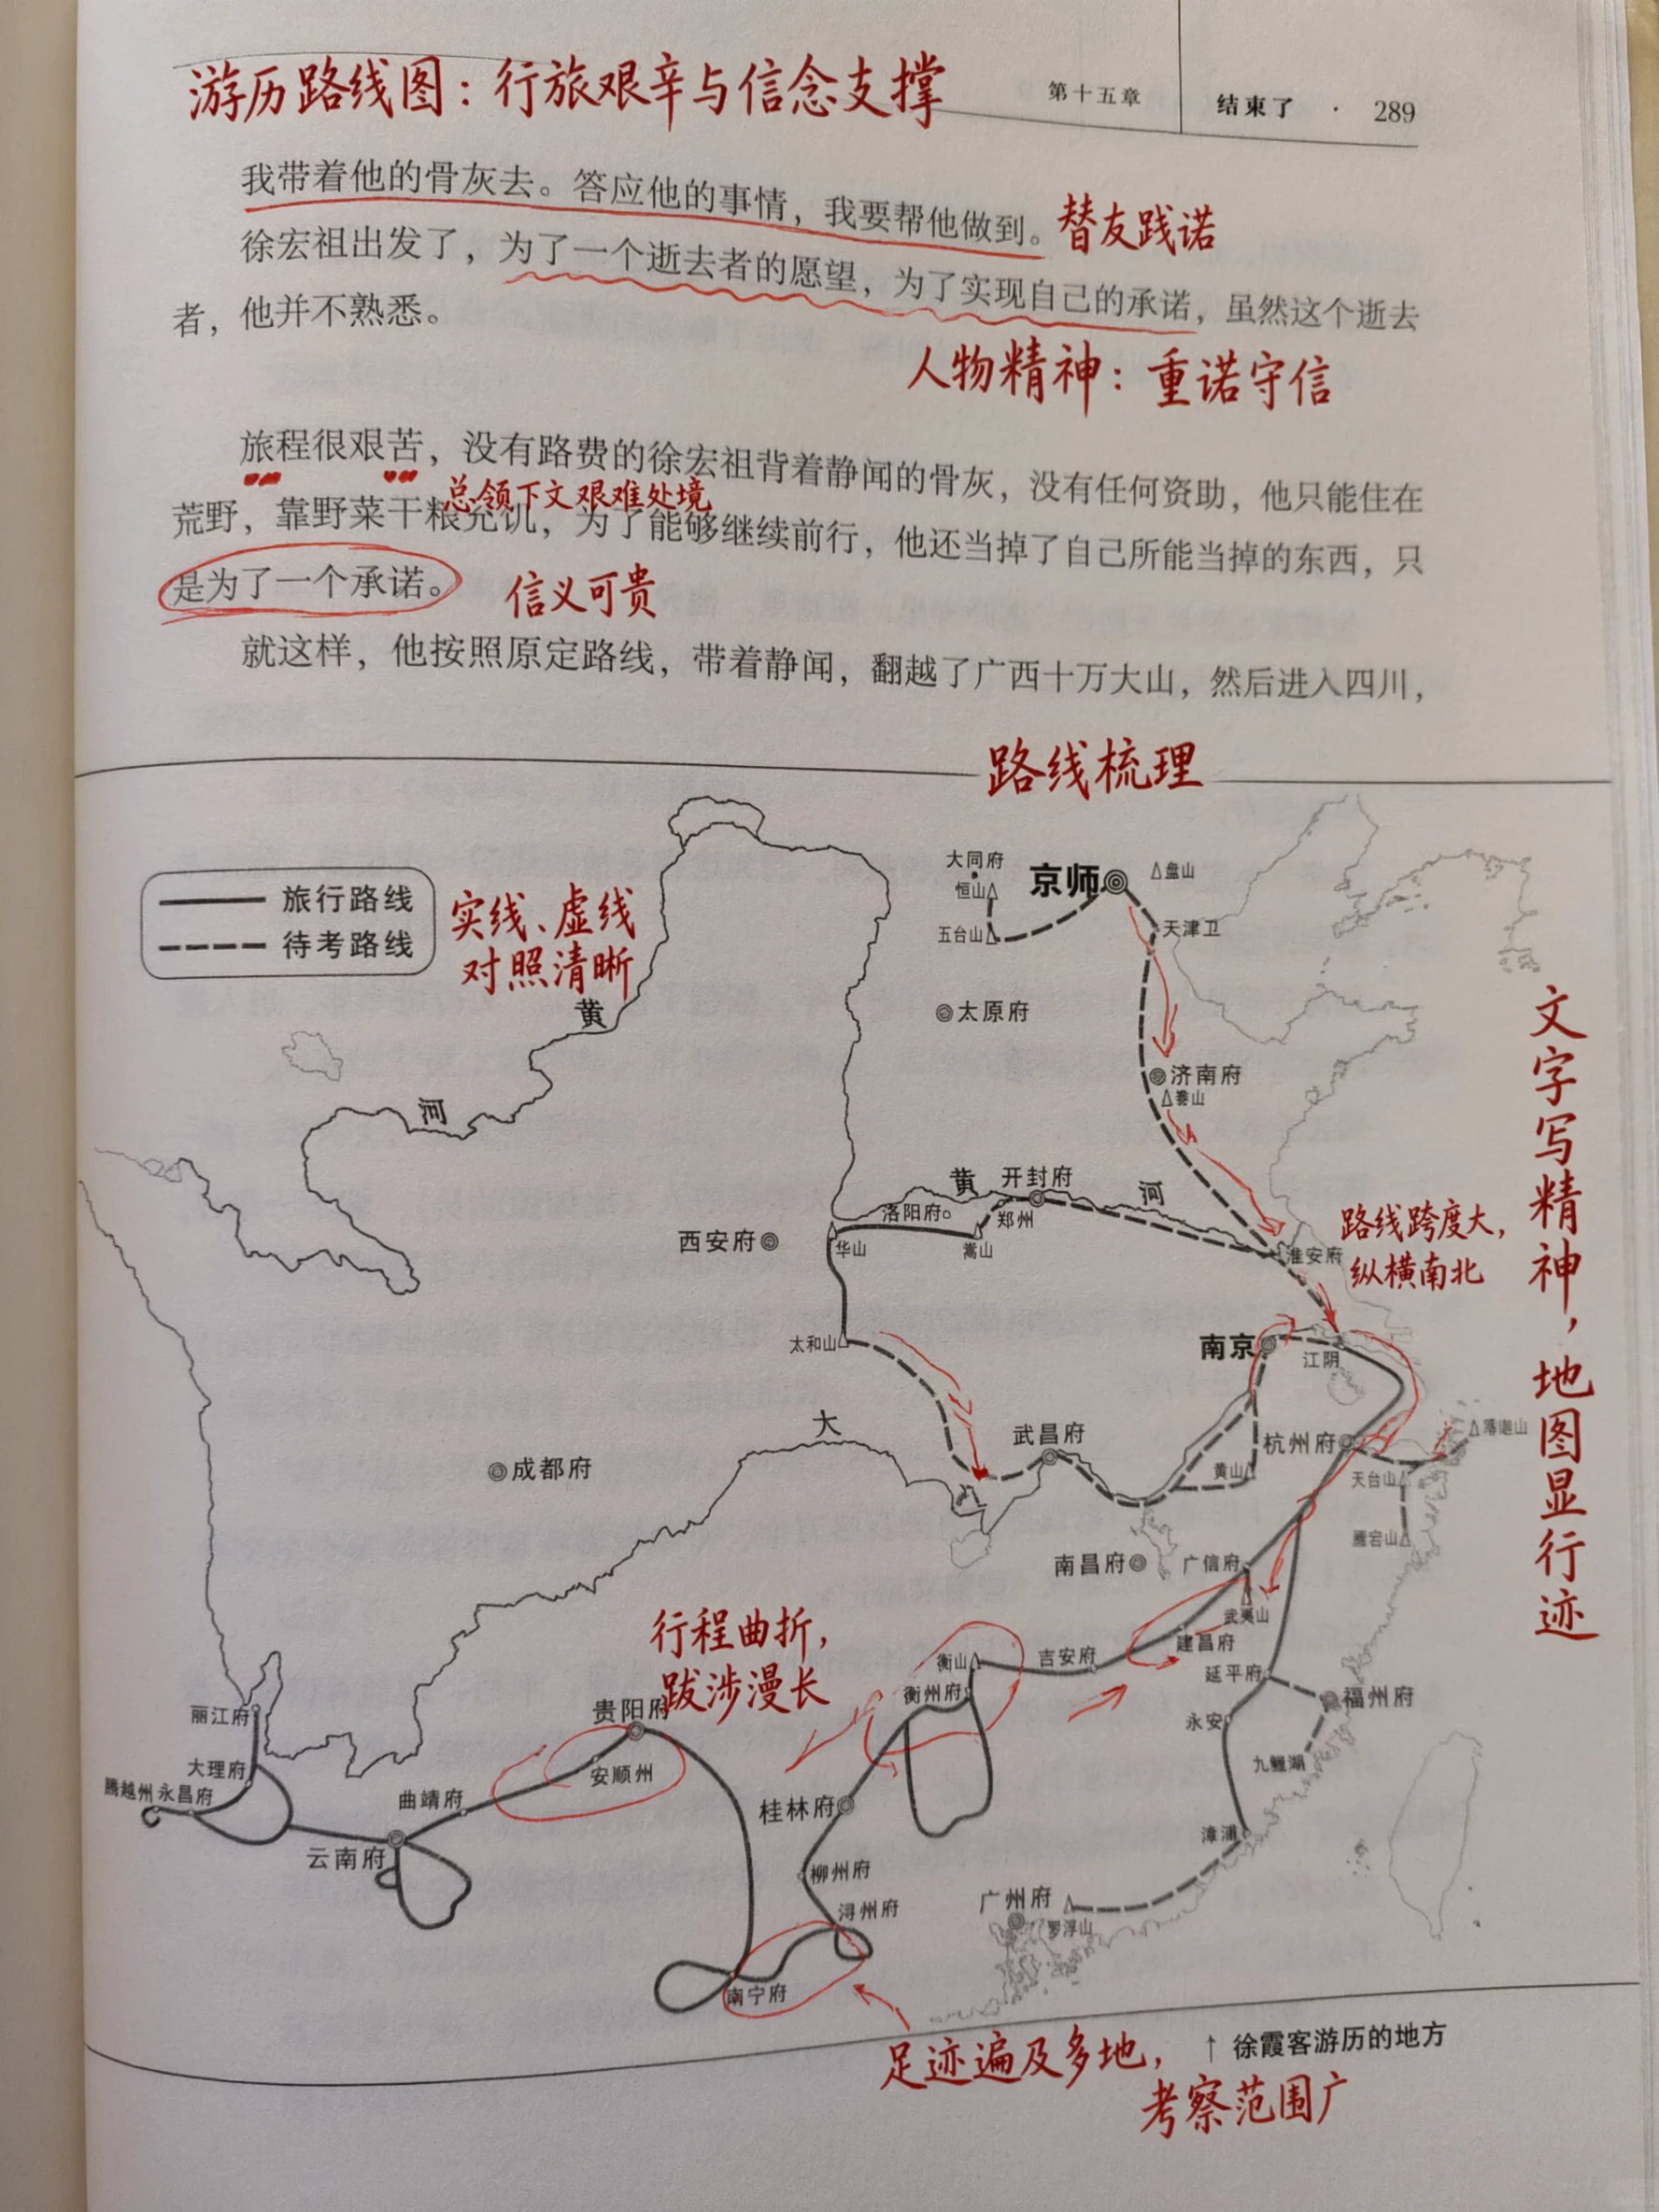
Image editing example: Qwen-Image 3.0 adds natural red handwritten annotations, underlines, circles, arrows, and route analysis while preserving the original page.
World knowledge and interface rendering: a structured visual design with multilingual content and UI-like composition.
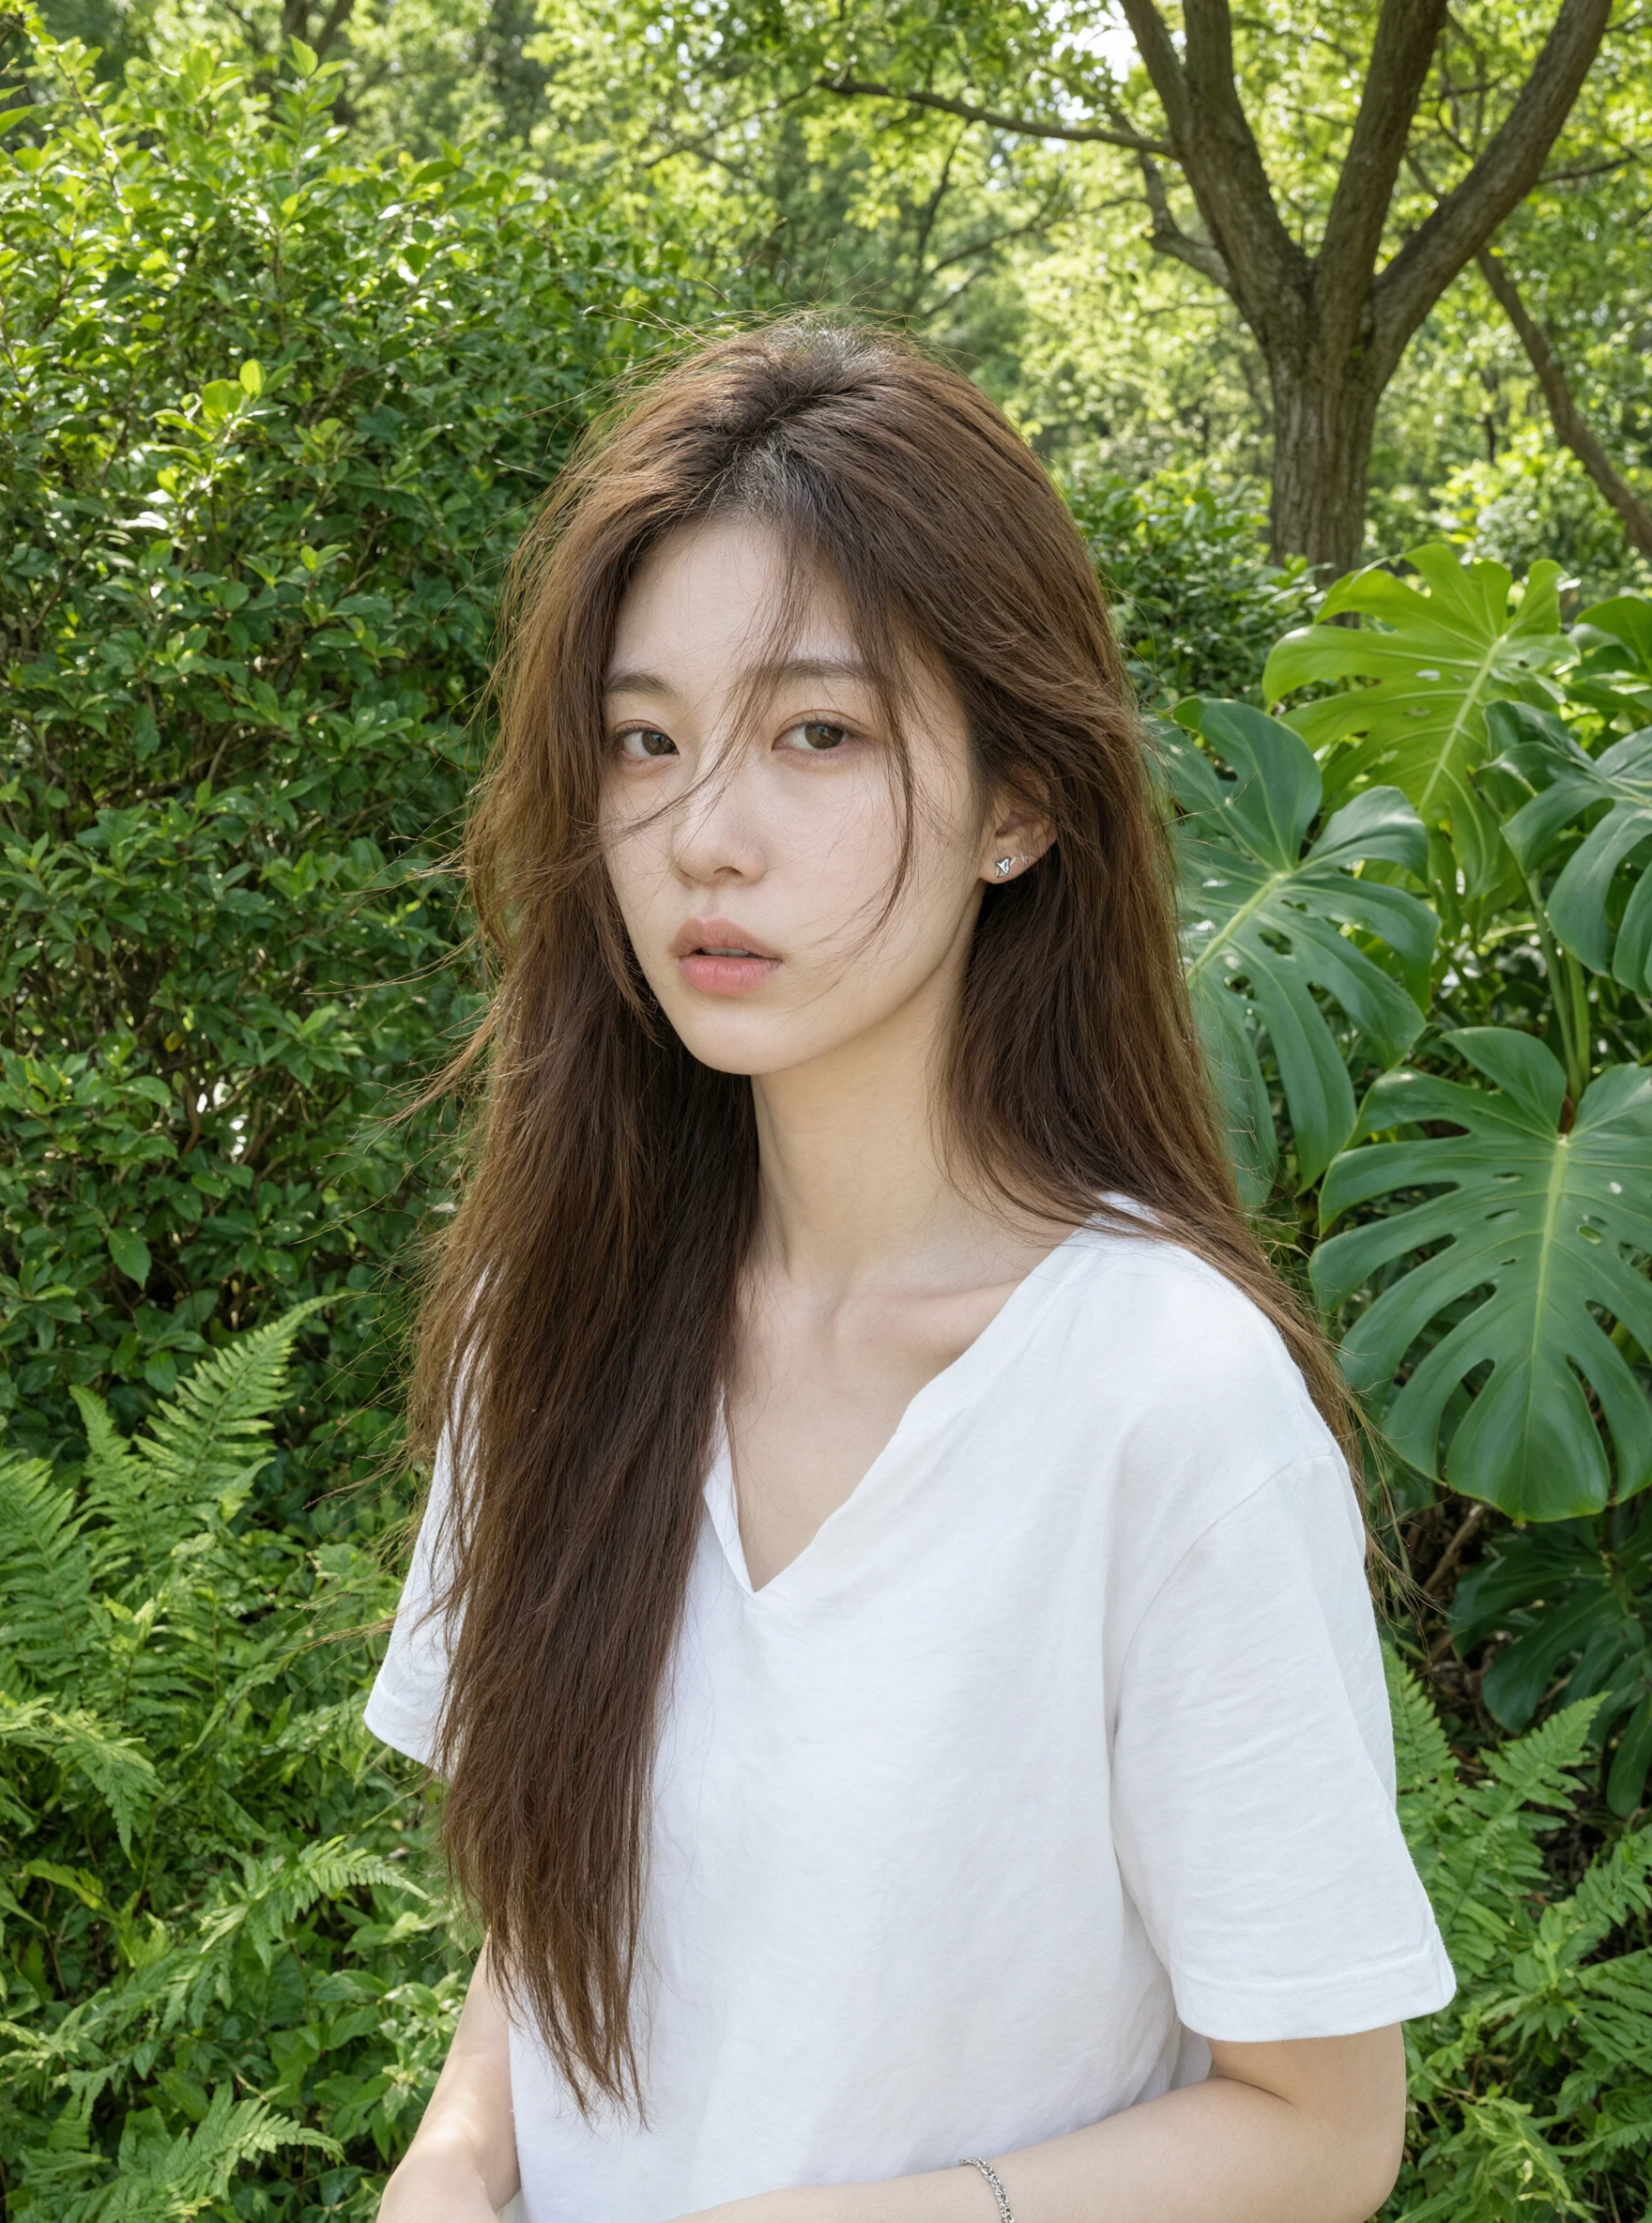
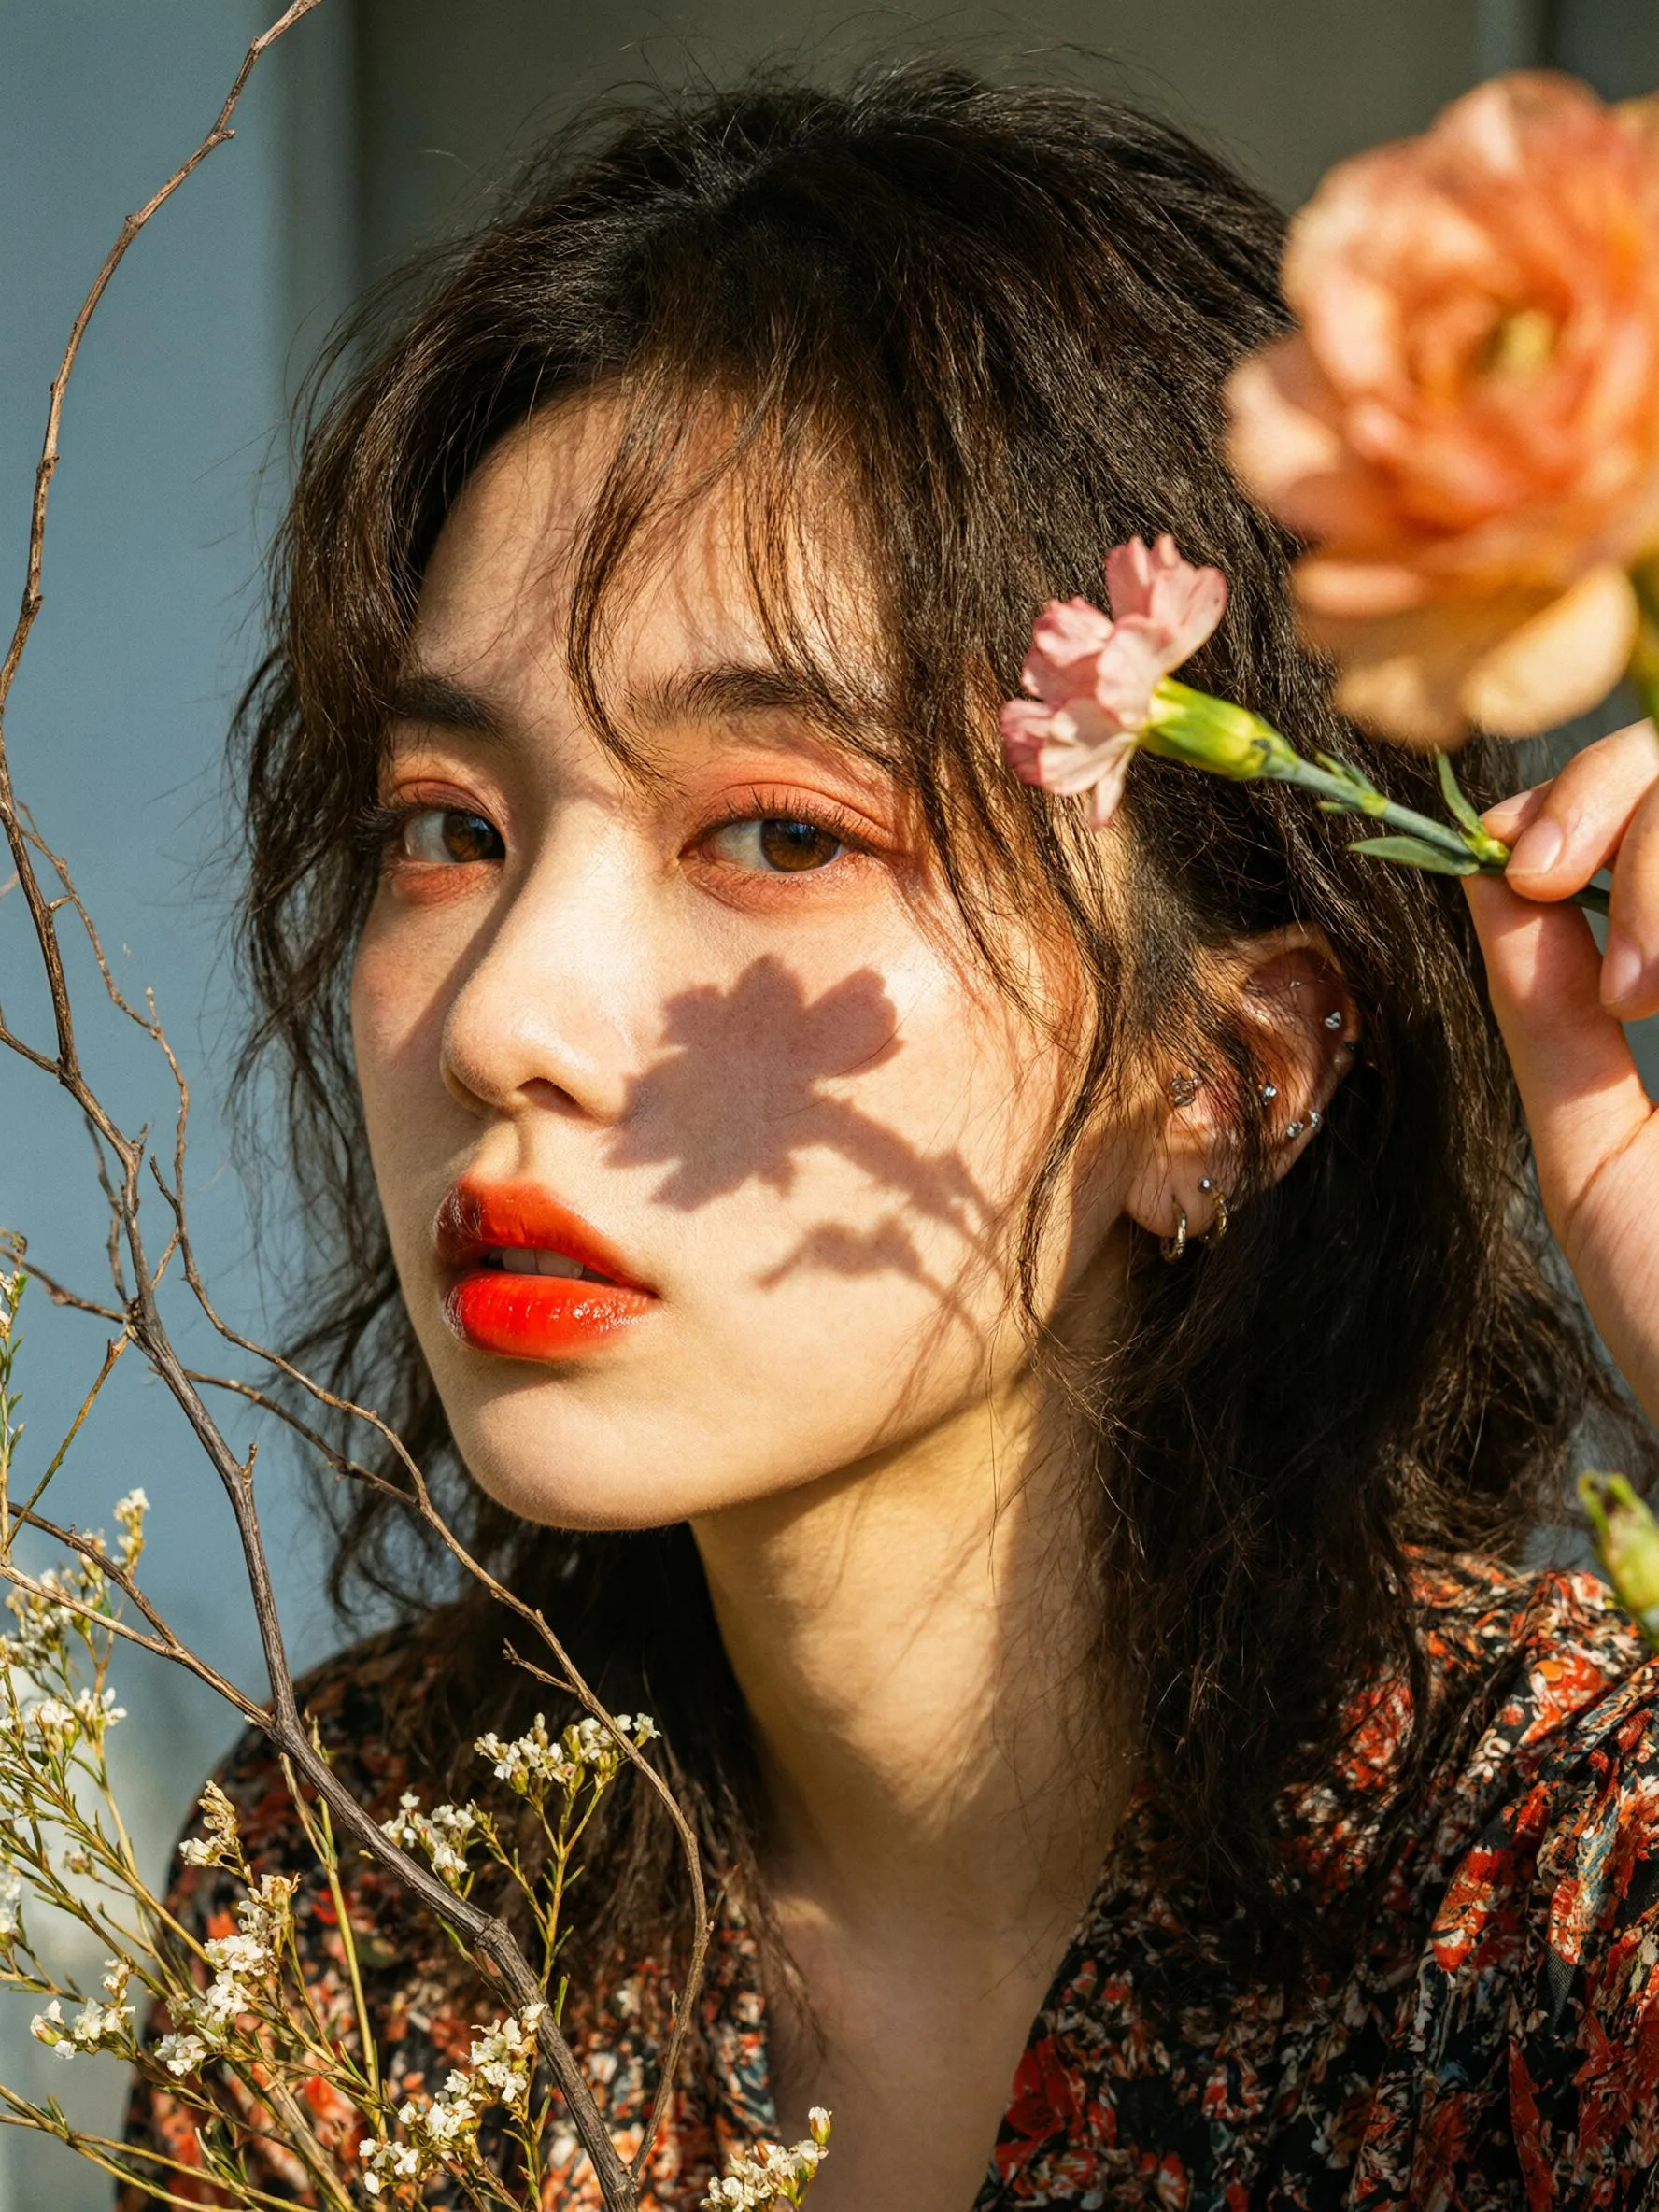
Authentic details: portrait, hair, skin, and material textures rendered with fine-grained visual detail.
Damaged painting
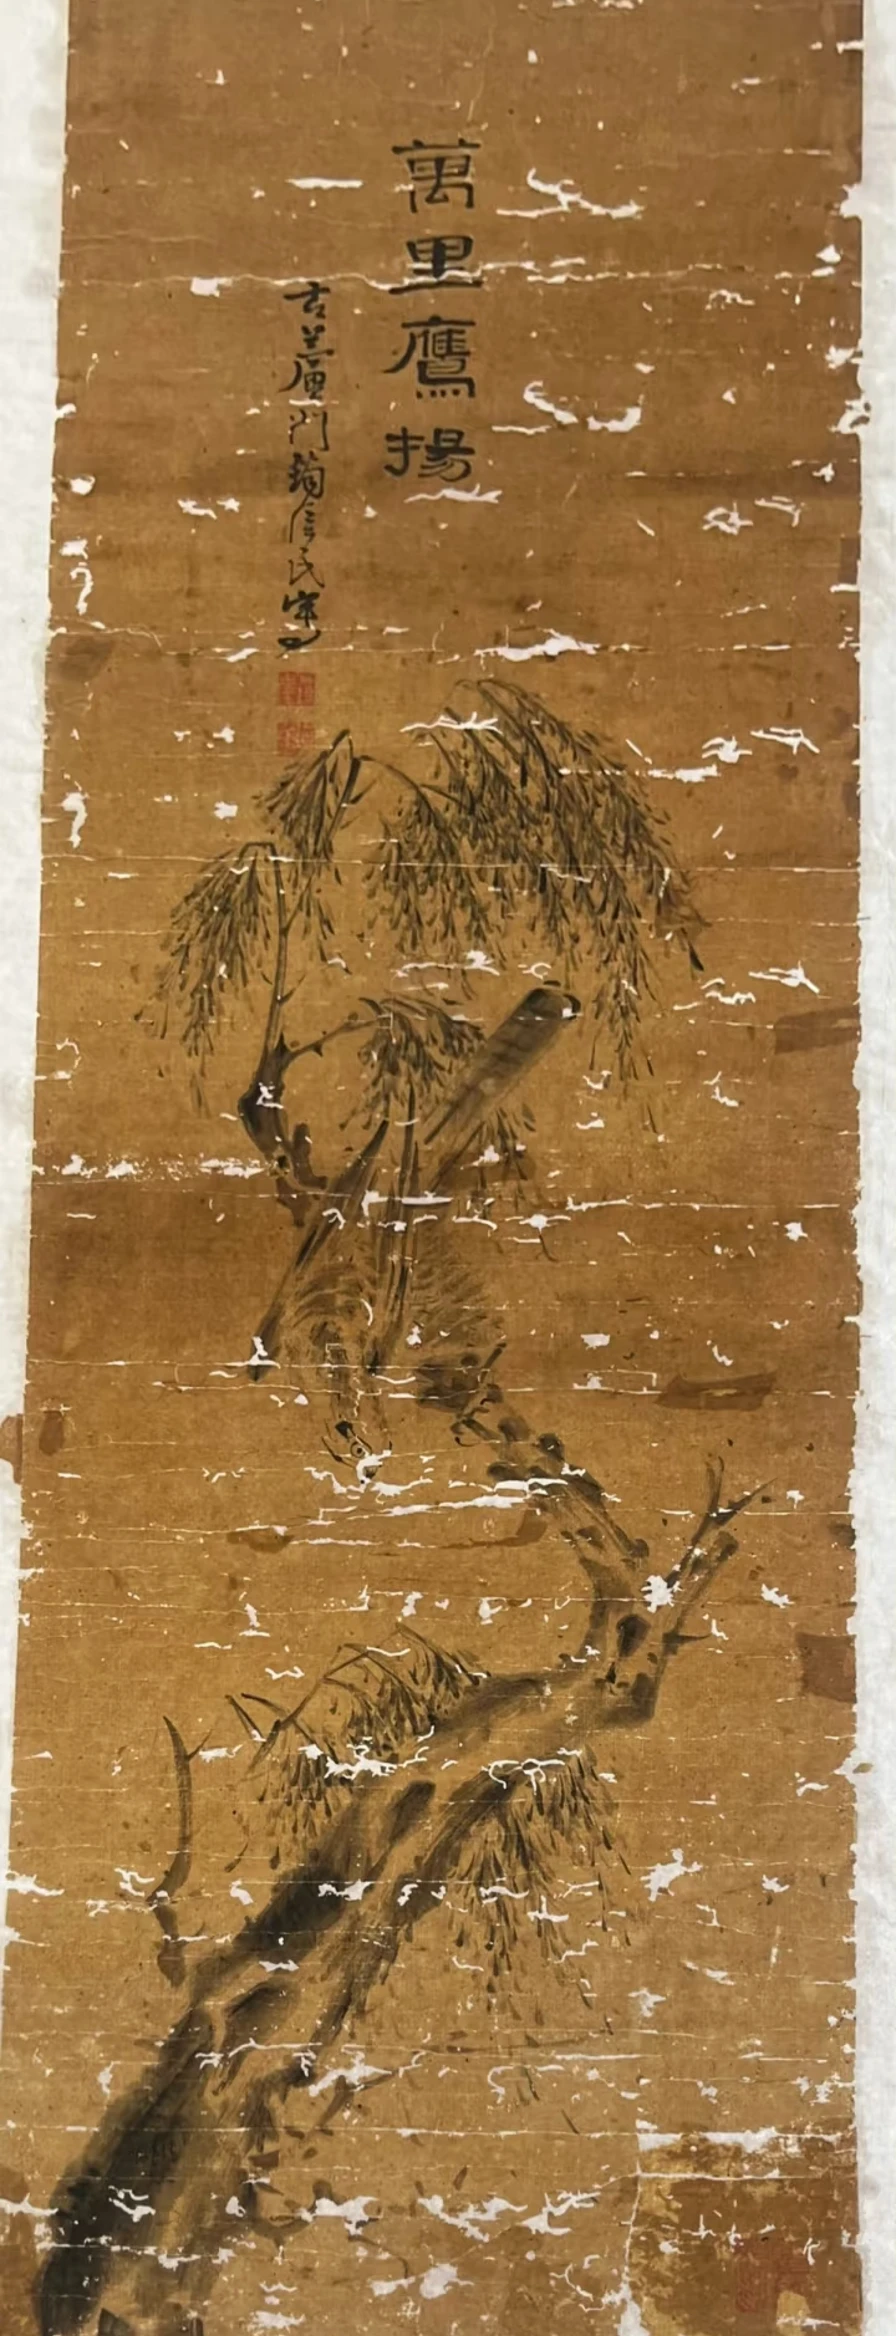
Restored painting
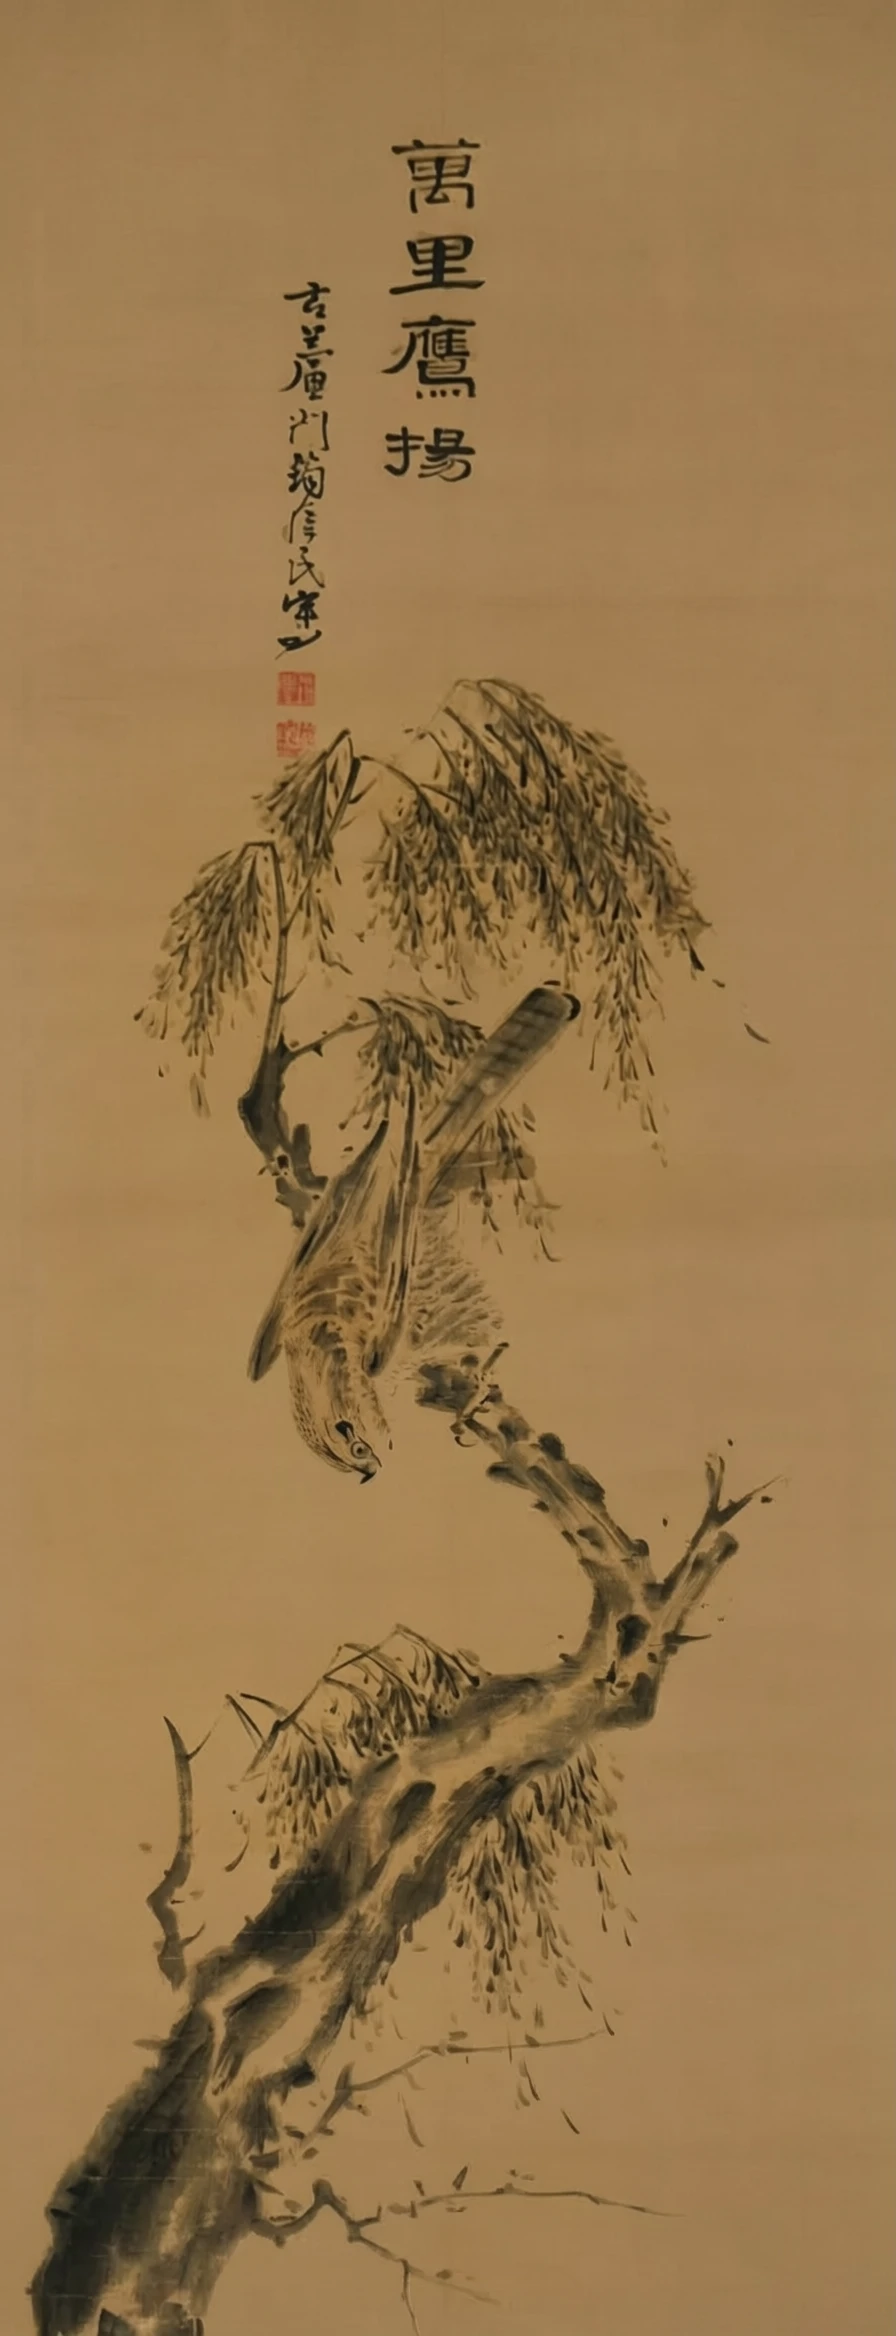
Restoration example: missing and damaged areas are repaired while the original ink gradients, brushwork, composition, and traditional painting style are preserved.
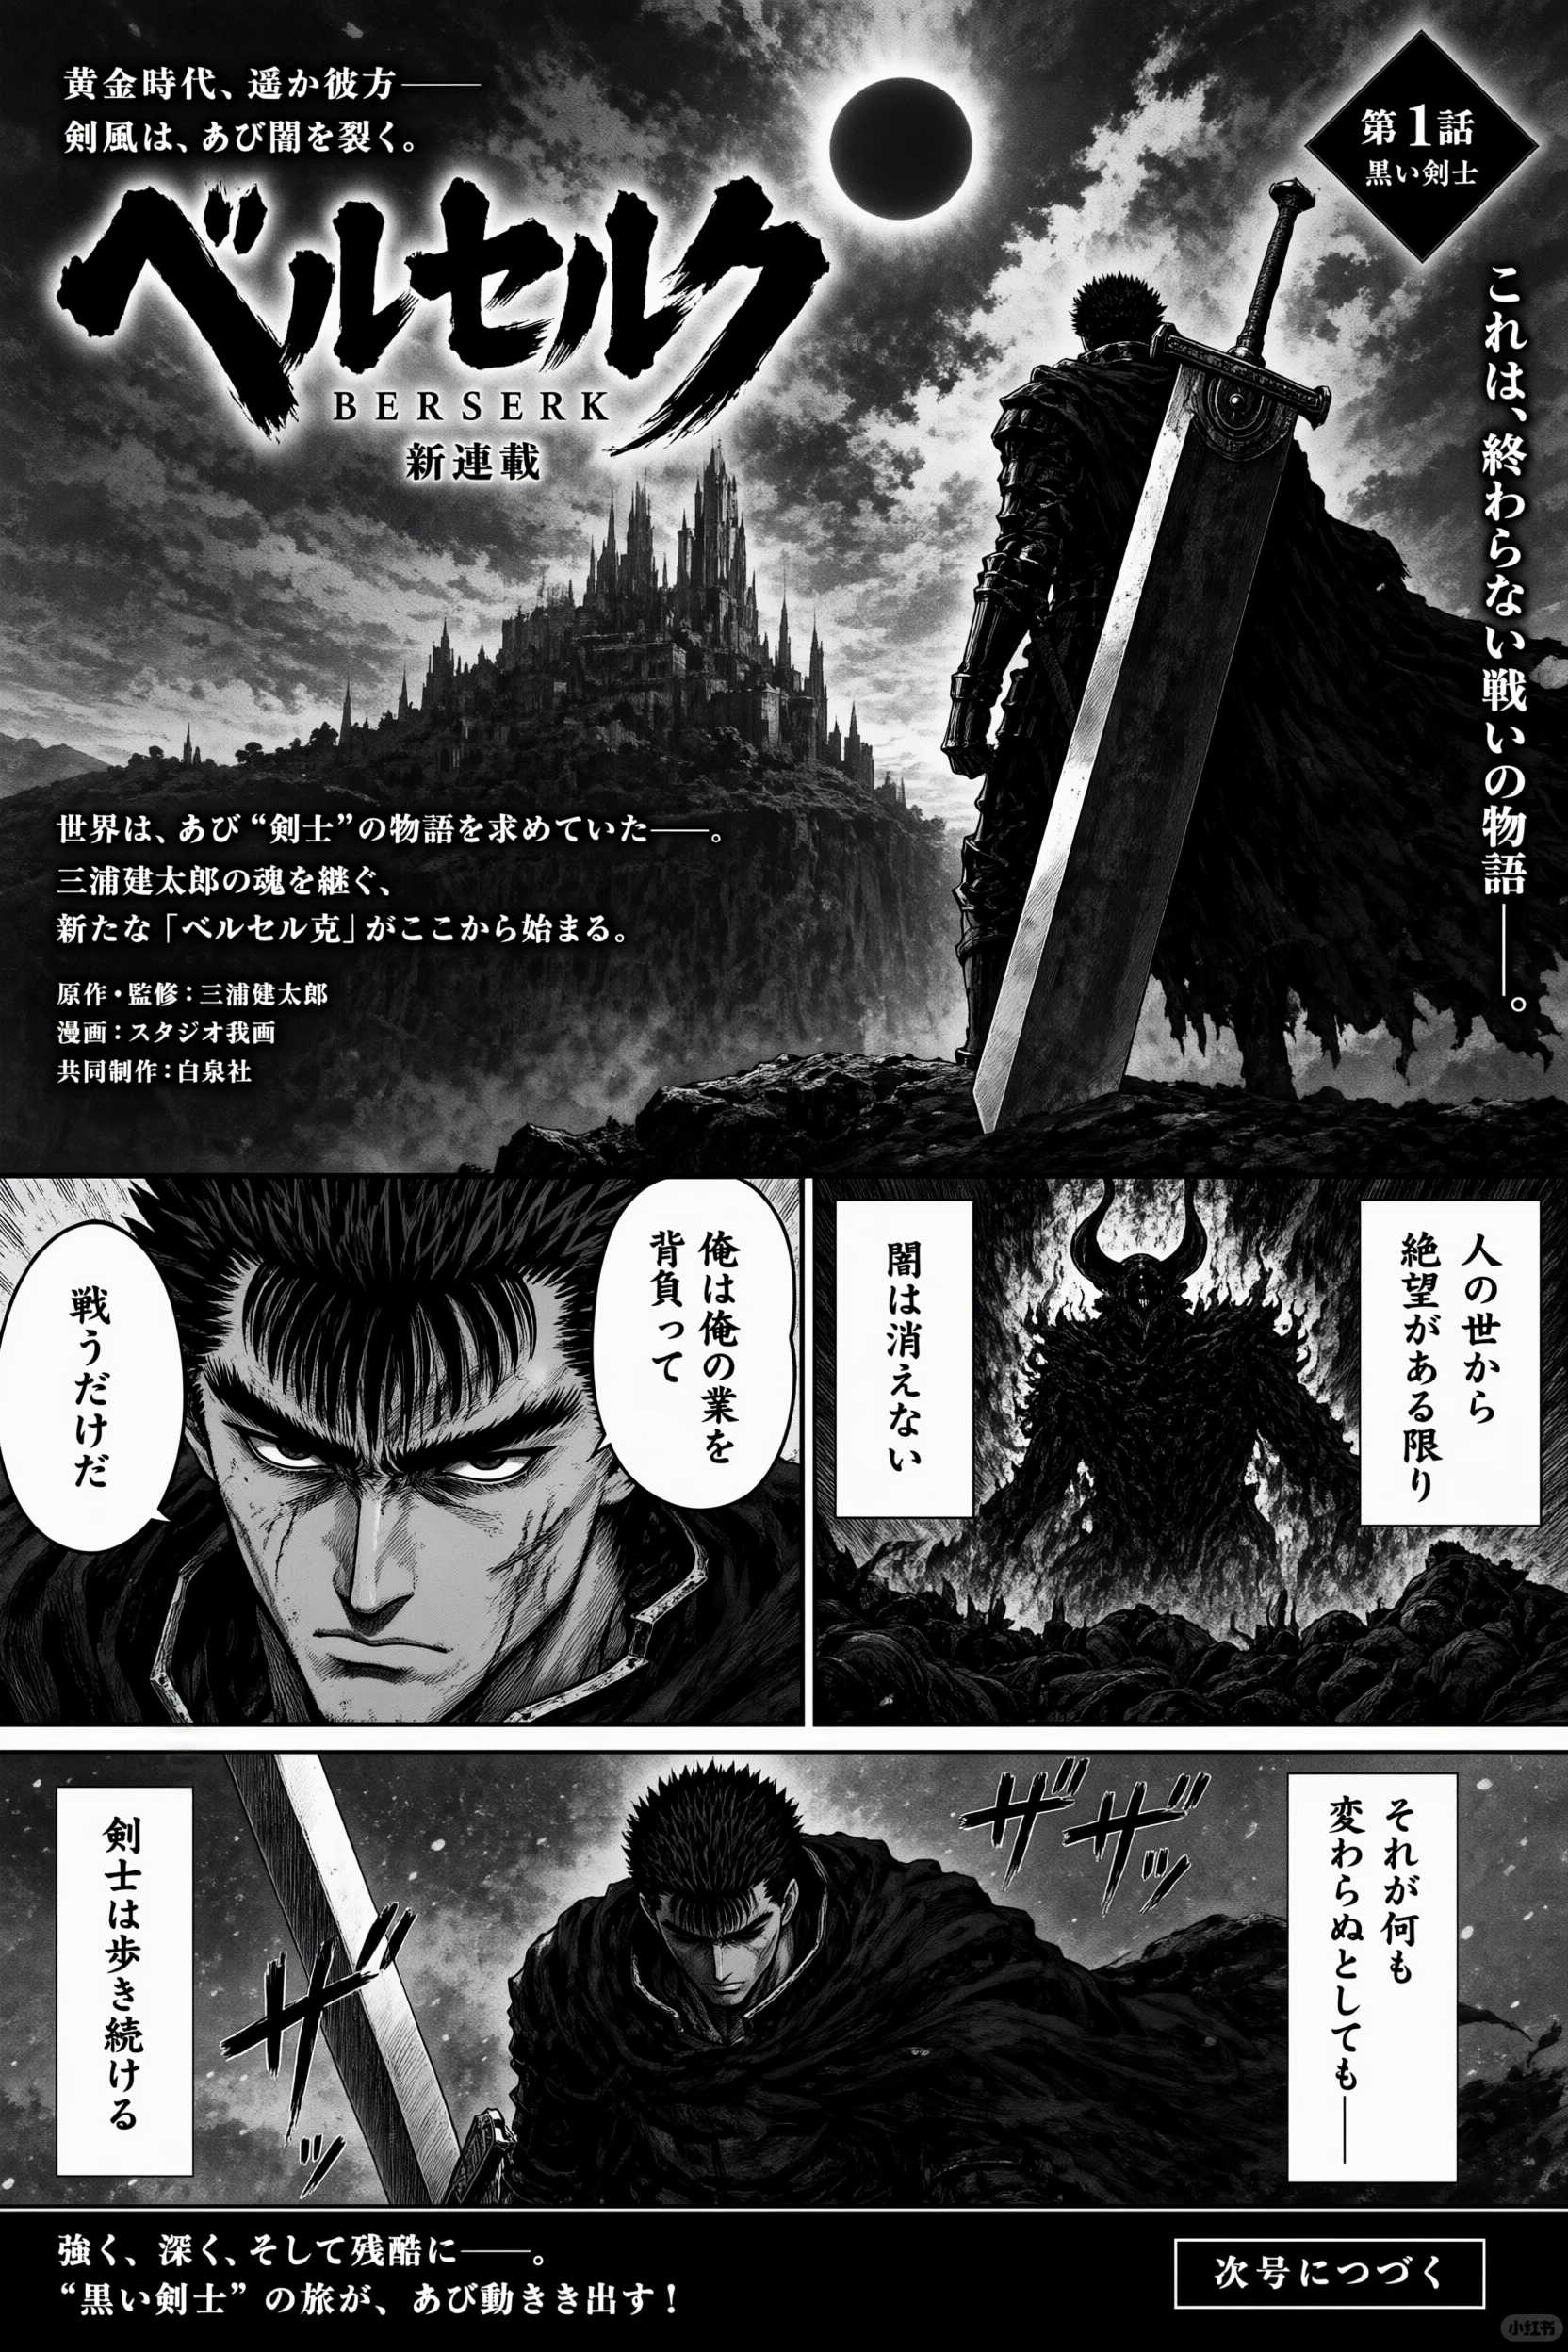
Style and layout knowledge: a manga-style page combines cinematic panels, speech bubbles, Japanese typography, and consistent characters.
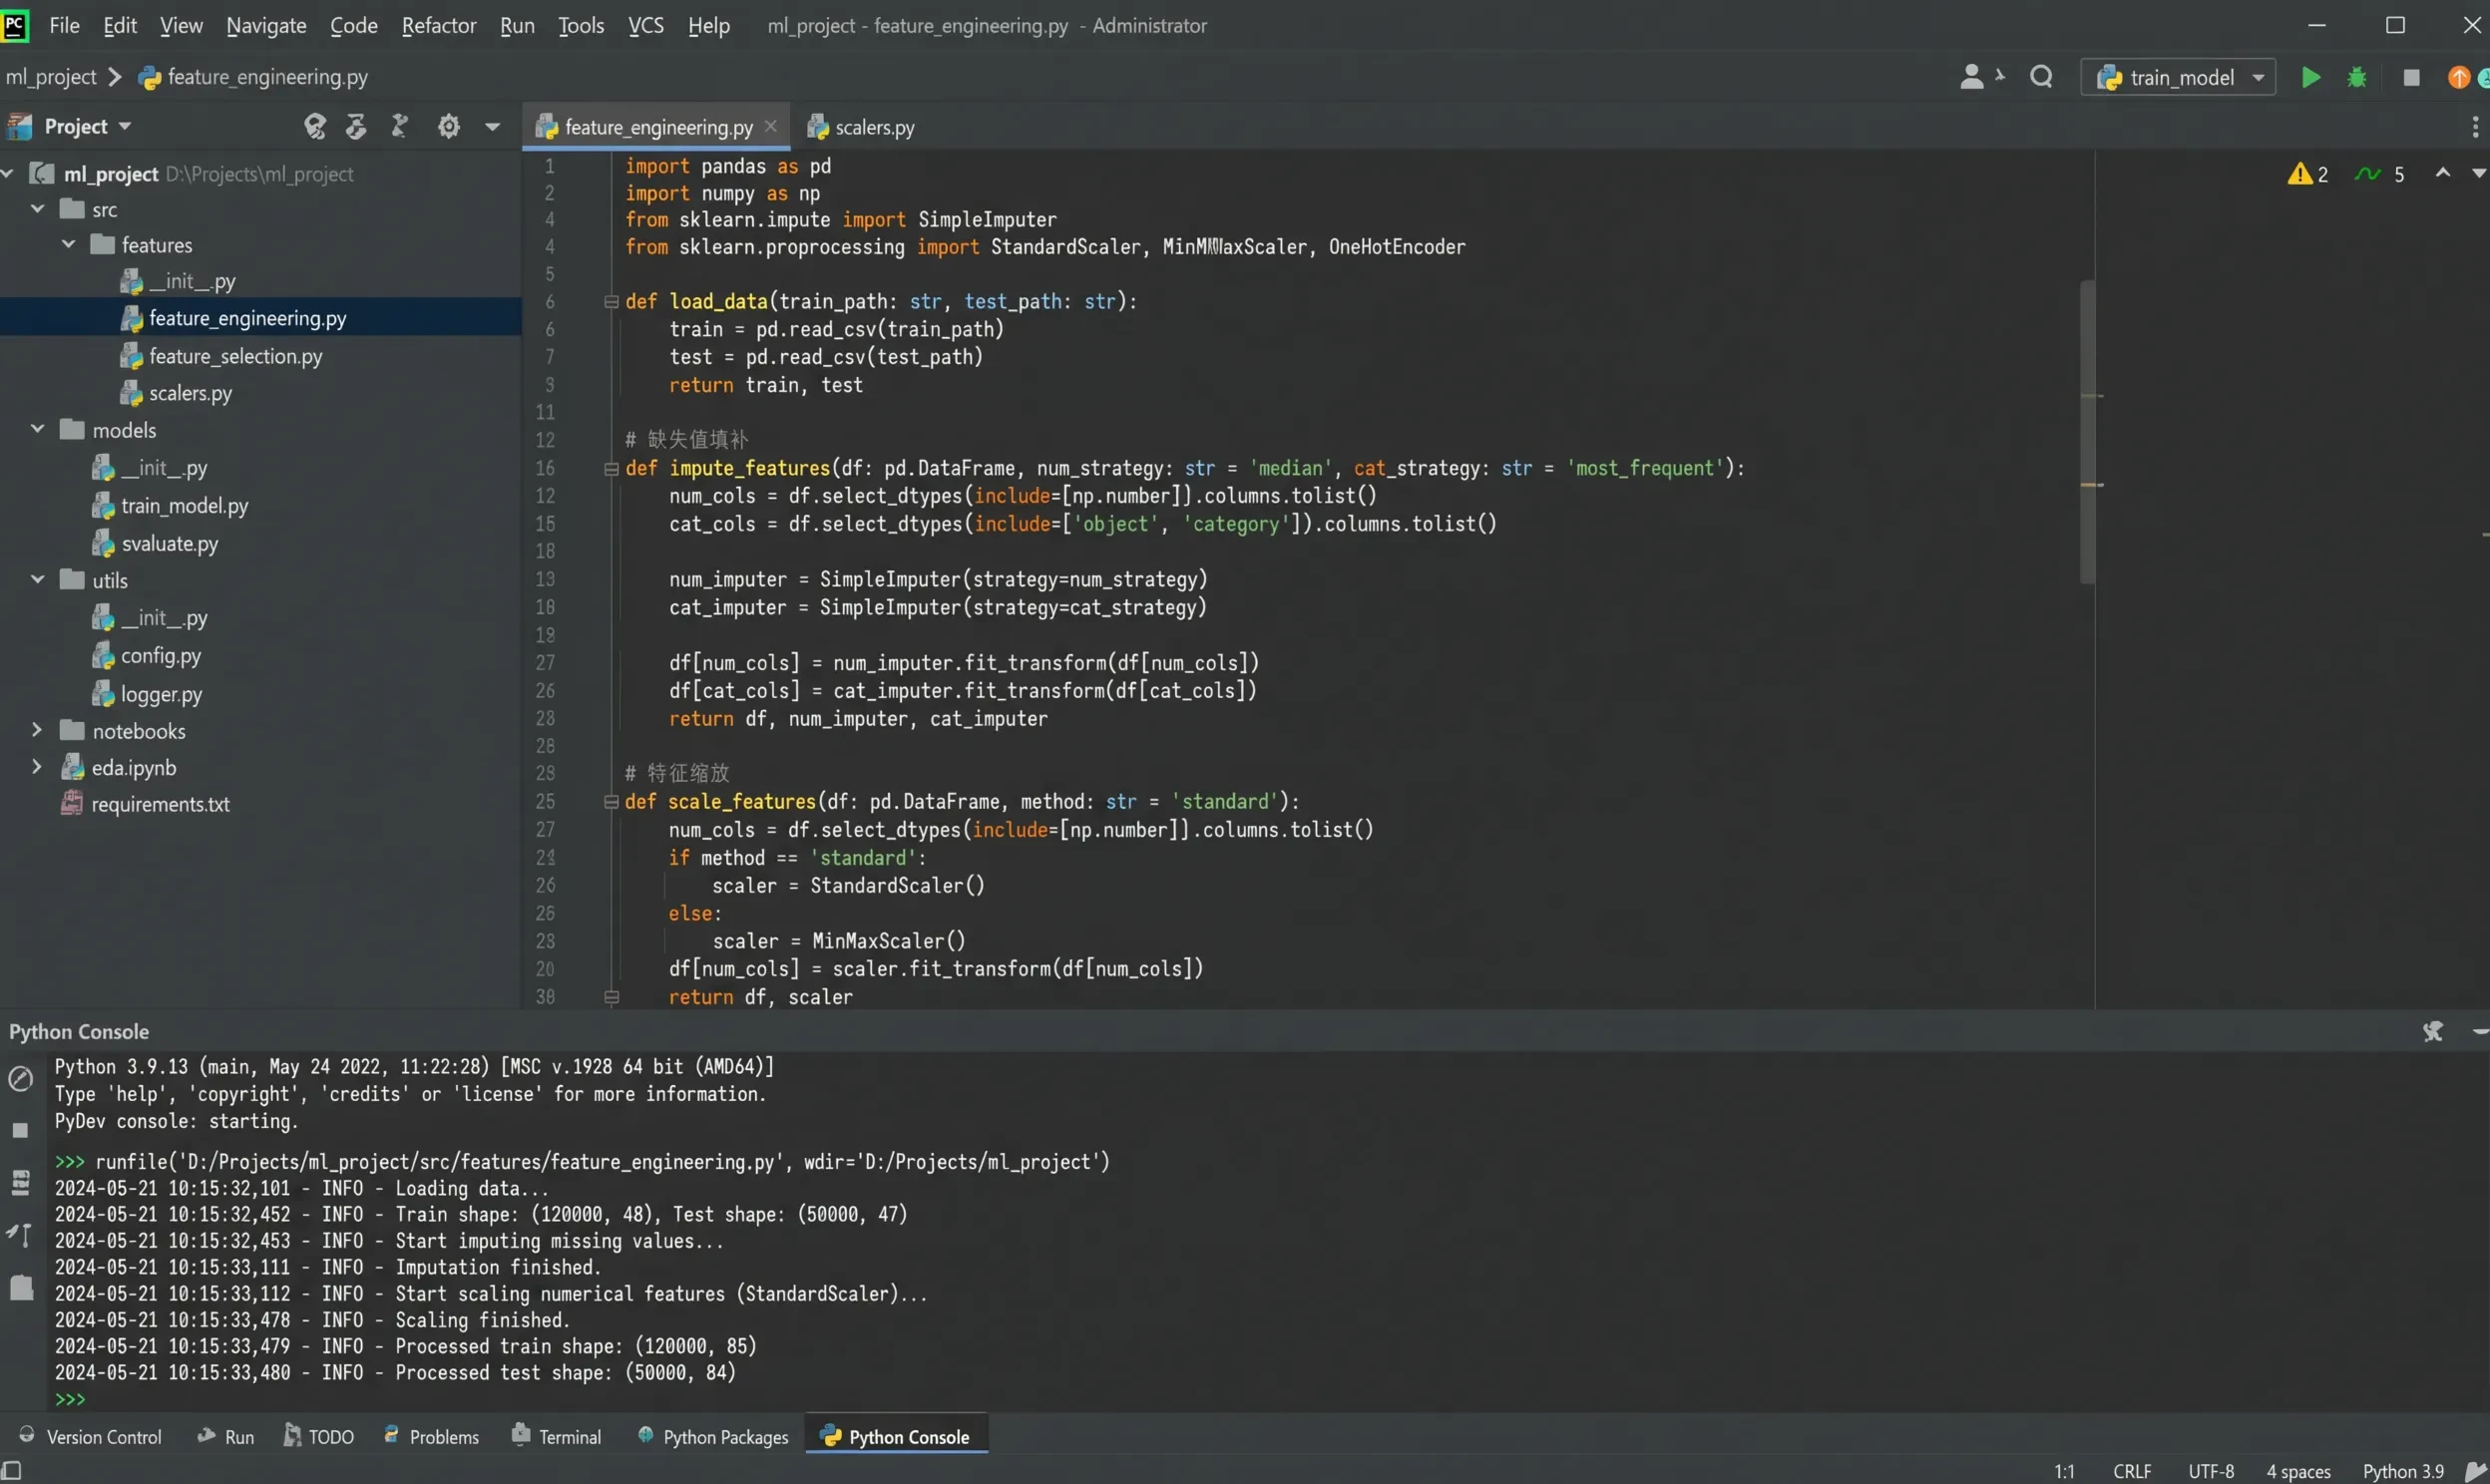
World knowledge applied to UI: a realistic development environment includes code, project structure, warnings, and console output.
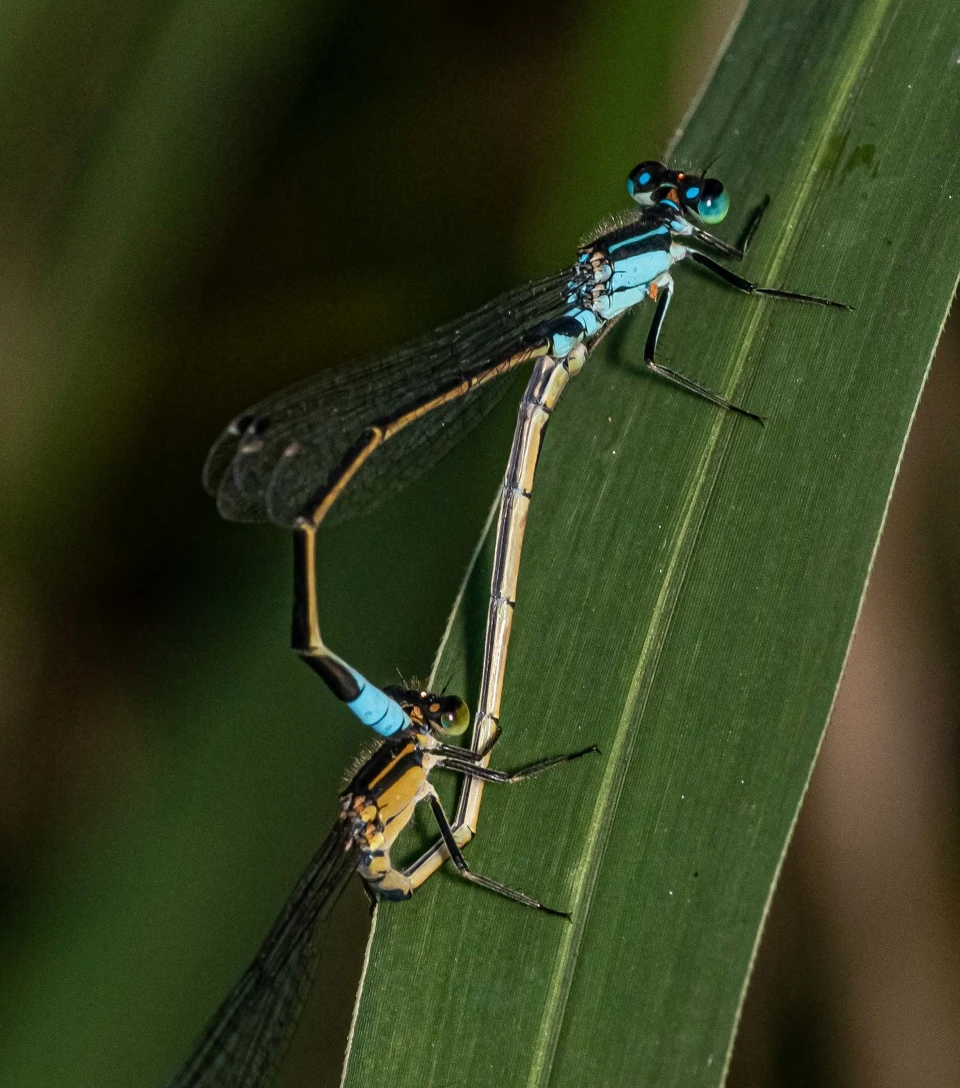
Original insect photograph
Scientific information graphic
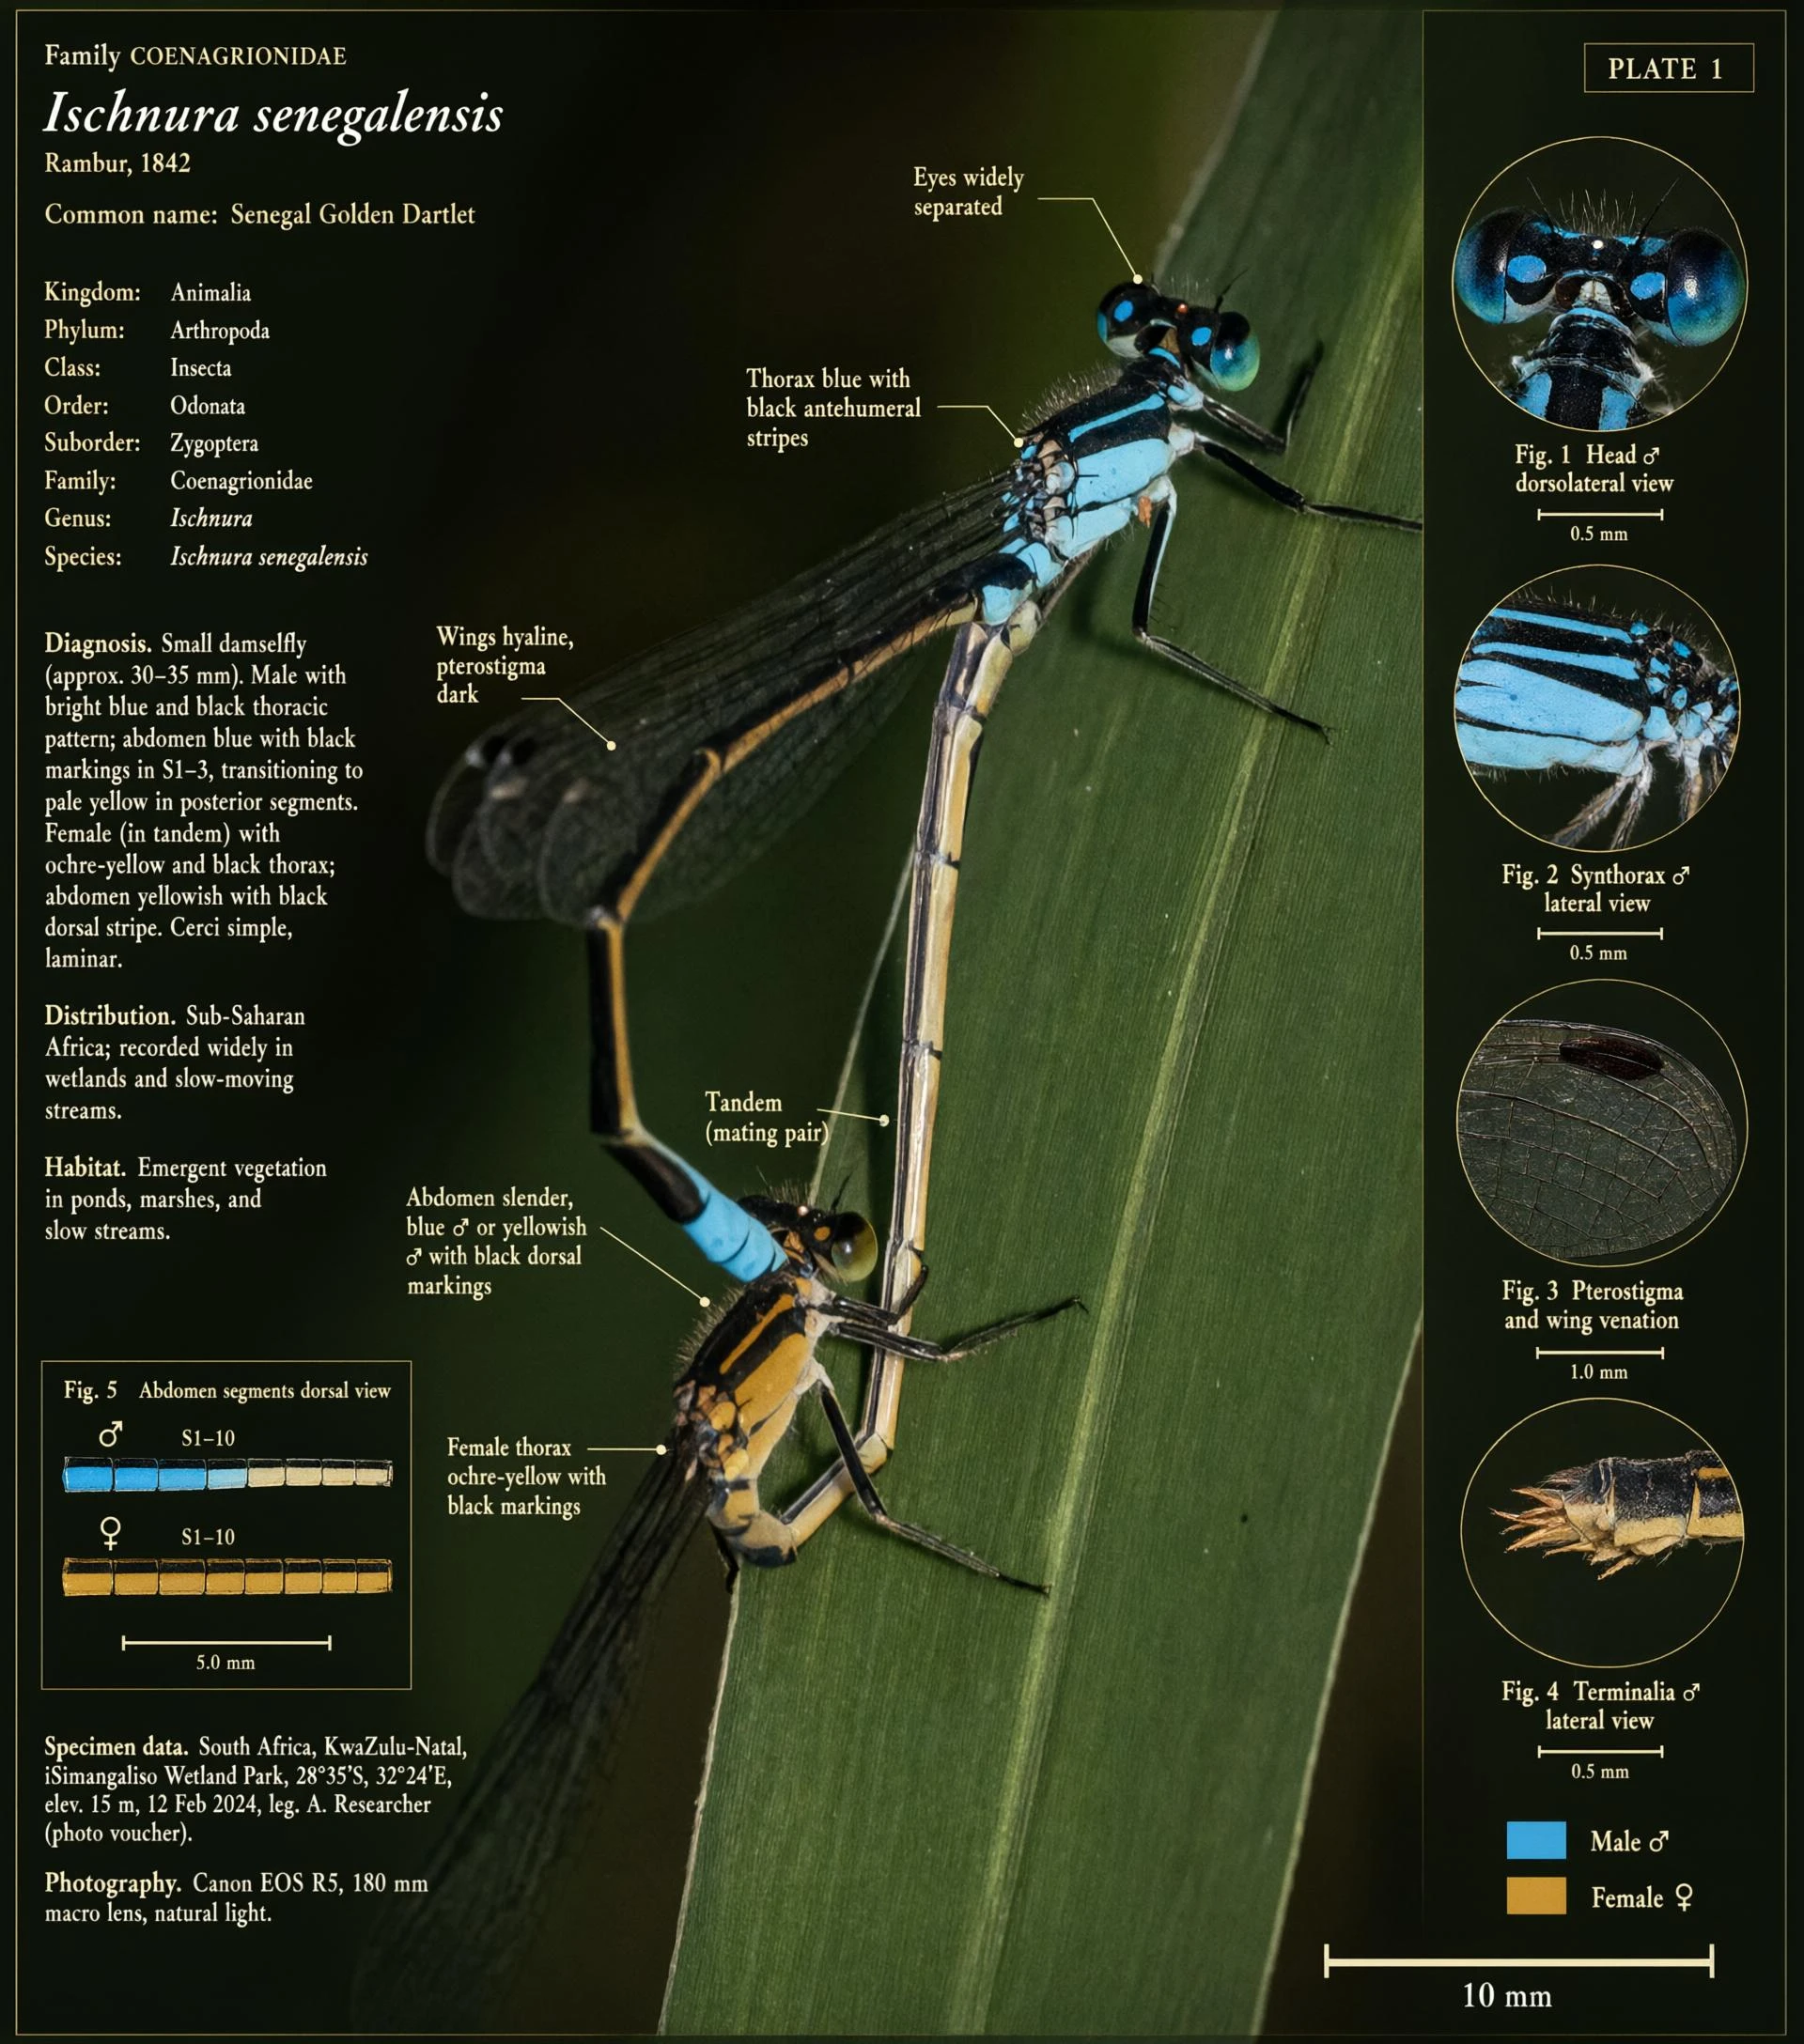
Knowledge expansion example: the source insect photograph becomes a publication-style scientific plate with taxonomy, morphology labels, close-up details, habitat notes, and scale references.
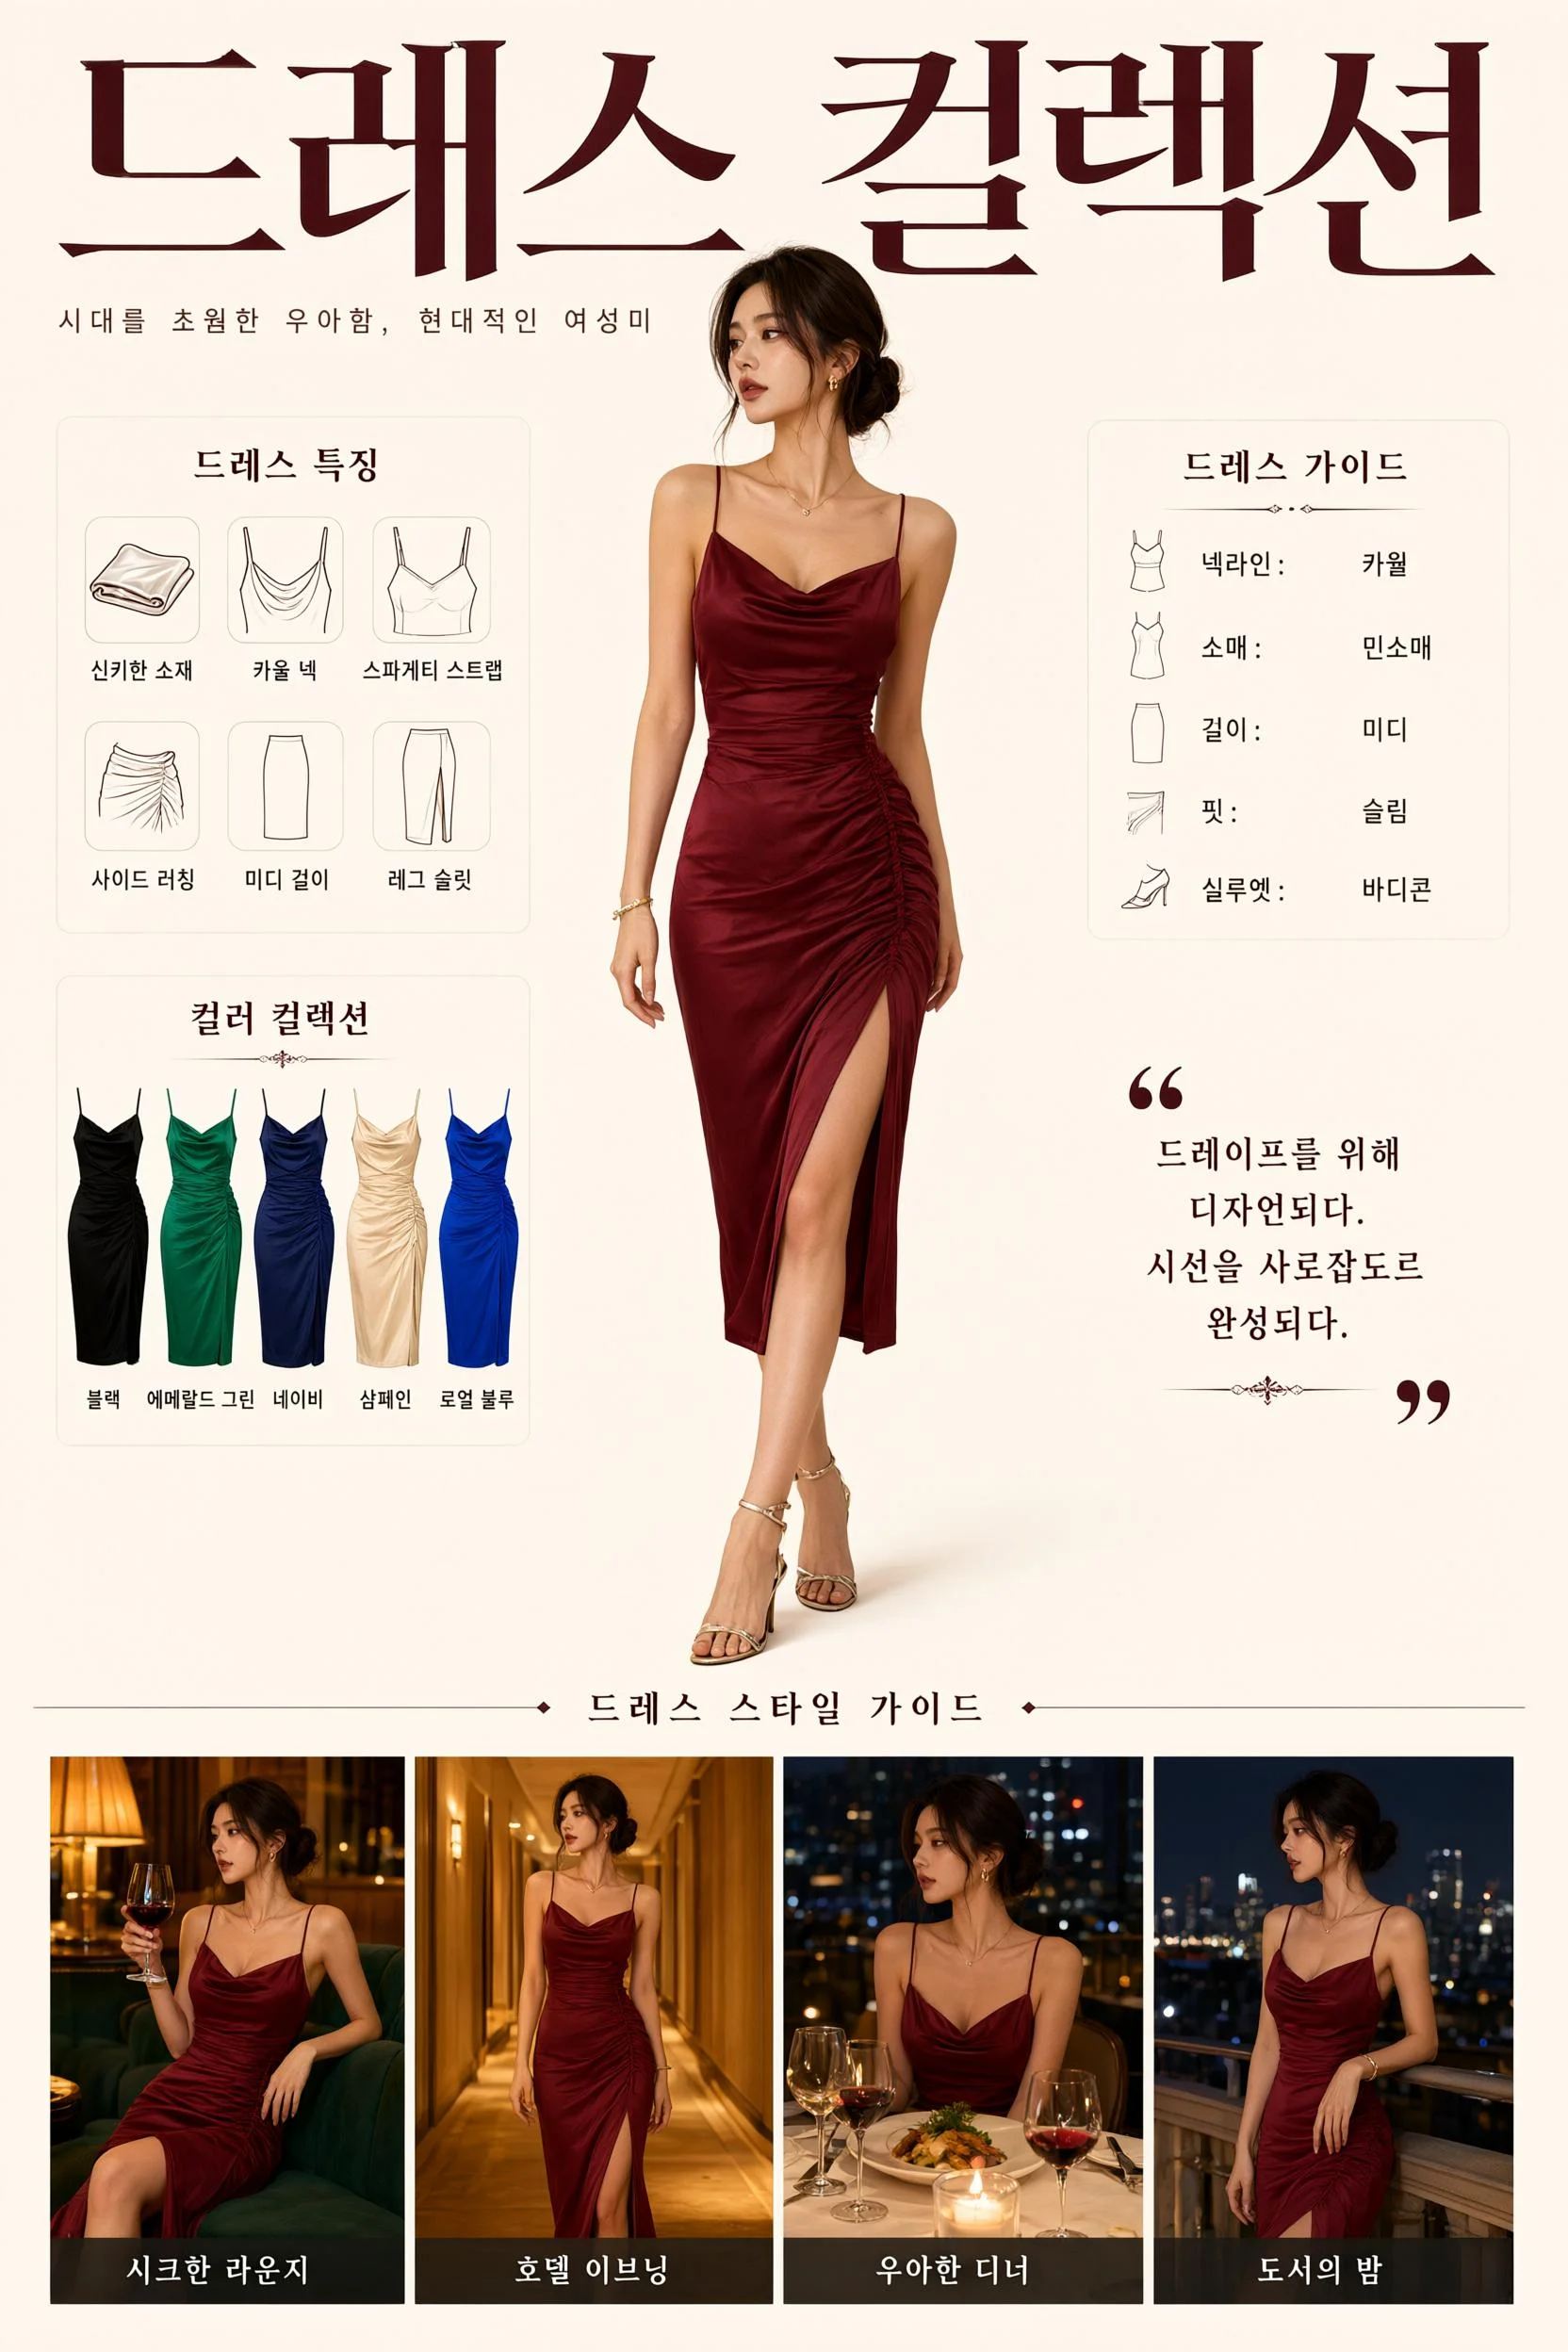
Multilingual production design: a Korean fashion collection page combines a title, garment guide, color palette, quotes, and coordinated lifestyle scenes.
Full Introduction and Release Status
The third-generation Qwen-Image release moves from attractive images toward practical, information-rich visual production.
Key Features
- Rich Content: Up to 4.5K-token instructions for newspapers, storyboards, exam papers, complex diagrams, and nine-panel knowledge graphics.
- Authentic Details: Official examples emphasize approximately 10px text, formulas, annotations, pores, hair strands, and realistic material textures.
- Deep Knowledge: Native rendering across 12 languages, multiple fonts, 100+ artistic styles, and realistic web, game, and livestream interfaces.
- Spatial Composition: Supports side-by-side content expansion and nested picture-in-picture interfaces in one generated image.
Official Release Status
Qwen-Image 3.0 is currently documented through the official announcement and available as a hosted experience. As of this page update, the official Qwen repositories and model hubs do not provide downloadable 3.0 weights, a confirmed license, a model card, parameter count, benchmark table, or local deployment instructions.
Official Sources
Images: Qwen-Image 3.0 official announcement examples, mirrored to this site's Cloudflare R2 CDN for efficient delivery.
Qwen-Image-Edit-2511
Qwen-Image-Edit-2511 is a released image-to-image model from the Qwen team. Its official model card highlights reduced image drift, improved single- and multi-person consistency, integrated LoRA support, industrial-design use cases, and stronger geometric reasoning.
Official Diffusers quick start
The following structure follows the official model card. Use a CUDA environment with enough memory for the selected precision and loading strategy.
pip install git+https://github.com/huggingface/diffusers

import torch
from PIL import Image
from diffusers import QwenImageEditPlusPipeline

pipeline = QwenImageEditPlusPipeline.from_pretrained(
    "Qwen/Qwen-Image-Edit-2511",
    torch_dtype=torch.bfloat16,
)
pipeline.to("cuda")

source = Image.open("input.png")
with torch.inference_mode():
    result = pipeline(
        image=[source],
        prompt="Replace the background with a quiet library; preserve the subject.",
        generator=torch.manual_seed(0),
        true_cfg_scale=4.0,
        negative_prompt=" ",
        num_inference_steps=40,
        guidance_scale=1.0,
    ).images[0]

result.save("qwen_edit.png")
For multi-image editing and the latest supported parameters, use the complete example on the official model card.
HiDream-O1-Image
HiDream-O1-Image by HiDream.ai (智象未来) — an 8B natively-unified image foundation model built on a Pixel-Level Unified Transformer (UiT): one end-to-end model on raw pixels with no VAE and no separate text encoder. The official repository includes full and distilled Dev variants and supports text-to-image, editing, and subject-driven personalization at up to 2,048 × 2,048.
✅ Open-Source — HiDream-O1-Image (8B)
MIT licensed and fully self-hostable. Ranked #8 open-weights in an April 2026 AA Text-to-Image Arena snapshot. This is the version the install guide below covers.
⭐ Commercial — HiDream-O1-Image-1.5
A separate closed-source commercial route. Cloud / online access only — do not treat it as the downloadable 8B model covered by this guide.
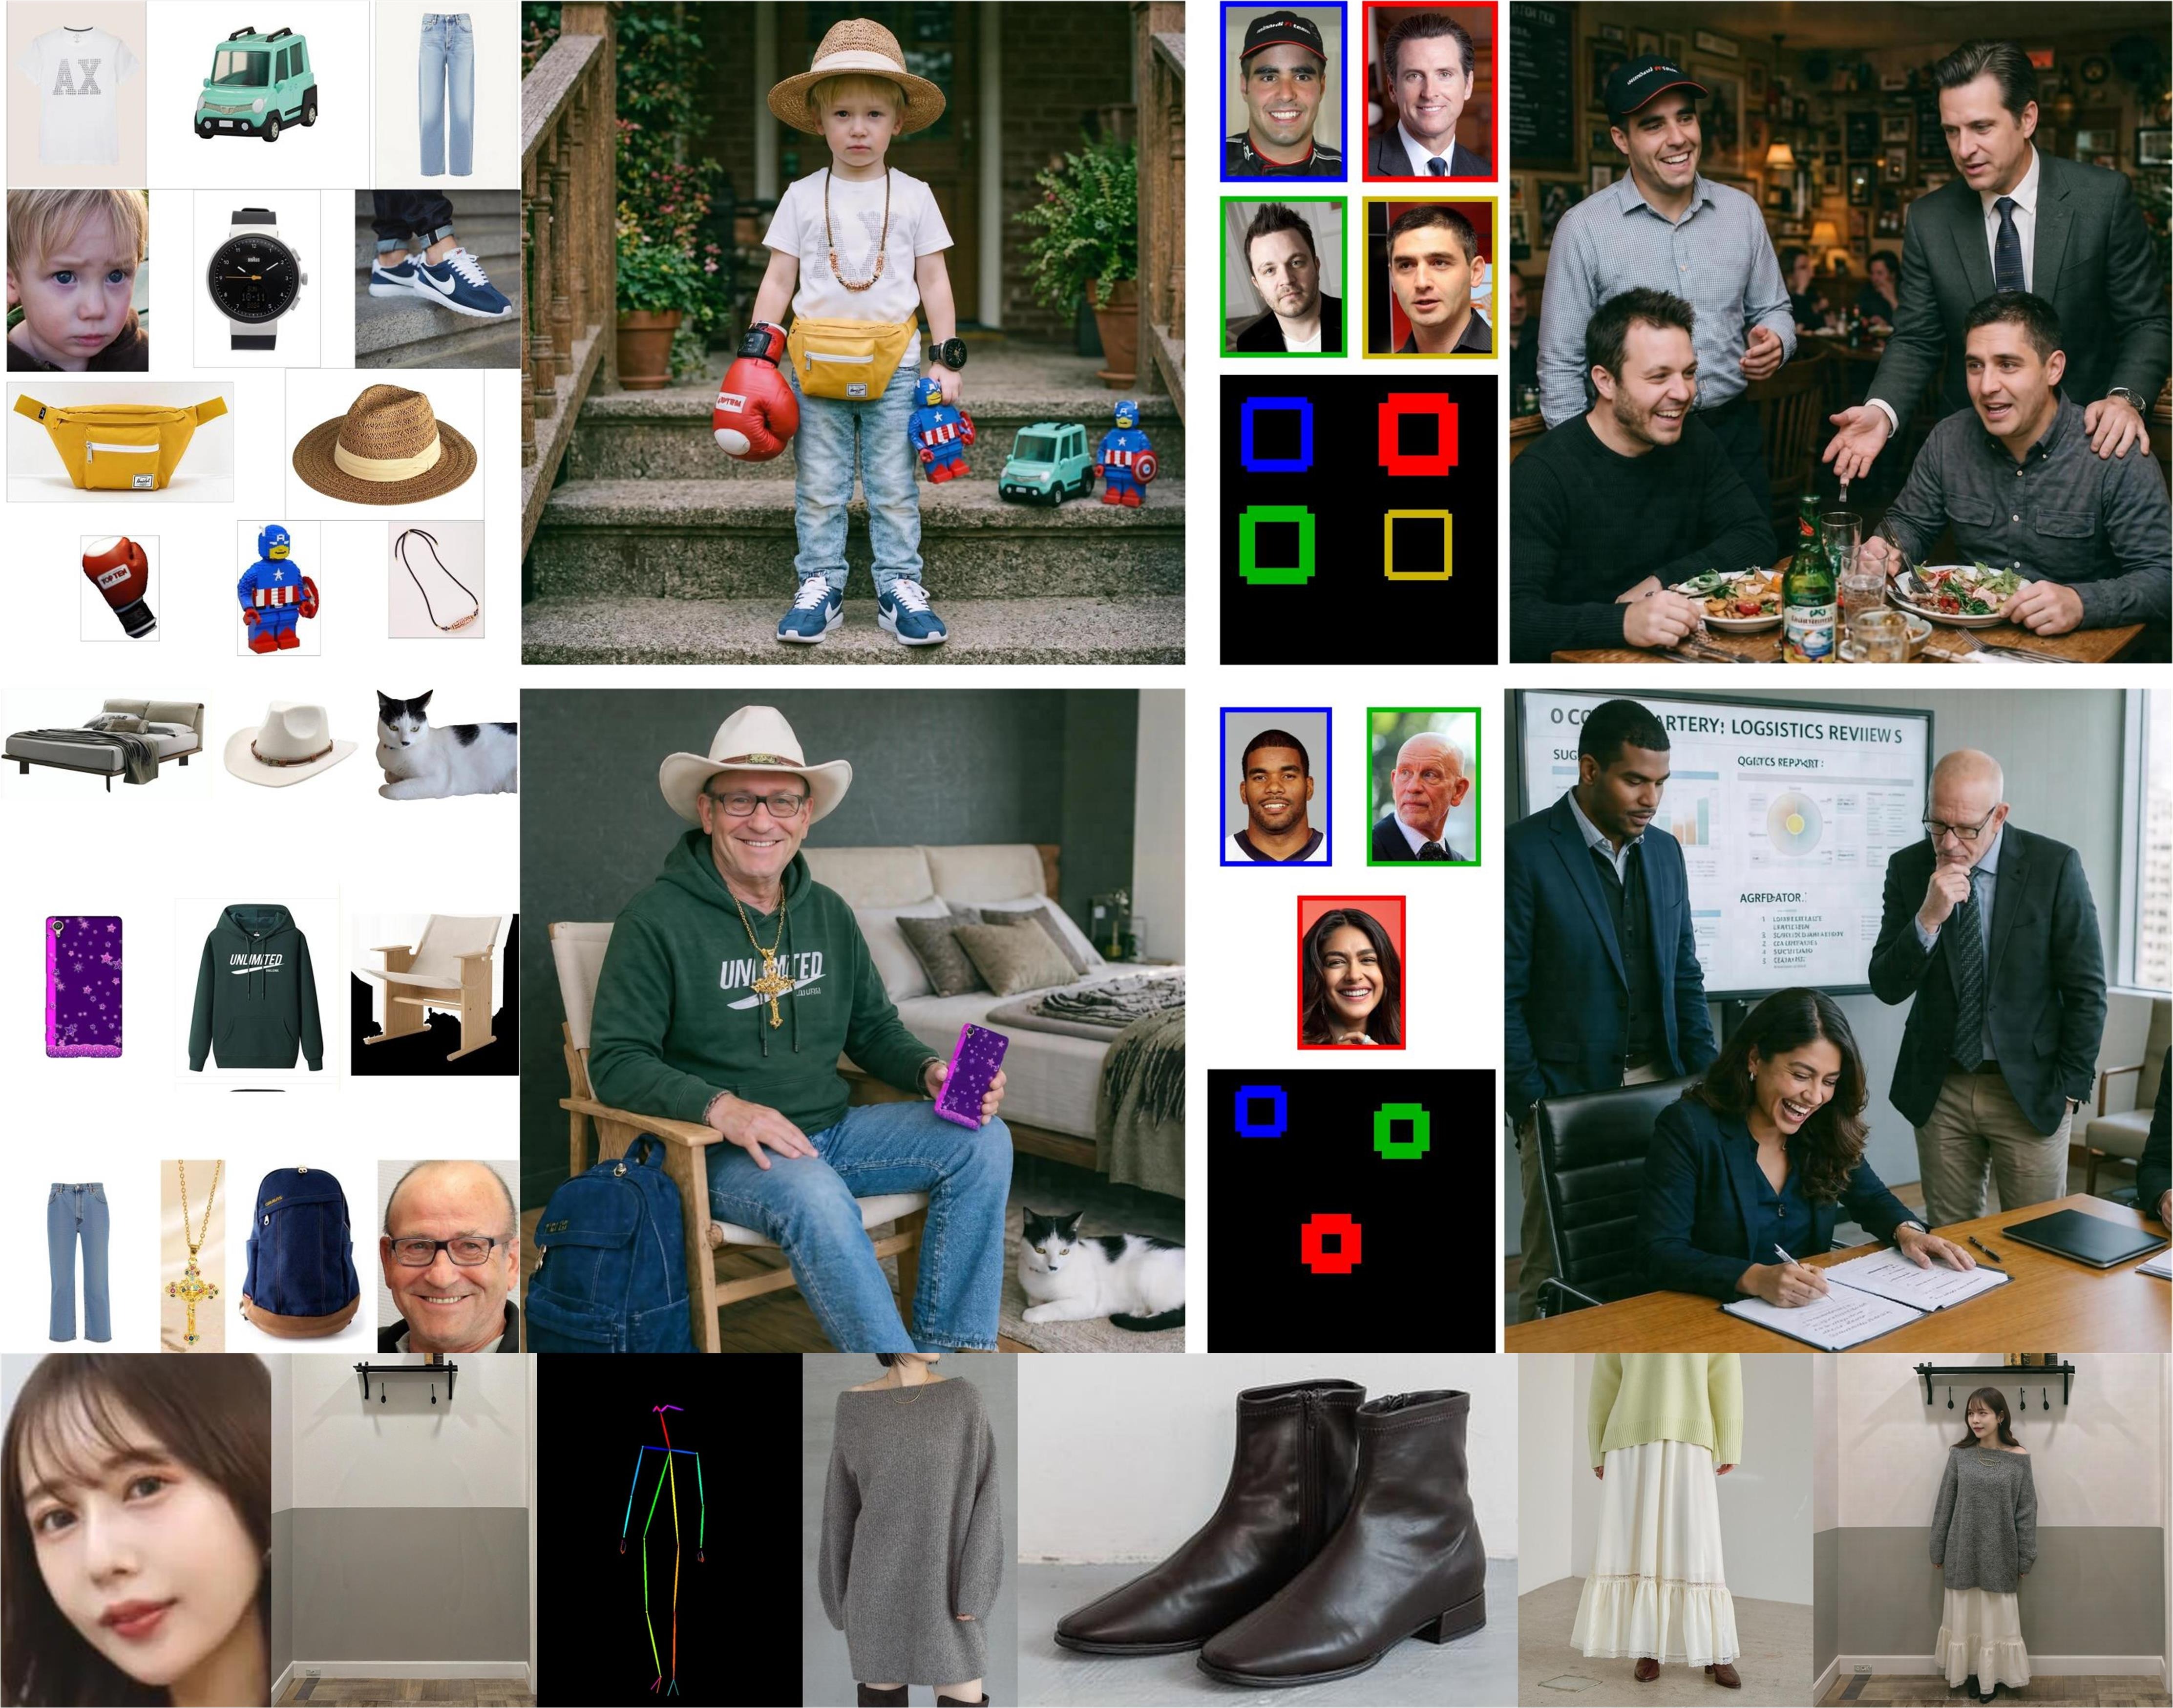
Full Technical Details (Repo Mirror)
One end-to-end model on raw pixels — no VAE, no disjoint text encoder.
Project Updates
- 2026.05.08: Open-sourced HiDream-O1-Image (8B) — both undistilled (full) and distilled (Dev) variants, plus the Reasoning-Driven Prompt Agent.
- 2026.05.14: Open-sourced HiDream-O1-Image-Dev-2604 with its prompt refiner, tailored for text-to-image.
- 2026.05: Dev-2604 was released as the distilled text-to-image variant.
Key Features
- Pixel-Level Unified Transformer: One end-to-end model on raw pixels, no VAE, no disjoint text encoder.
- One Model, Many Tasks: Text-to-image, long-text rendering, instruction editing, subject-driven personalization, and storyboard generation in a single architecture.
- Reasoning-Driven Prompt Agent: Built-in "thinking" agent that resolves implicit knowledge, layout, and text rendering before generation.
- Native High Resolution: Direct synthesis up to 2,048 × 2,048 with sharp detail.
- 8B Unified Architecture: One released model family covers generation, editing, and subject-driven workflows.
Model Variants
| Model | Type | Best For |
|---|---|---|
| HiDream-O1-Image | Full (undistilled) | Highest quality; recommended for editing tasks |
| HiDream-O1-Image-Dev | Distilled | Faster inference |
| HiDream-O1-Image-Dev-2604 | Distilled (latest) | Text-to-image; AA Arena #8 open-weights |
Installation
git clone https://github.com/HiDream-ai/HiDream-O1-Image.git
cd HiDream-O1-Image
pip install -r requirements.txt
# flash-attn is strongly recommended. Without it, set "use_flash_attn": False
# in models/pipeline.py (line ~341) or inference will fail to import the kernel.
Quick Start: Text-to-Image
# Undistilled full model (best quality)
python inference.py --model_type full --prompt "A serene mountain lake at sunset, cinematic lighting"

# Distilled dev model (faster)
python inference.py --model_type dev --prompt "A serene mountain lake at sunset, cinematic lighting"
Reasoning-Driven Prompt Agent (optional)
# Rewrites a raw instruction into a self-contained English prompt.
# Backend A: local Gemma-4-31B-it   Backend B: external OpenAI-compatible API
python prompt_agent.py --backend api --instruction "做一张猫咪生日party的海报,标题写HAPPY BIRTHDAY"
# Feed the returned "prompt" field into inference.py for best results.
Web Demo
python app.py --model_path /path/to/HiDream-O1-Image --model_type full
# launches the repository's local Flask interface
License
The code and the HiDream-O1-Image models are released under the MIT License — free for personal and commercial use.
Citation
@article{hidreamolimage,
  title={HiDream-O1-Image: A Natively Unified Image Generative Foundation Model with Pixel-level Unified Transformer},
  author={Cai, Qi and Chen, Jingwen and Gao, Chengmin and others},
  journal={arXiv preprint arXiv:2605.11061},
  year={2026}
}
Z-Image Turbo
A 6B distilled model using 8-step generation via Decoupled-DMD. 📖 View Full Z-Image Documentation →
Full Technical Details (Repo Mirror)
Single-Stream DiT with Decoupled-DMD Distillation.
Model Zoo
| Model | Steps | Quality | VRAM Friendly |
|---|---|---|---|
| Z-Image-Turbo | 8 | Very High | ✅ Yes |
| Z-Image-Base | 50 | High | ❌ No |
| Z-Image-Edit | 50 | Editing | ⚠️ Med |
Decoupled-DMD Algorithm
Core Insight: Decoupling CFG Augmentation (Engine) from Distribution Matching (Shield). This allows 8-step inference with high fidelity.

Community Acceleration (Low VRAM)
- stable-diffusion.cpp: Pure C++ inference. Runs on 4GB VRAM. View Details →
- Cache-DiT: 4x speedup on multi-GPU.
- LeMiCa: Training-free timestep acceleration.
Citation
@article{team2025zimage, title={Z-Image: An Efficient Image Generation Foundation Model}, author={Z-Image Team}, year={2025}}