Z-Image
Efficient Image Generation with Single-Stream Diffusion
An efficient 6-billion-parameter foundation model for image generation. Through systematic optimization, it proves that top-tier performance is achievable without relying on enormous model sizes.
Core Features 核心特性
摄影级真实感
超快推理速度
60亿高效参数
中英文本渲染
消费级显卡友好
广博世界知识
Models 模型系列
At just 6 billion parameters, Z-Image produces photorealistic images on par with models an order of
magnitude larger.
仅以60亿参数的规模,Z-Image 能生成与参数量大一个数量级的模型相媲美的照片级真实感图像。
🔧 Z-Image-Omni-Base
A foundation model designed for easy fine-tuning, unifying image generation and editing capabilities.
⚡ Z-Image-Turbo
A distilled version with strong photorealistic generation, accurate bilingual text rendering. Achieves top performance with only 8 steps.
✏️ Z-Image-Edit
Specialized for image editing. Excels at complex instructions, from local modifications to global style transformations.
Architecture 架构
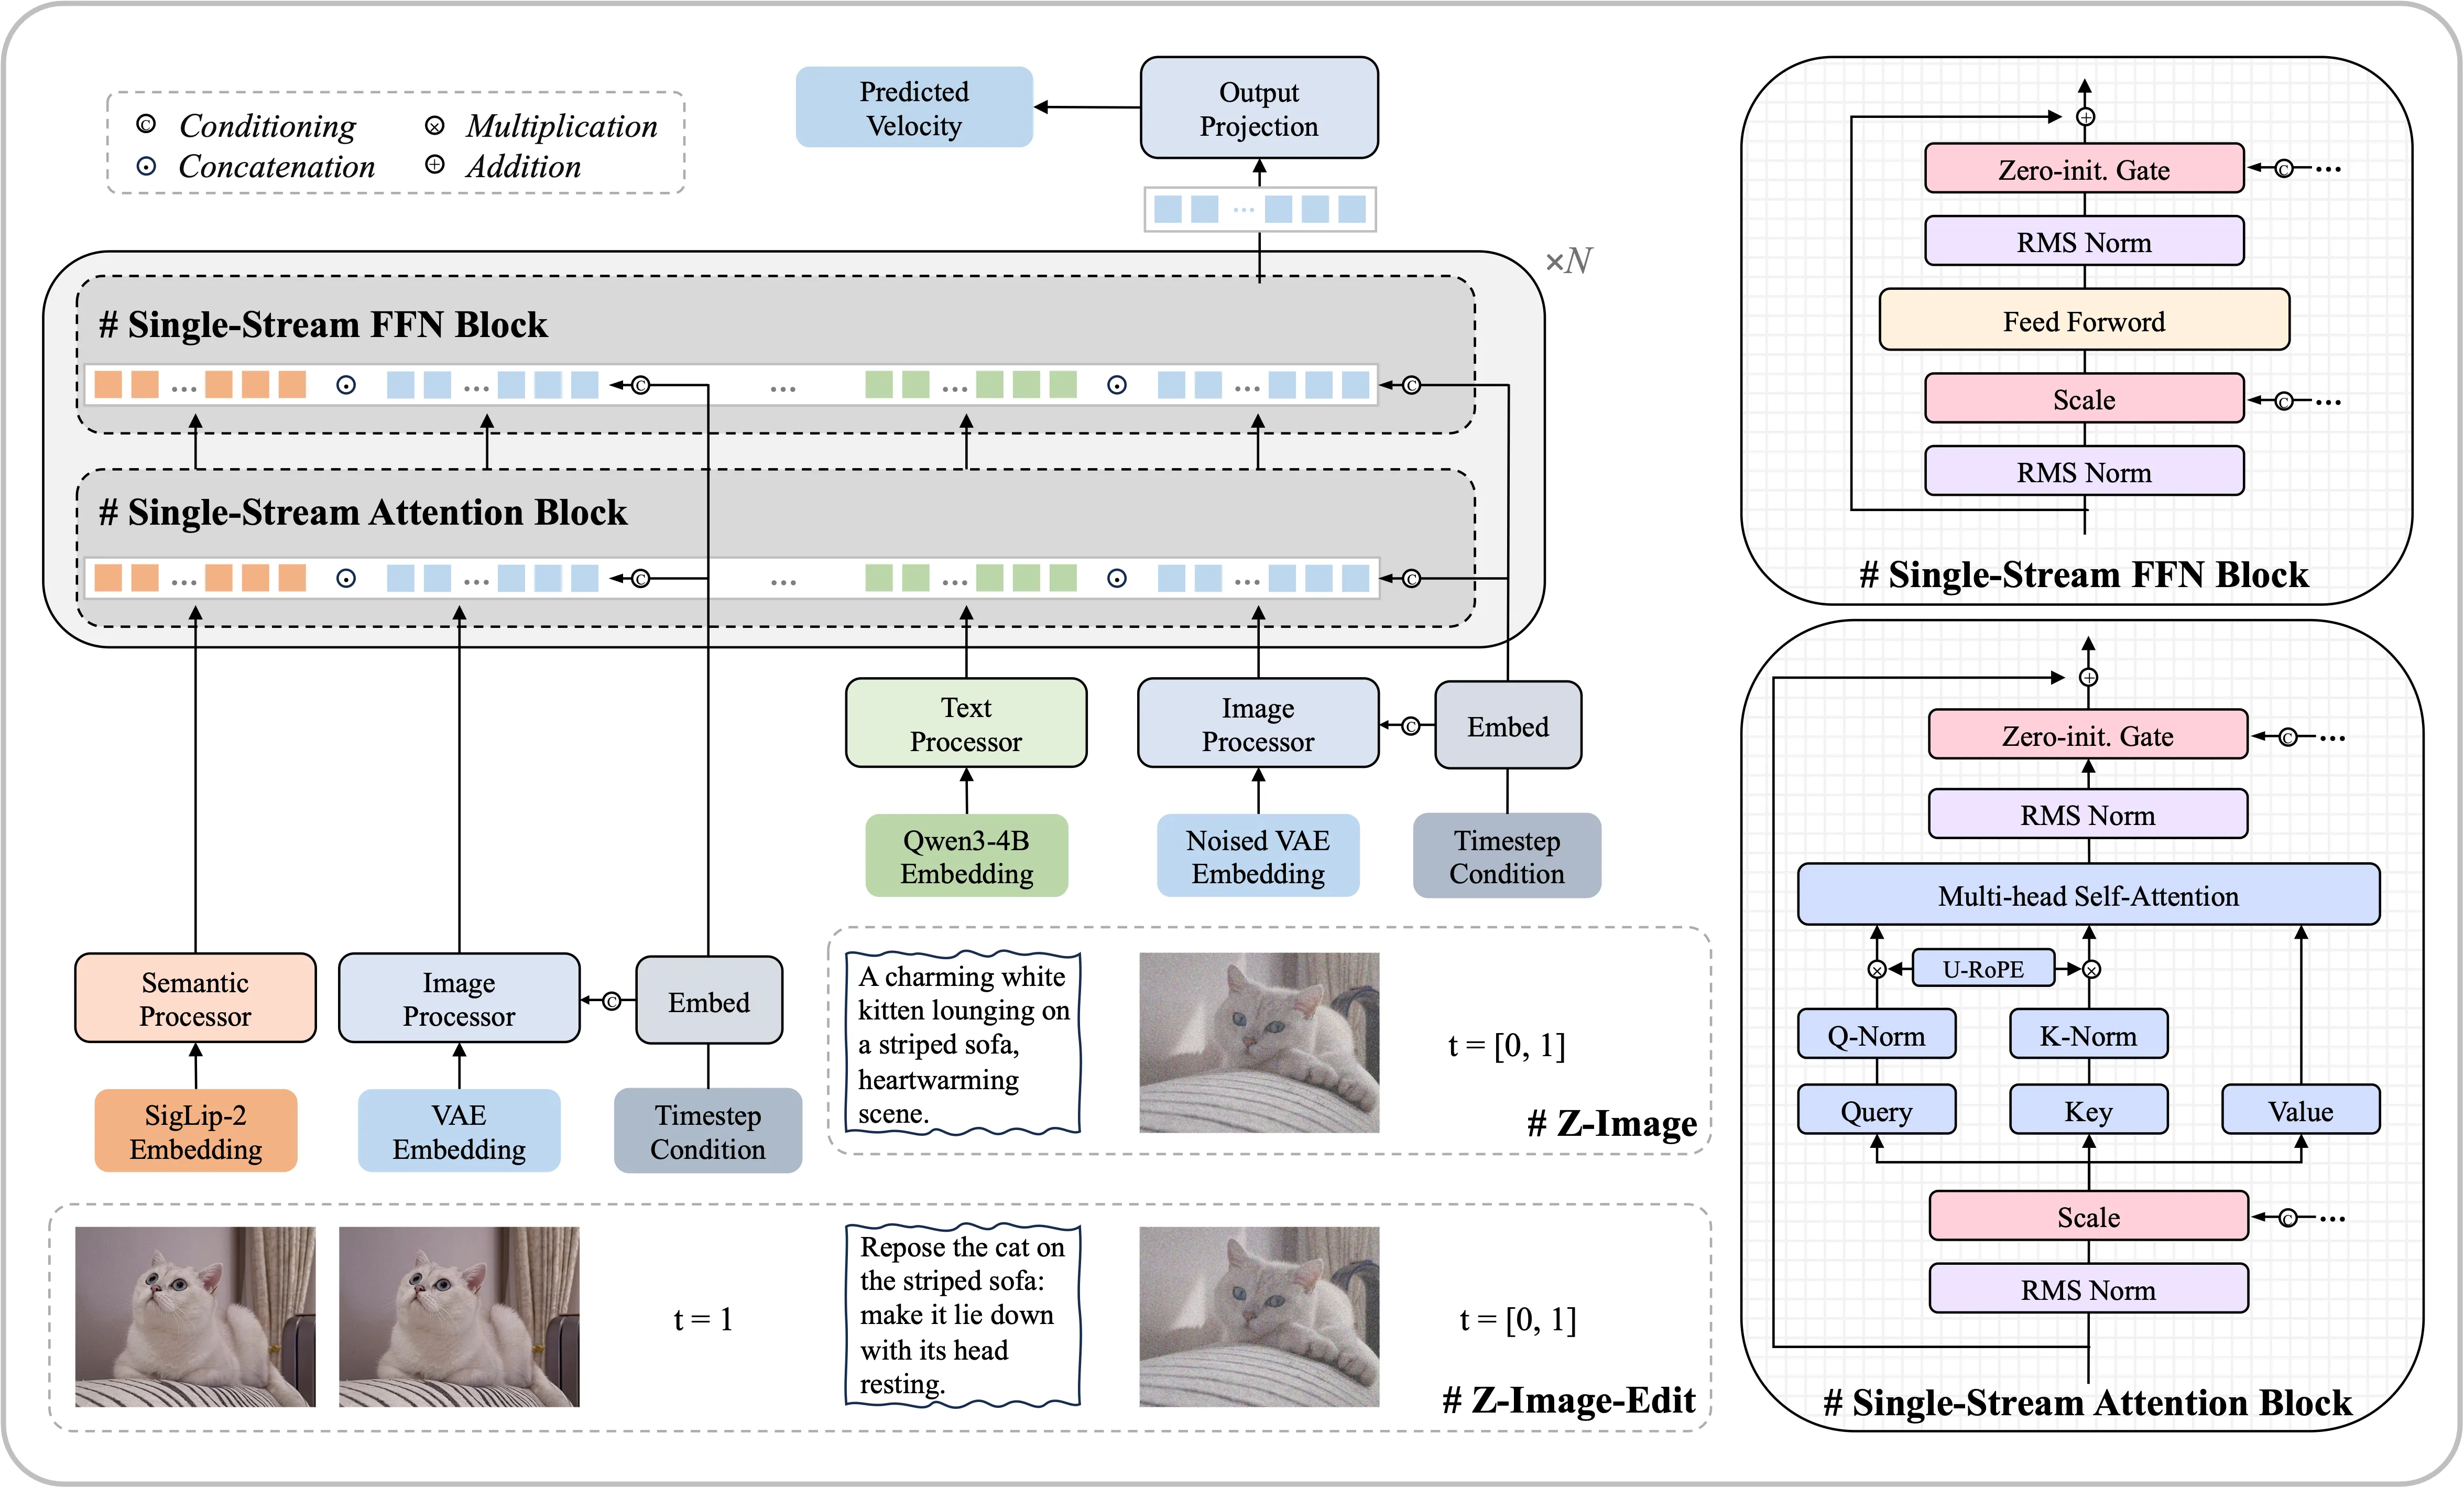
Z-Image adopts a Single-Stream Diffusion Transformer architecture. This design unifies the processing of various conditional inputs (text, image embeddings) with noisy image latents into a single sequence fed into the Transformer backbone.
Arena Ranking 竞技场排名
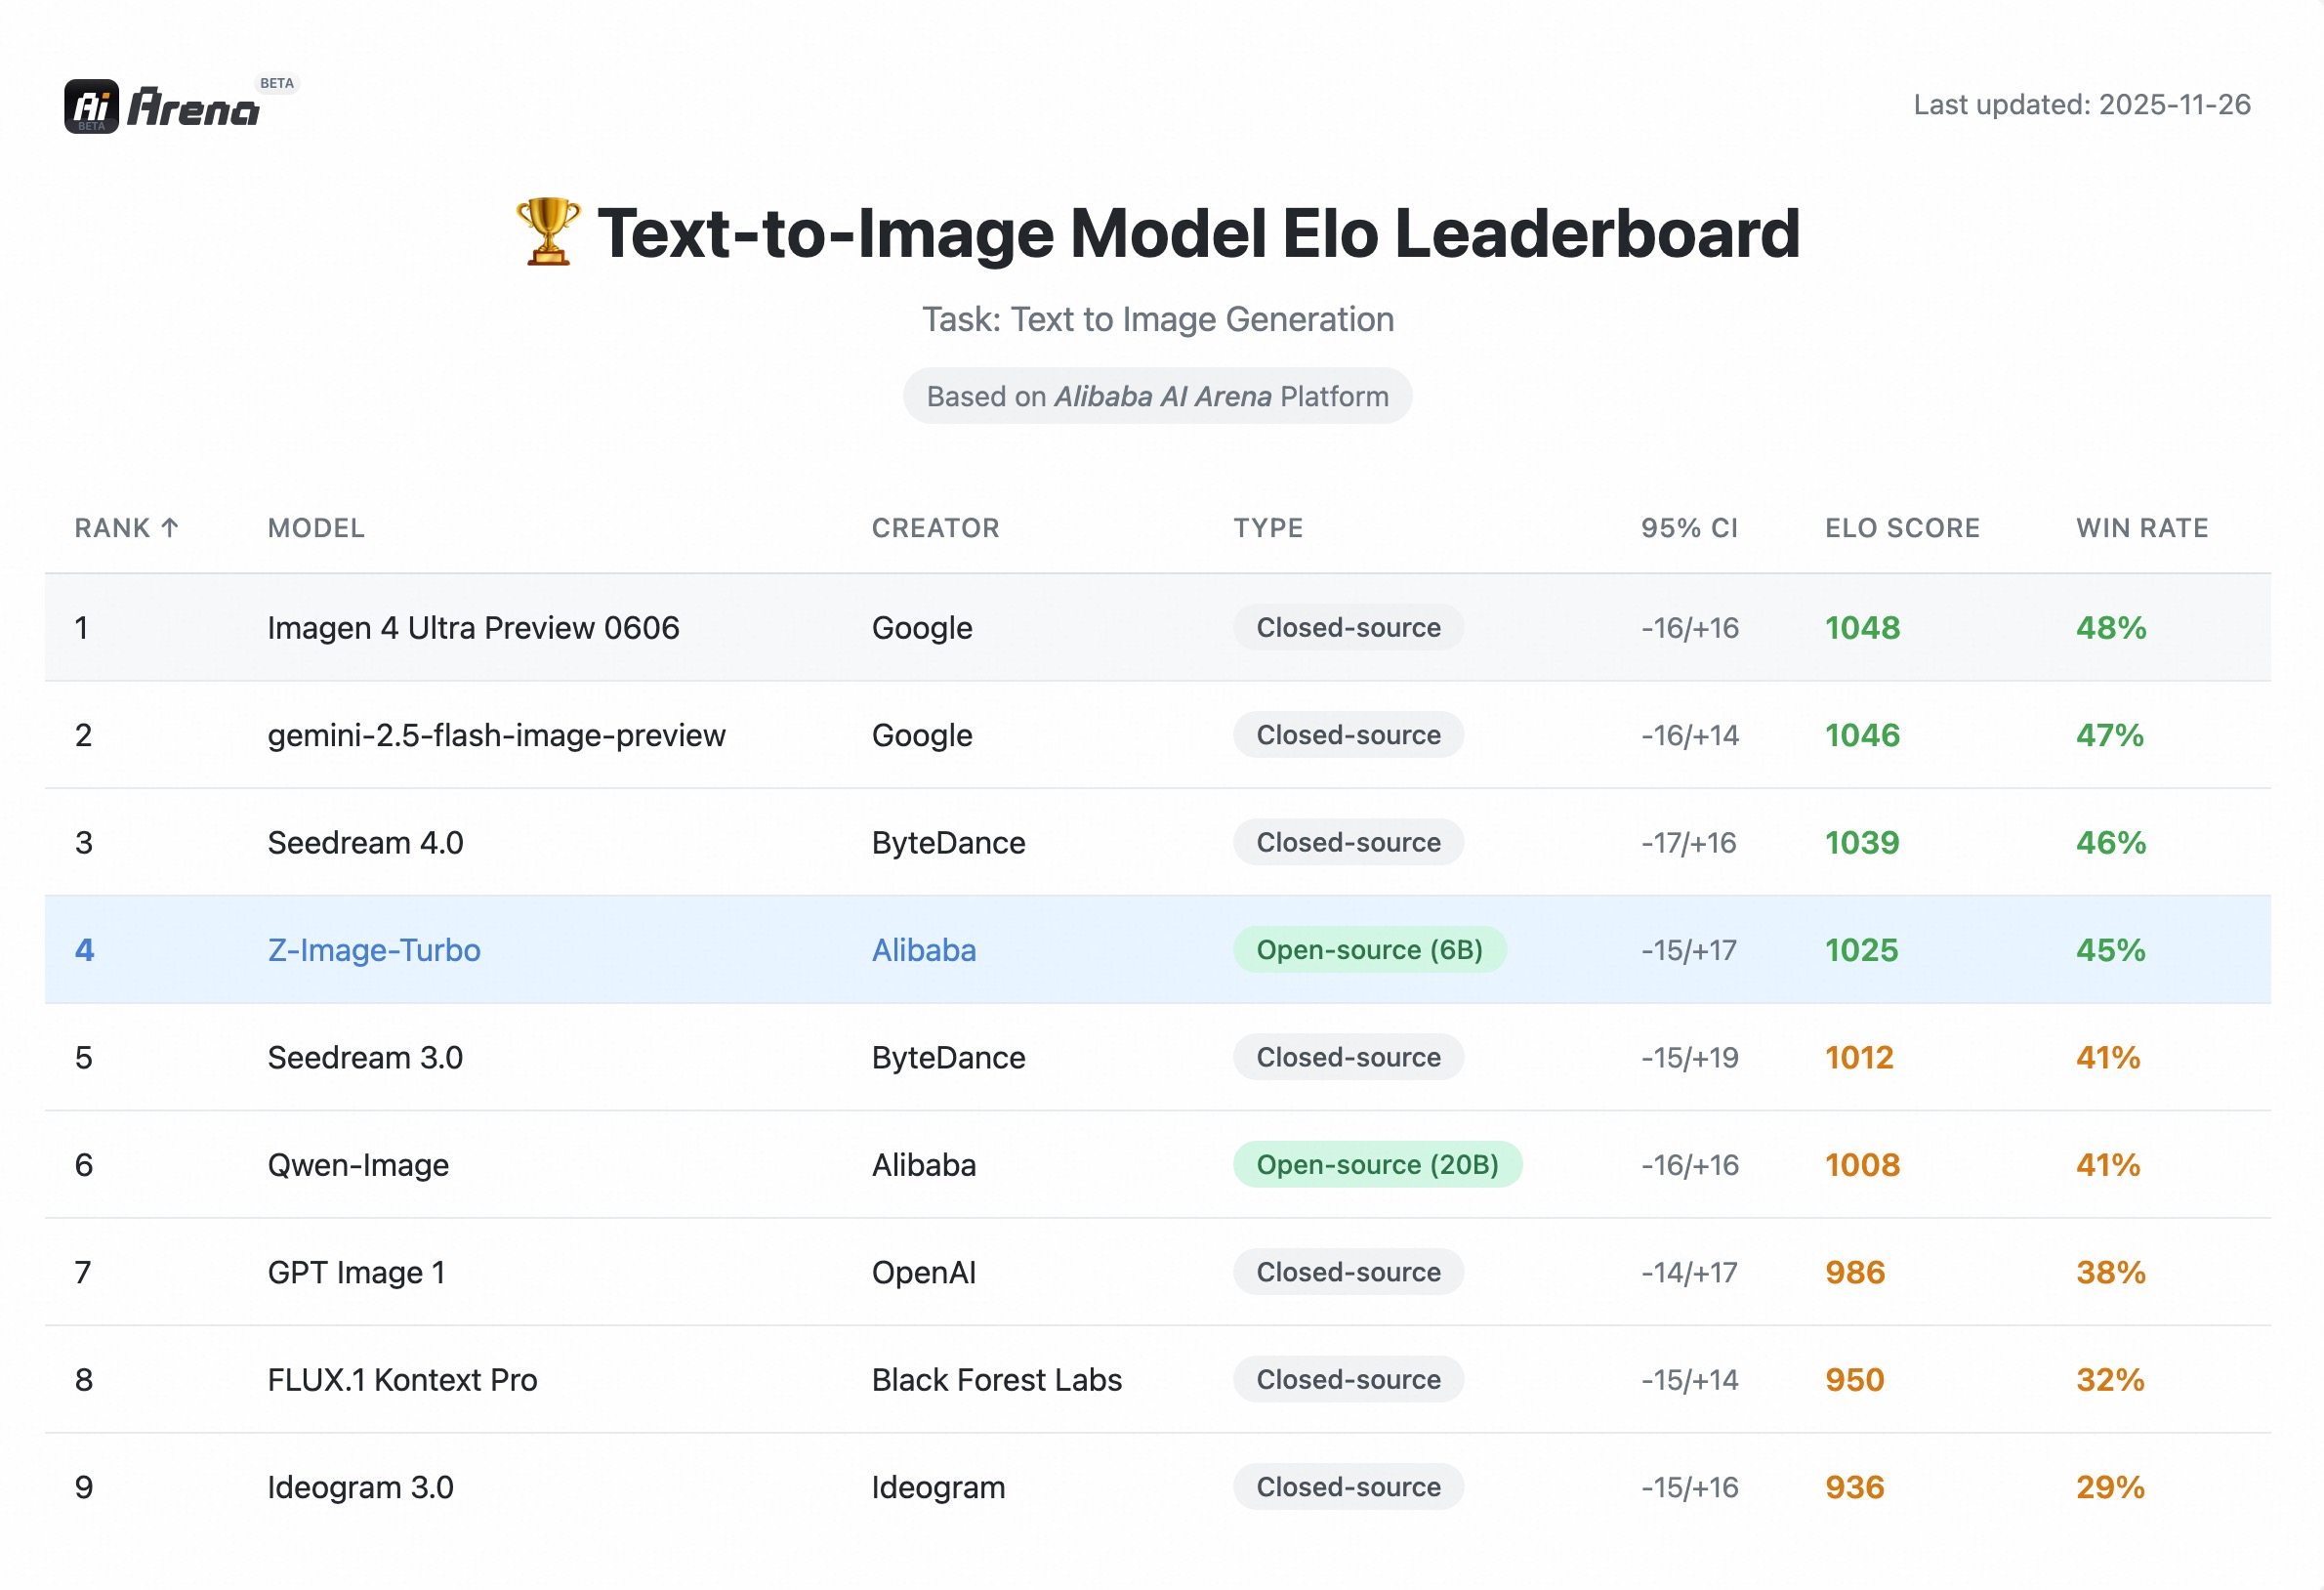
According to Elo-based Human Preference Evaluation (Alibaba AI Arena), Z-Image shows highly competitive performance against leading models and was presented as one of the strongest open-source image systems of its release window.
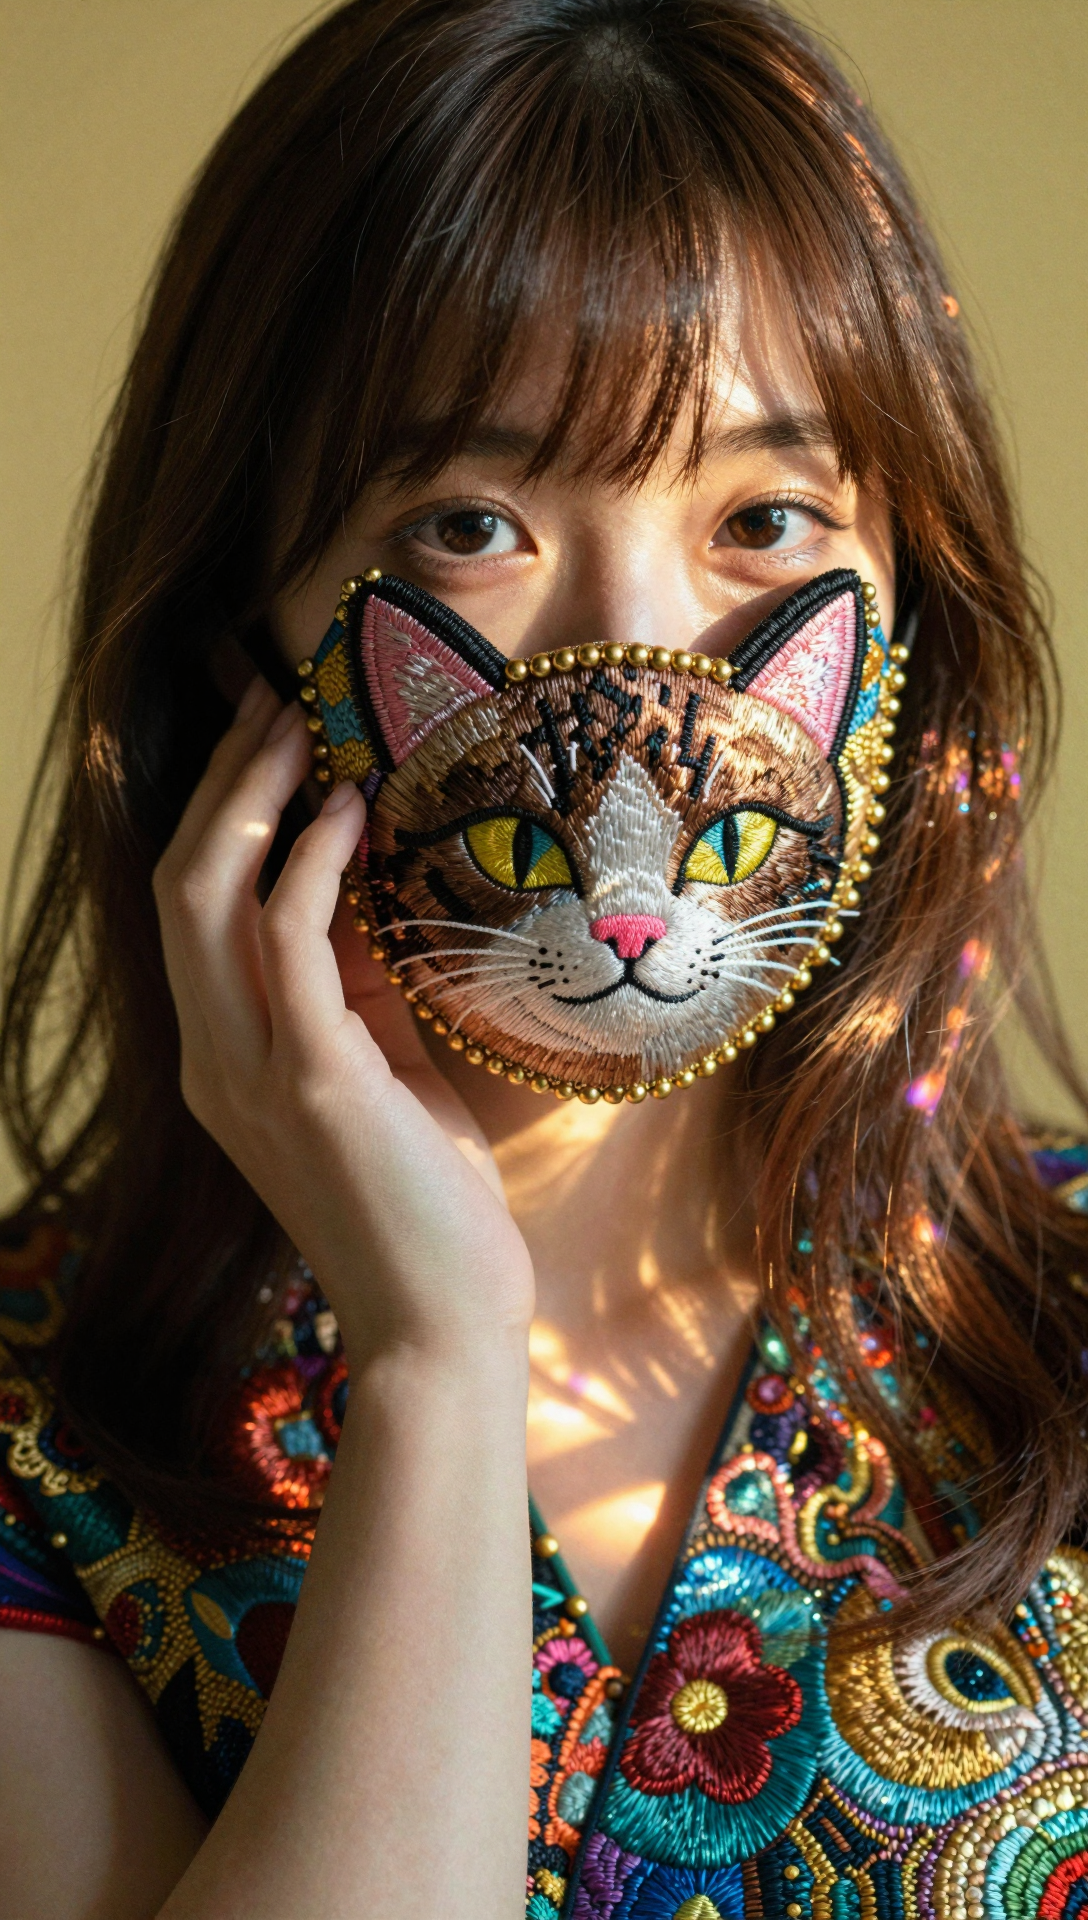
1. Efficient Photorealistic Quality 极致高效的照片级真实感
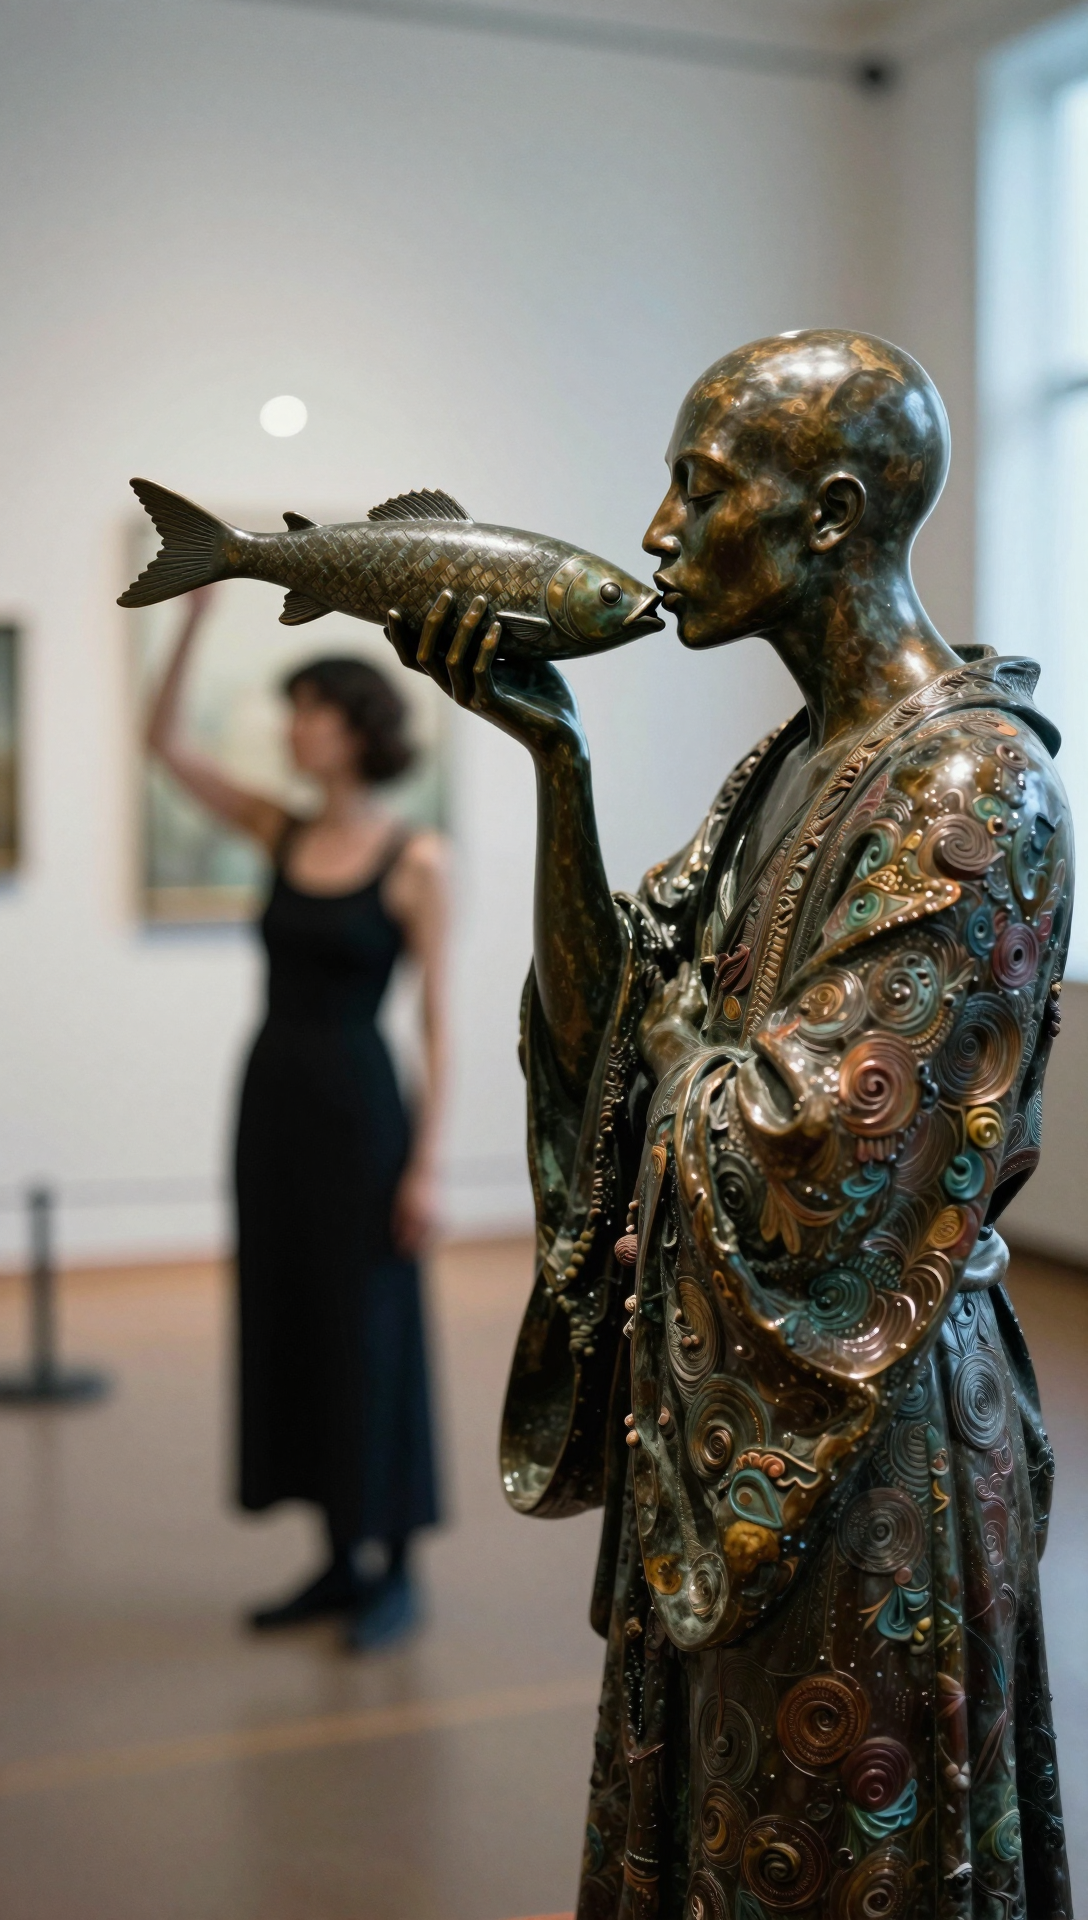
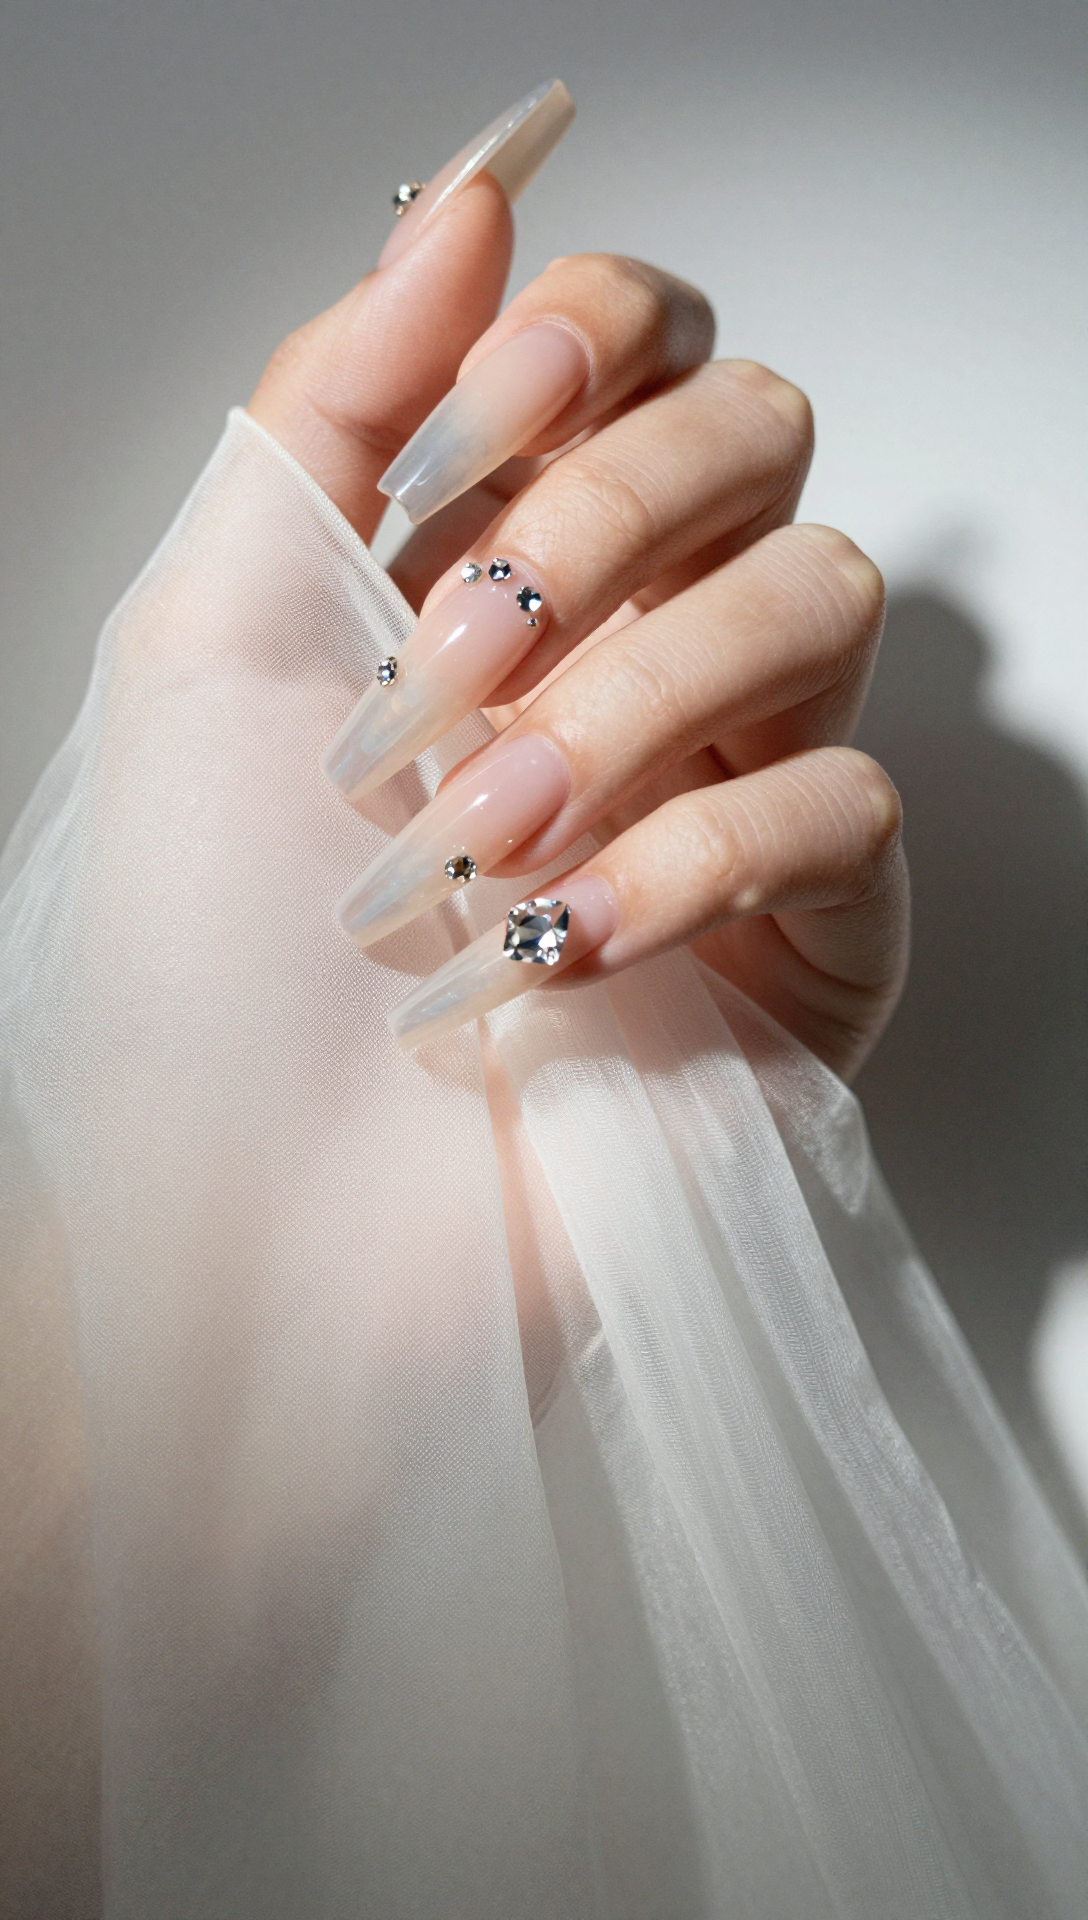
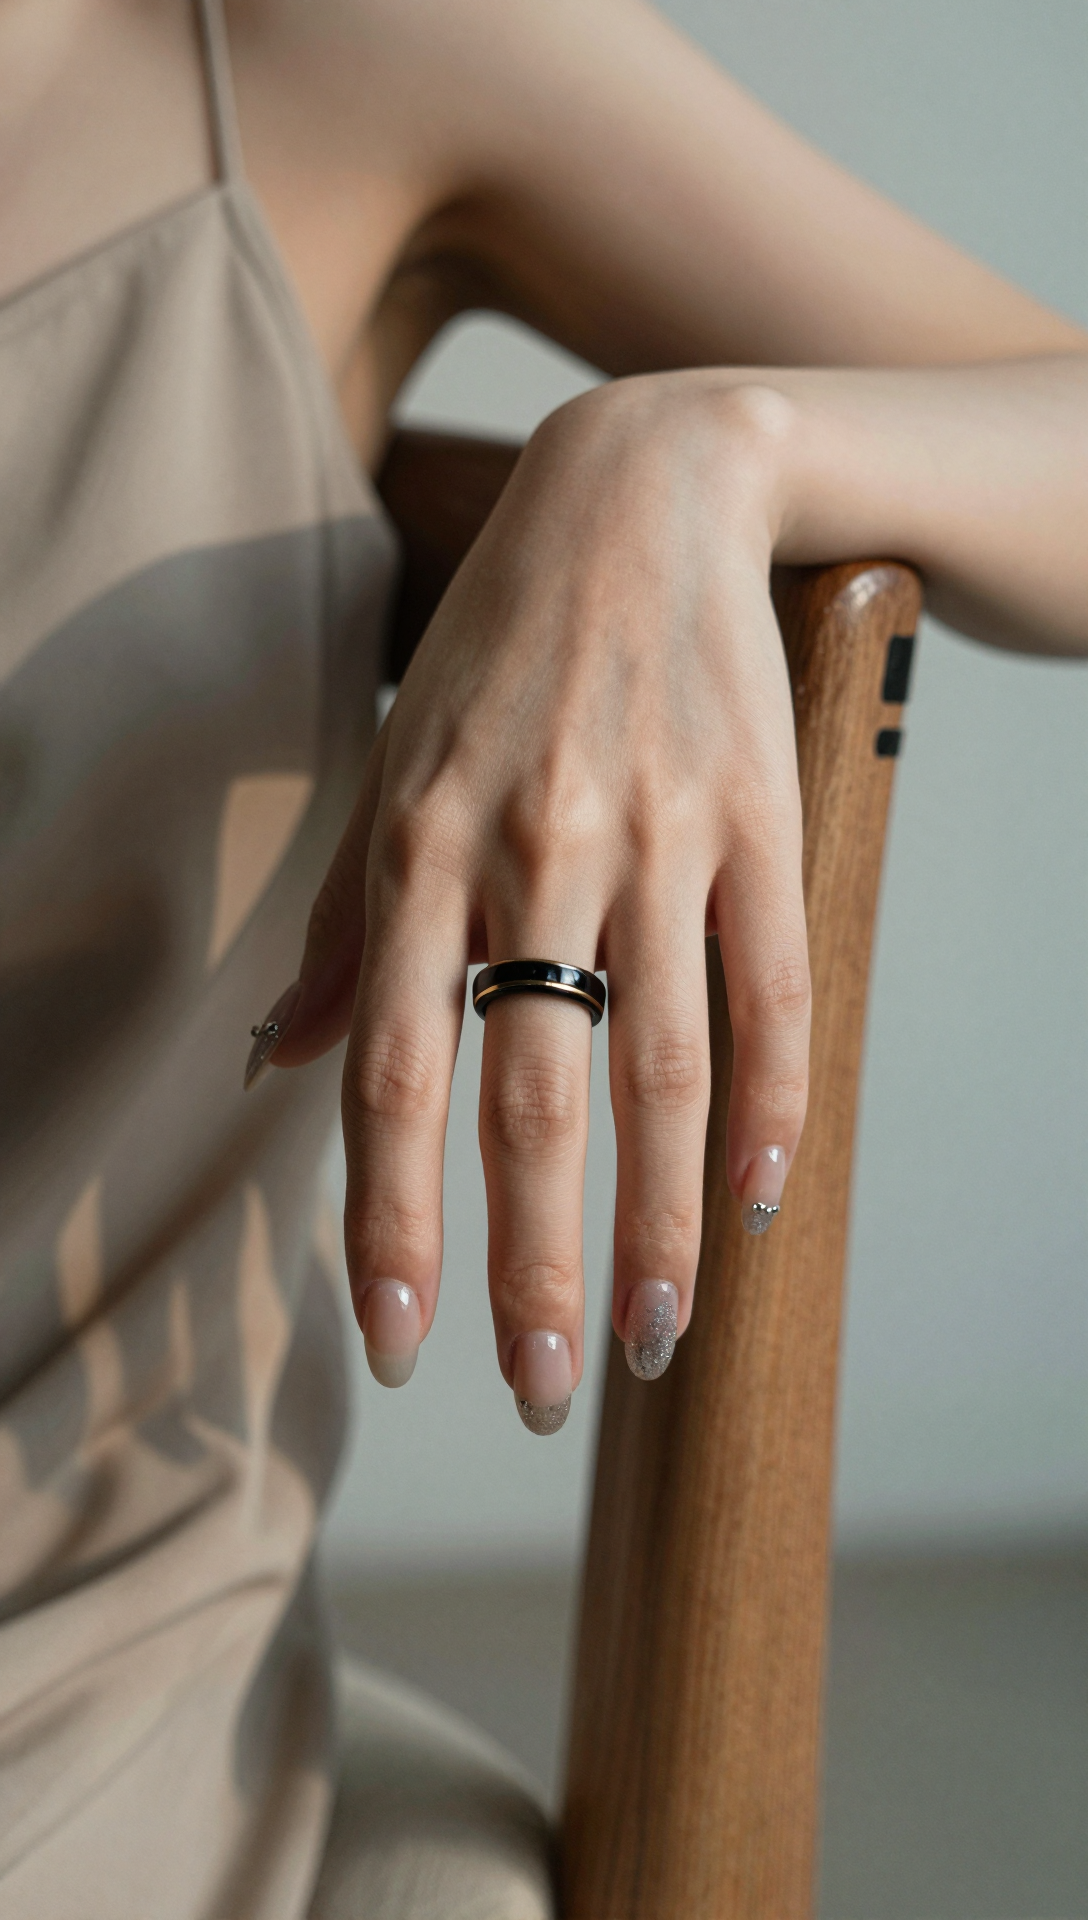
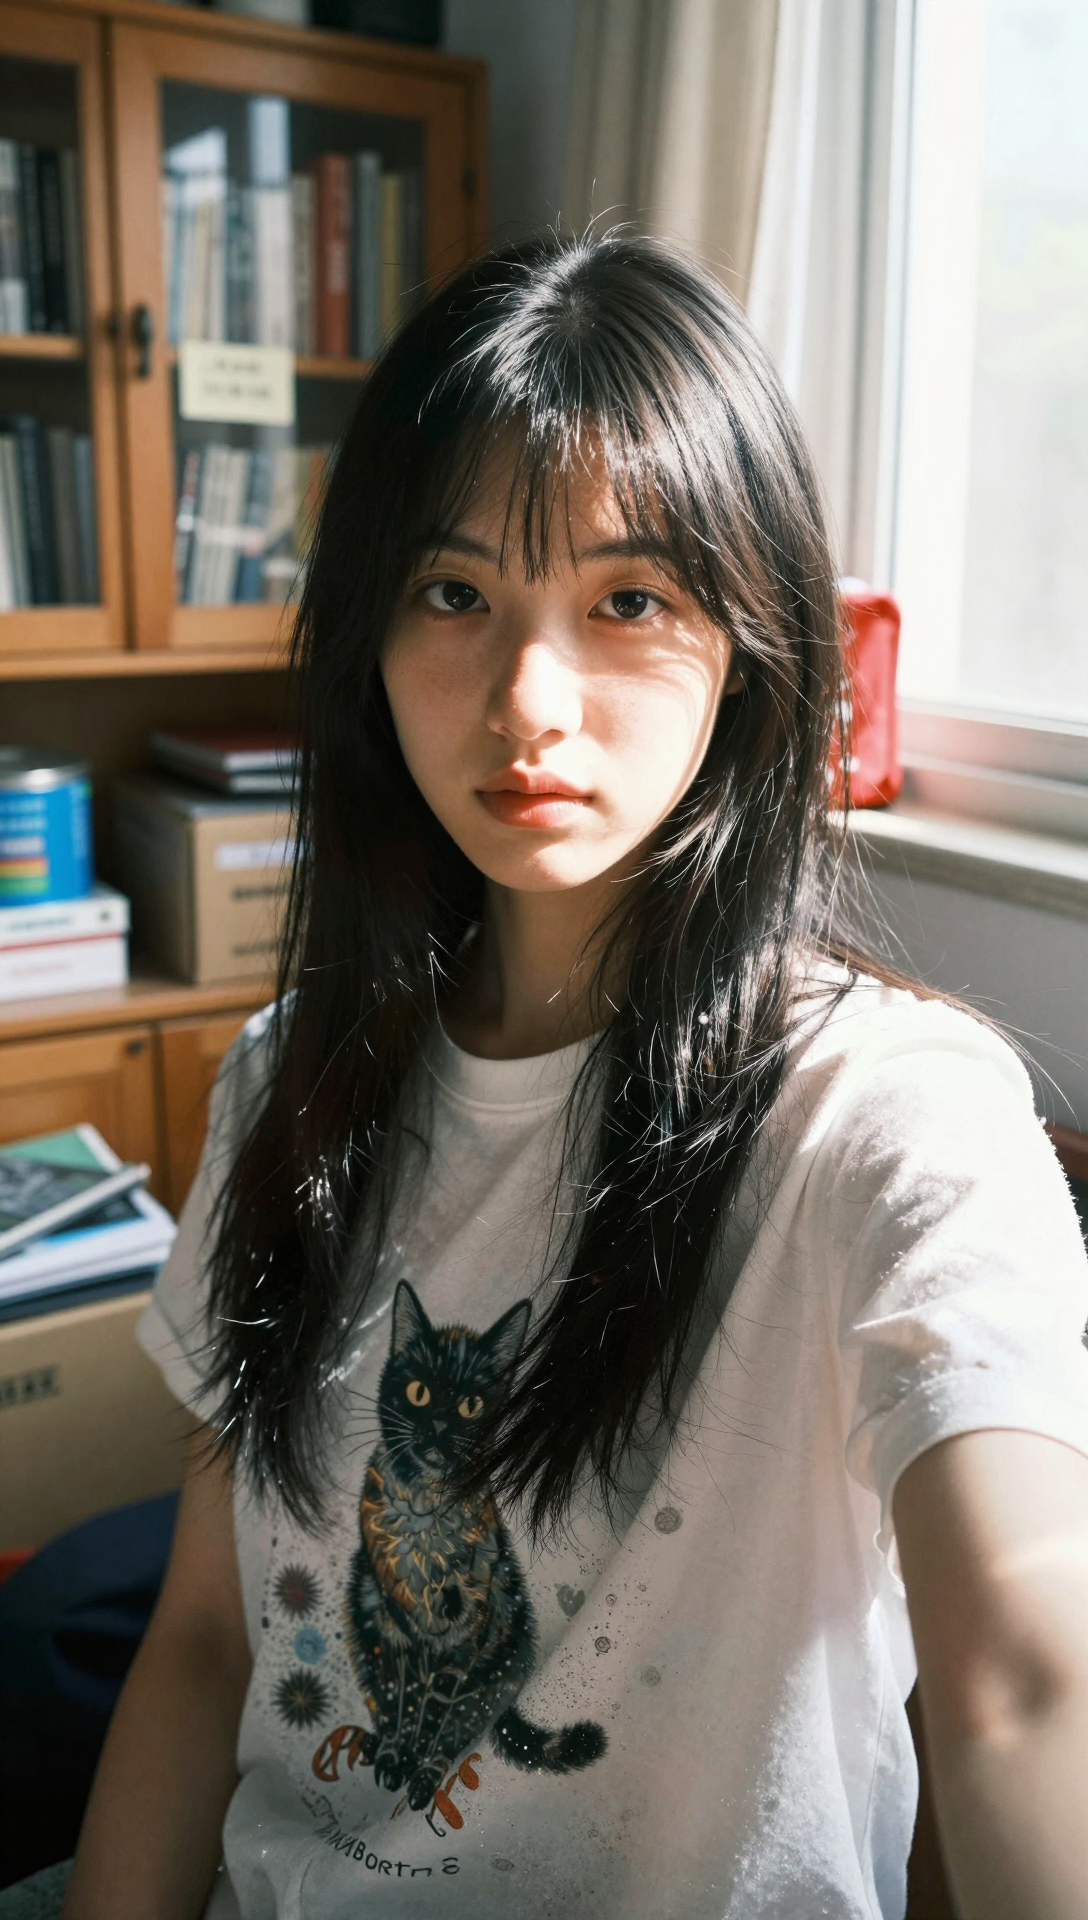
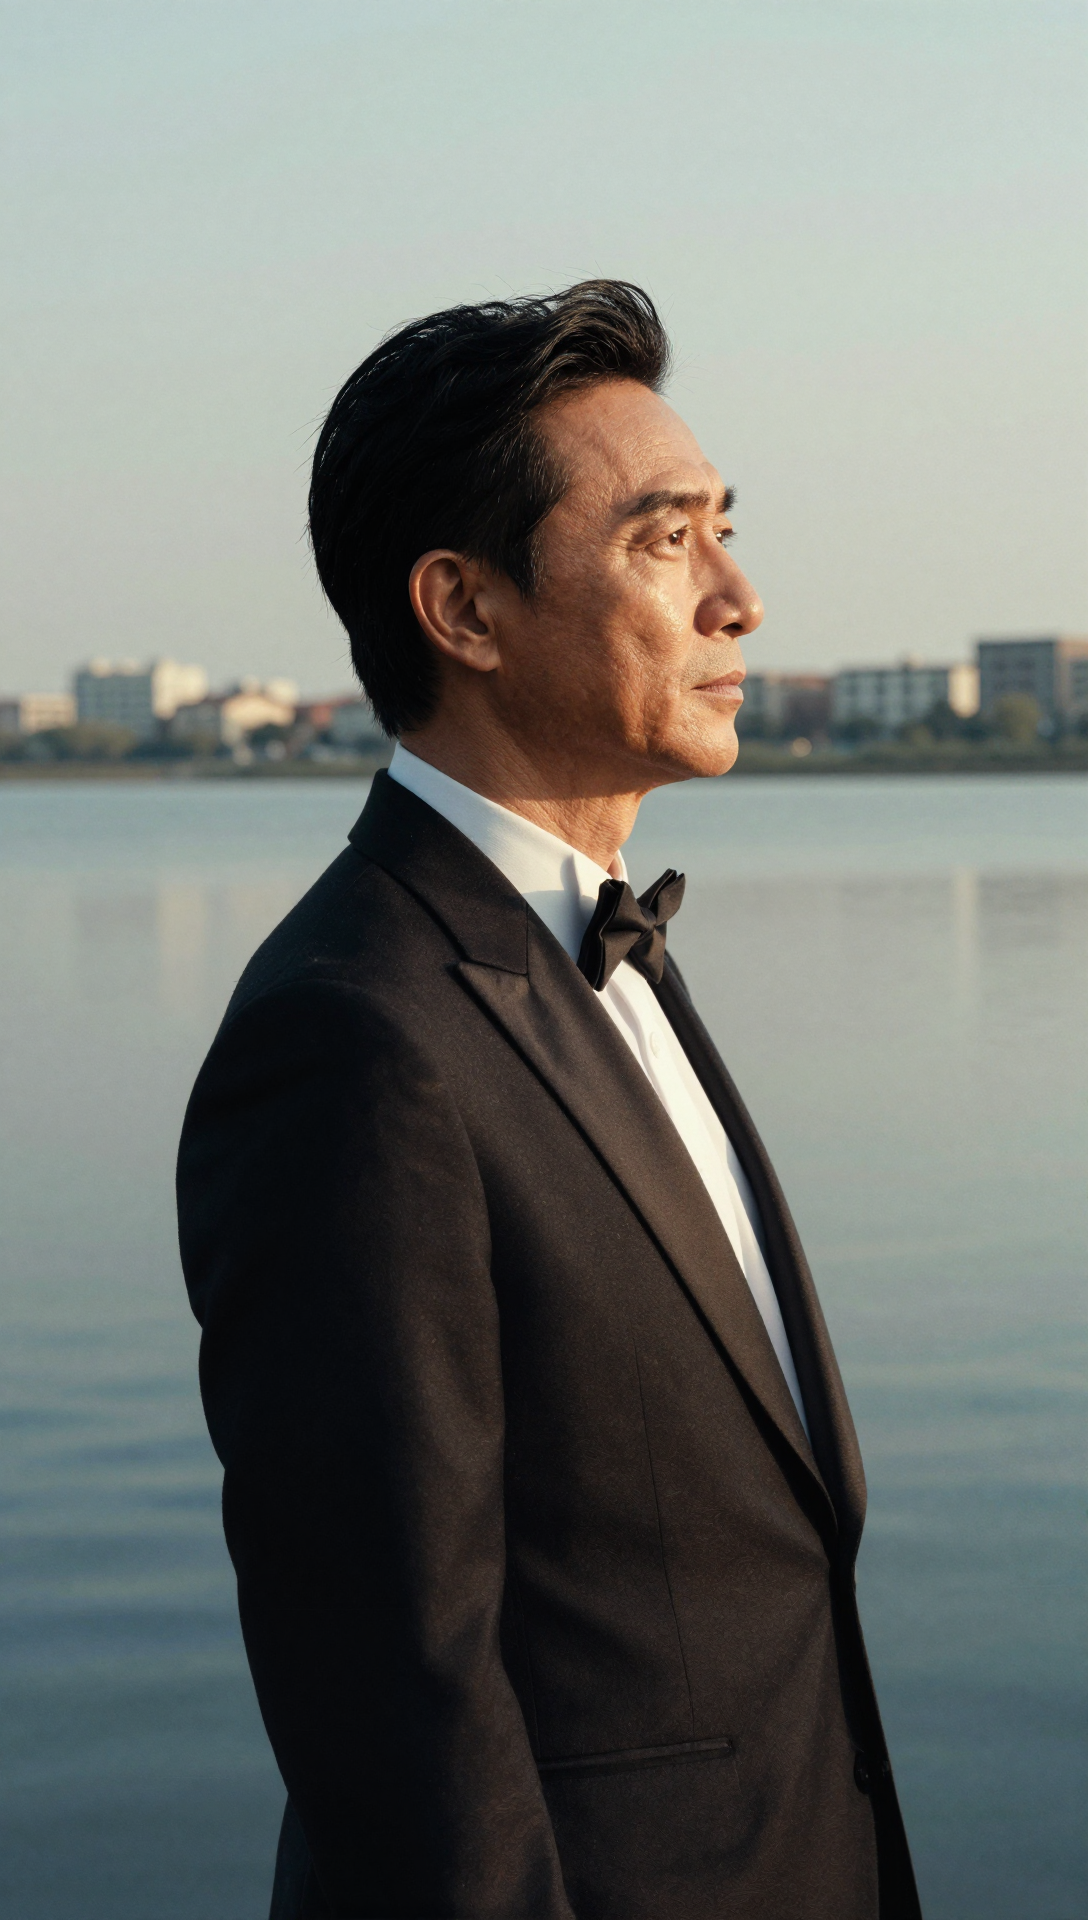
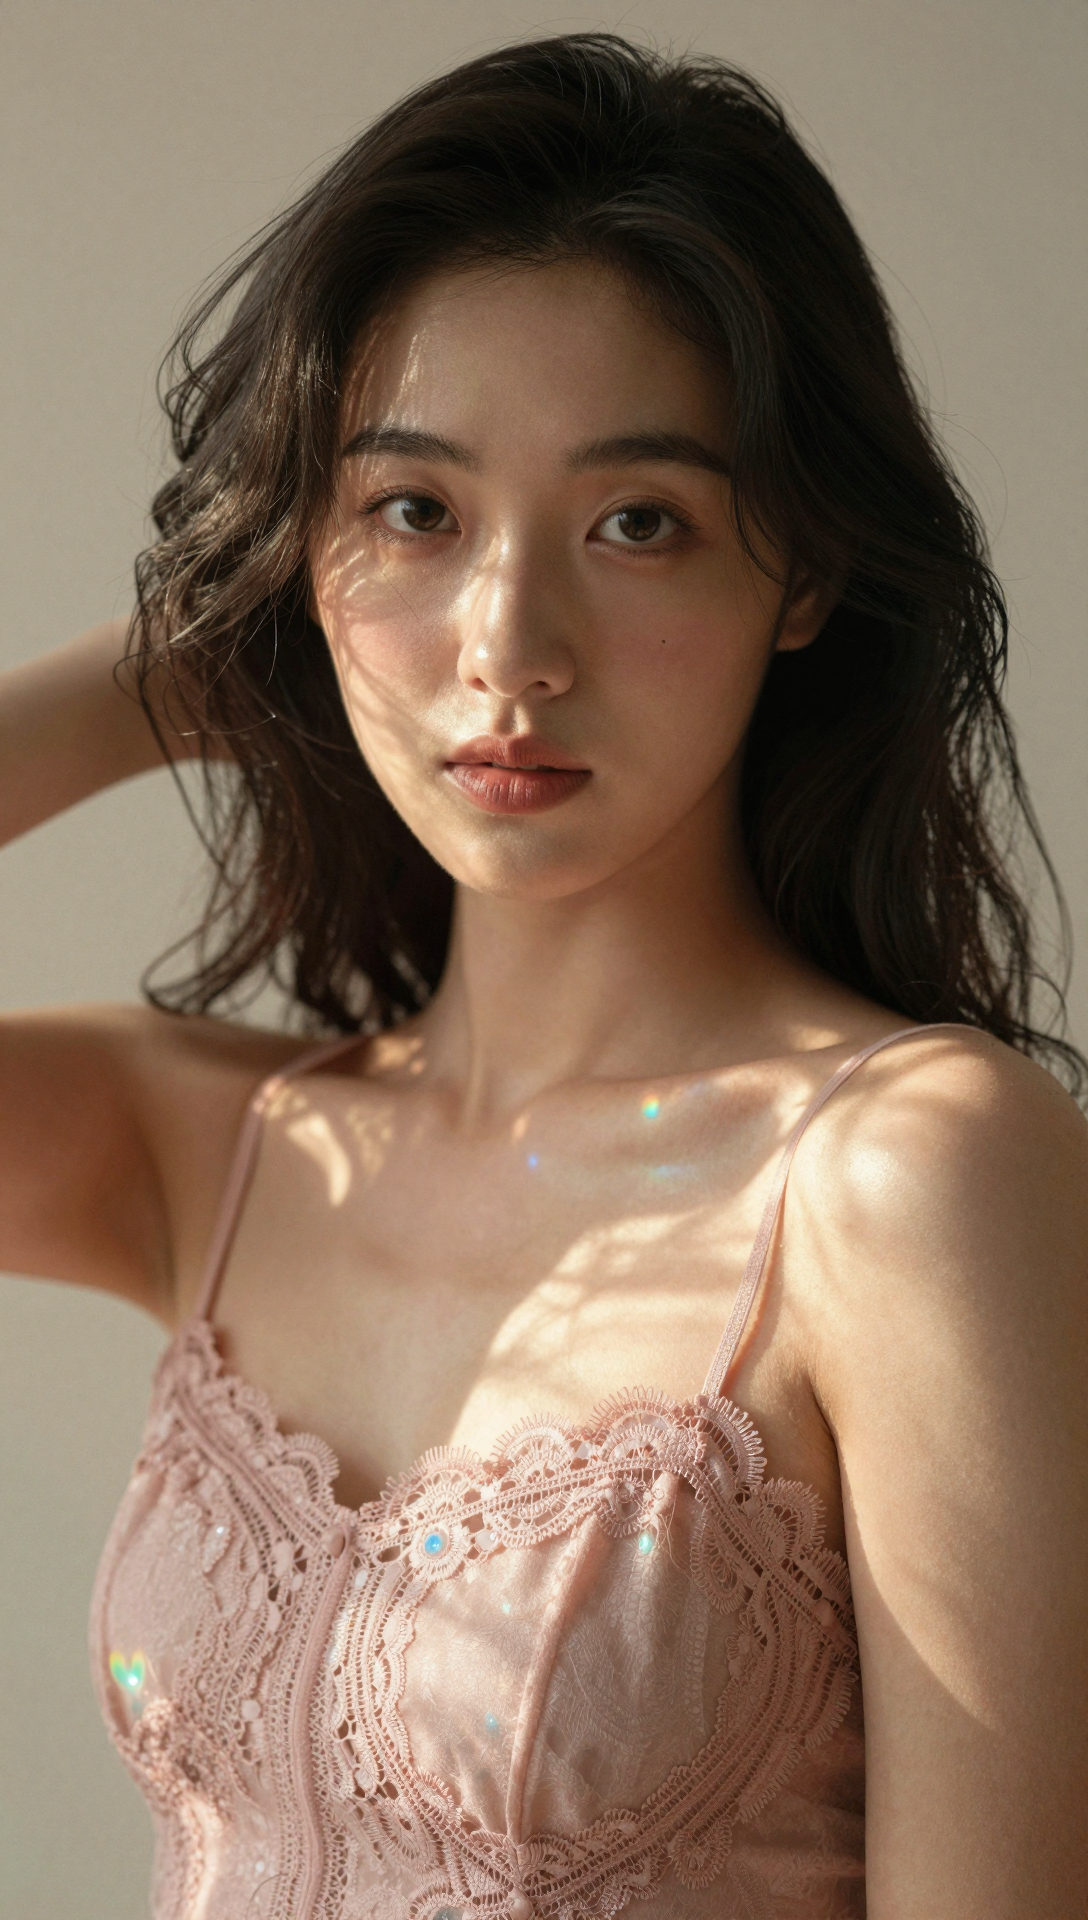
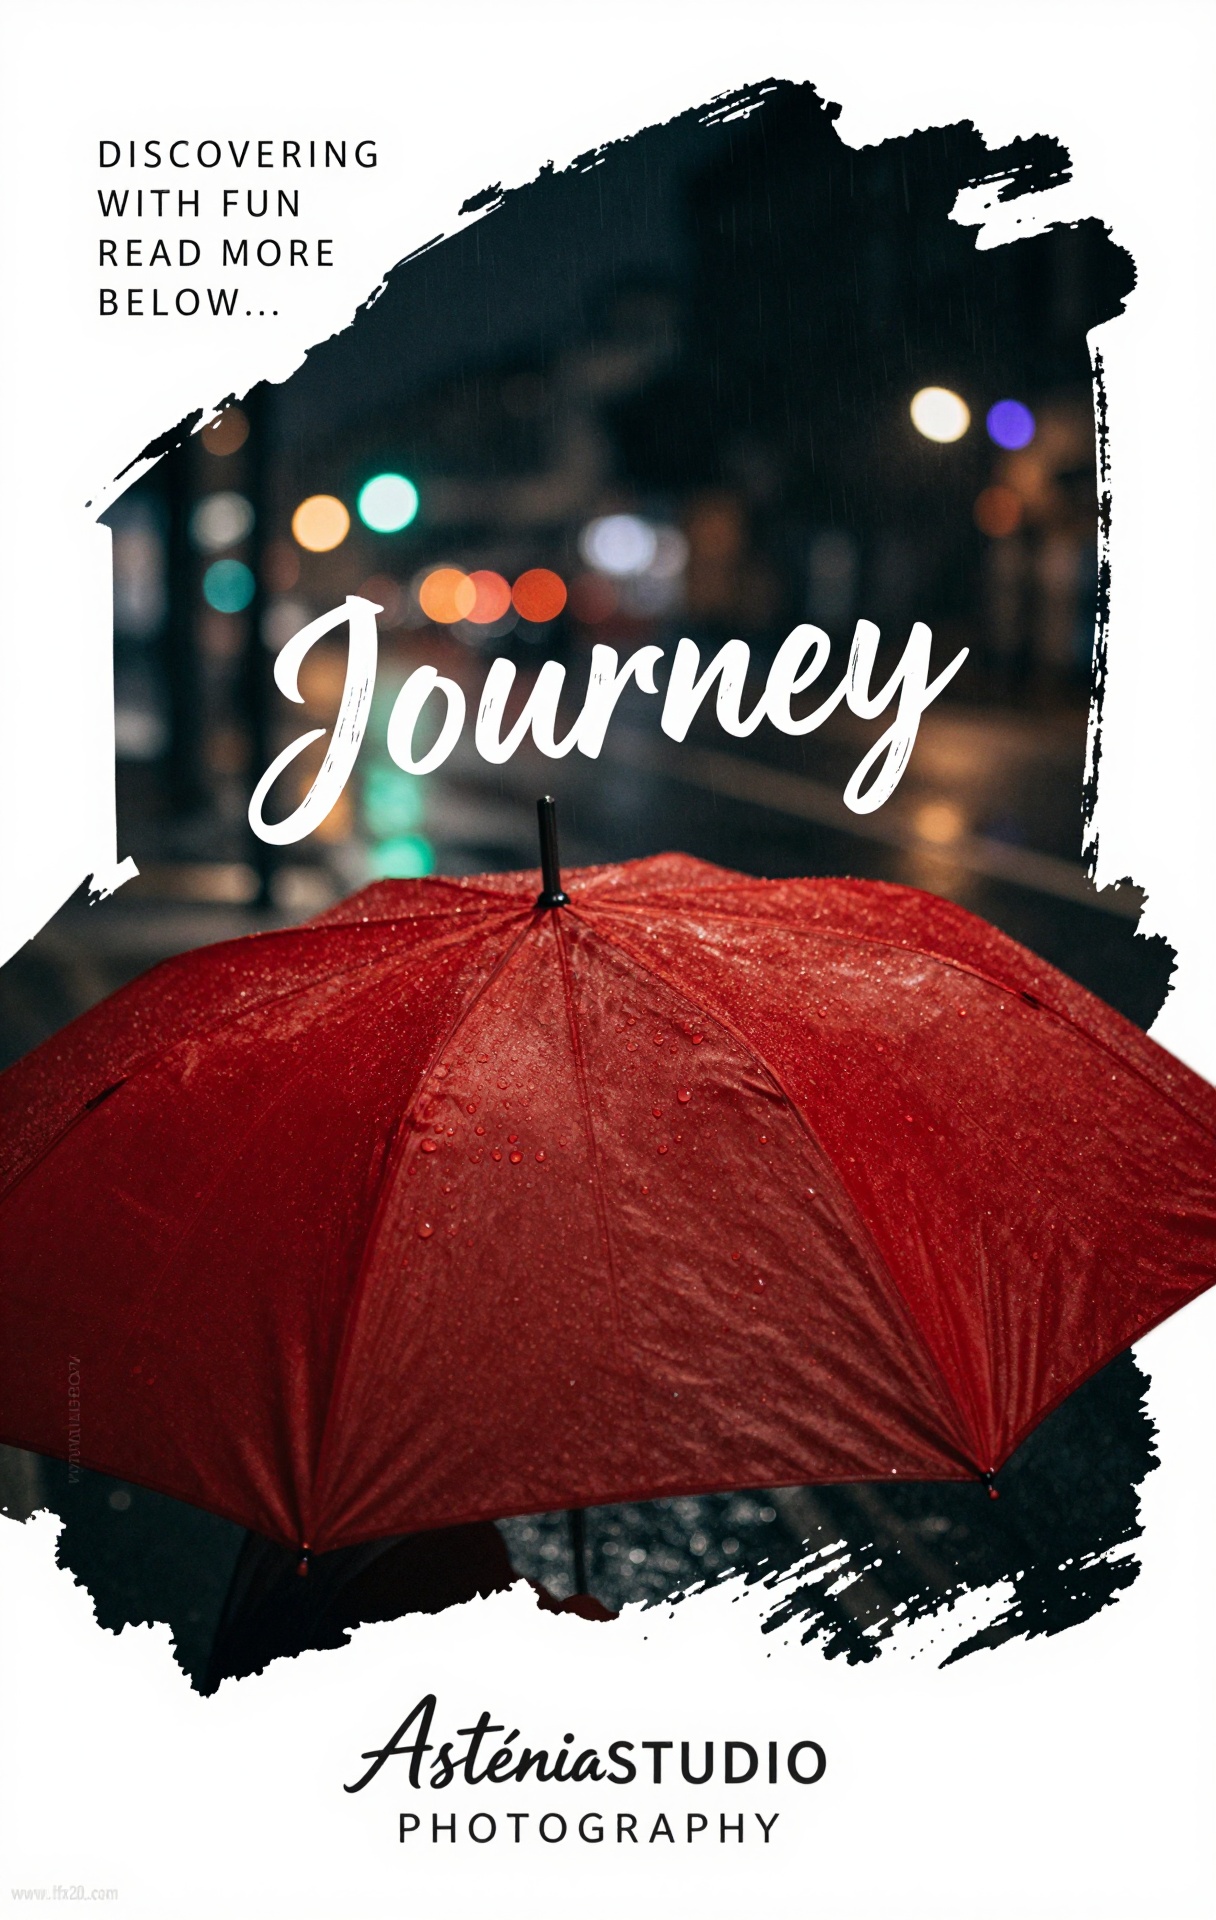
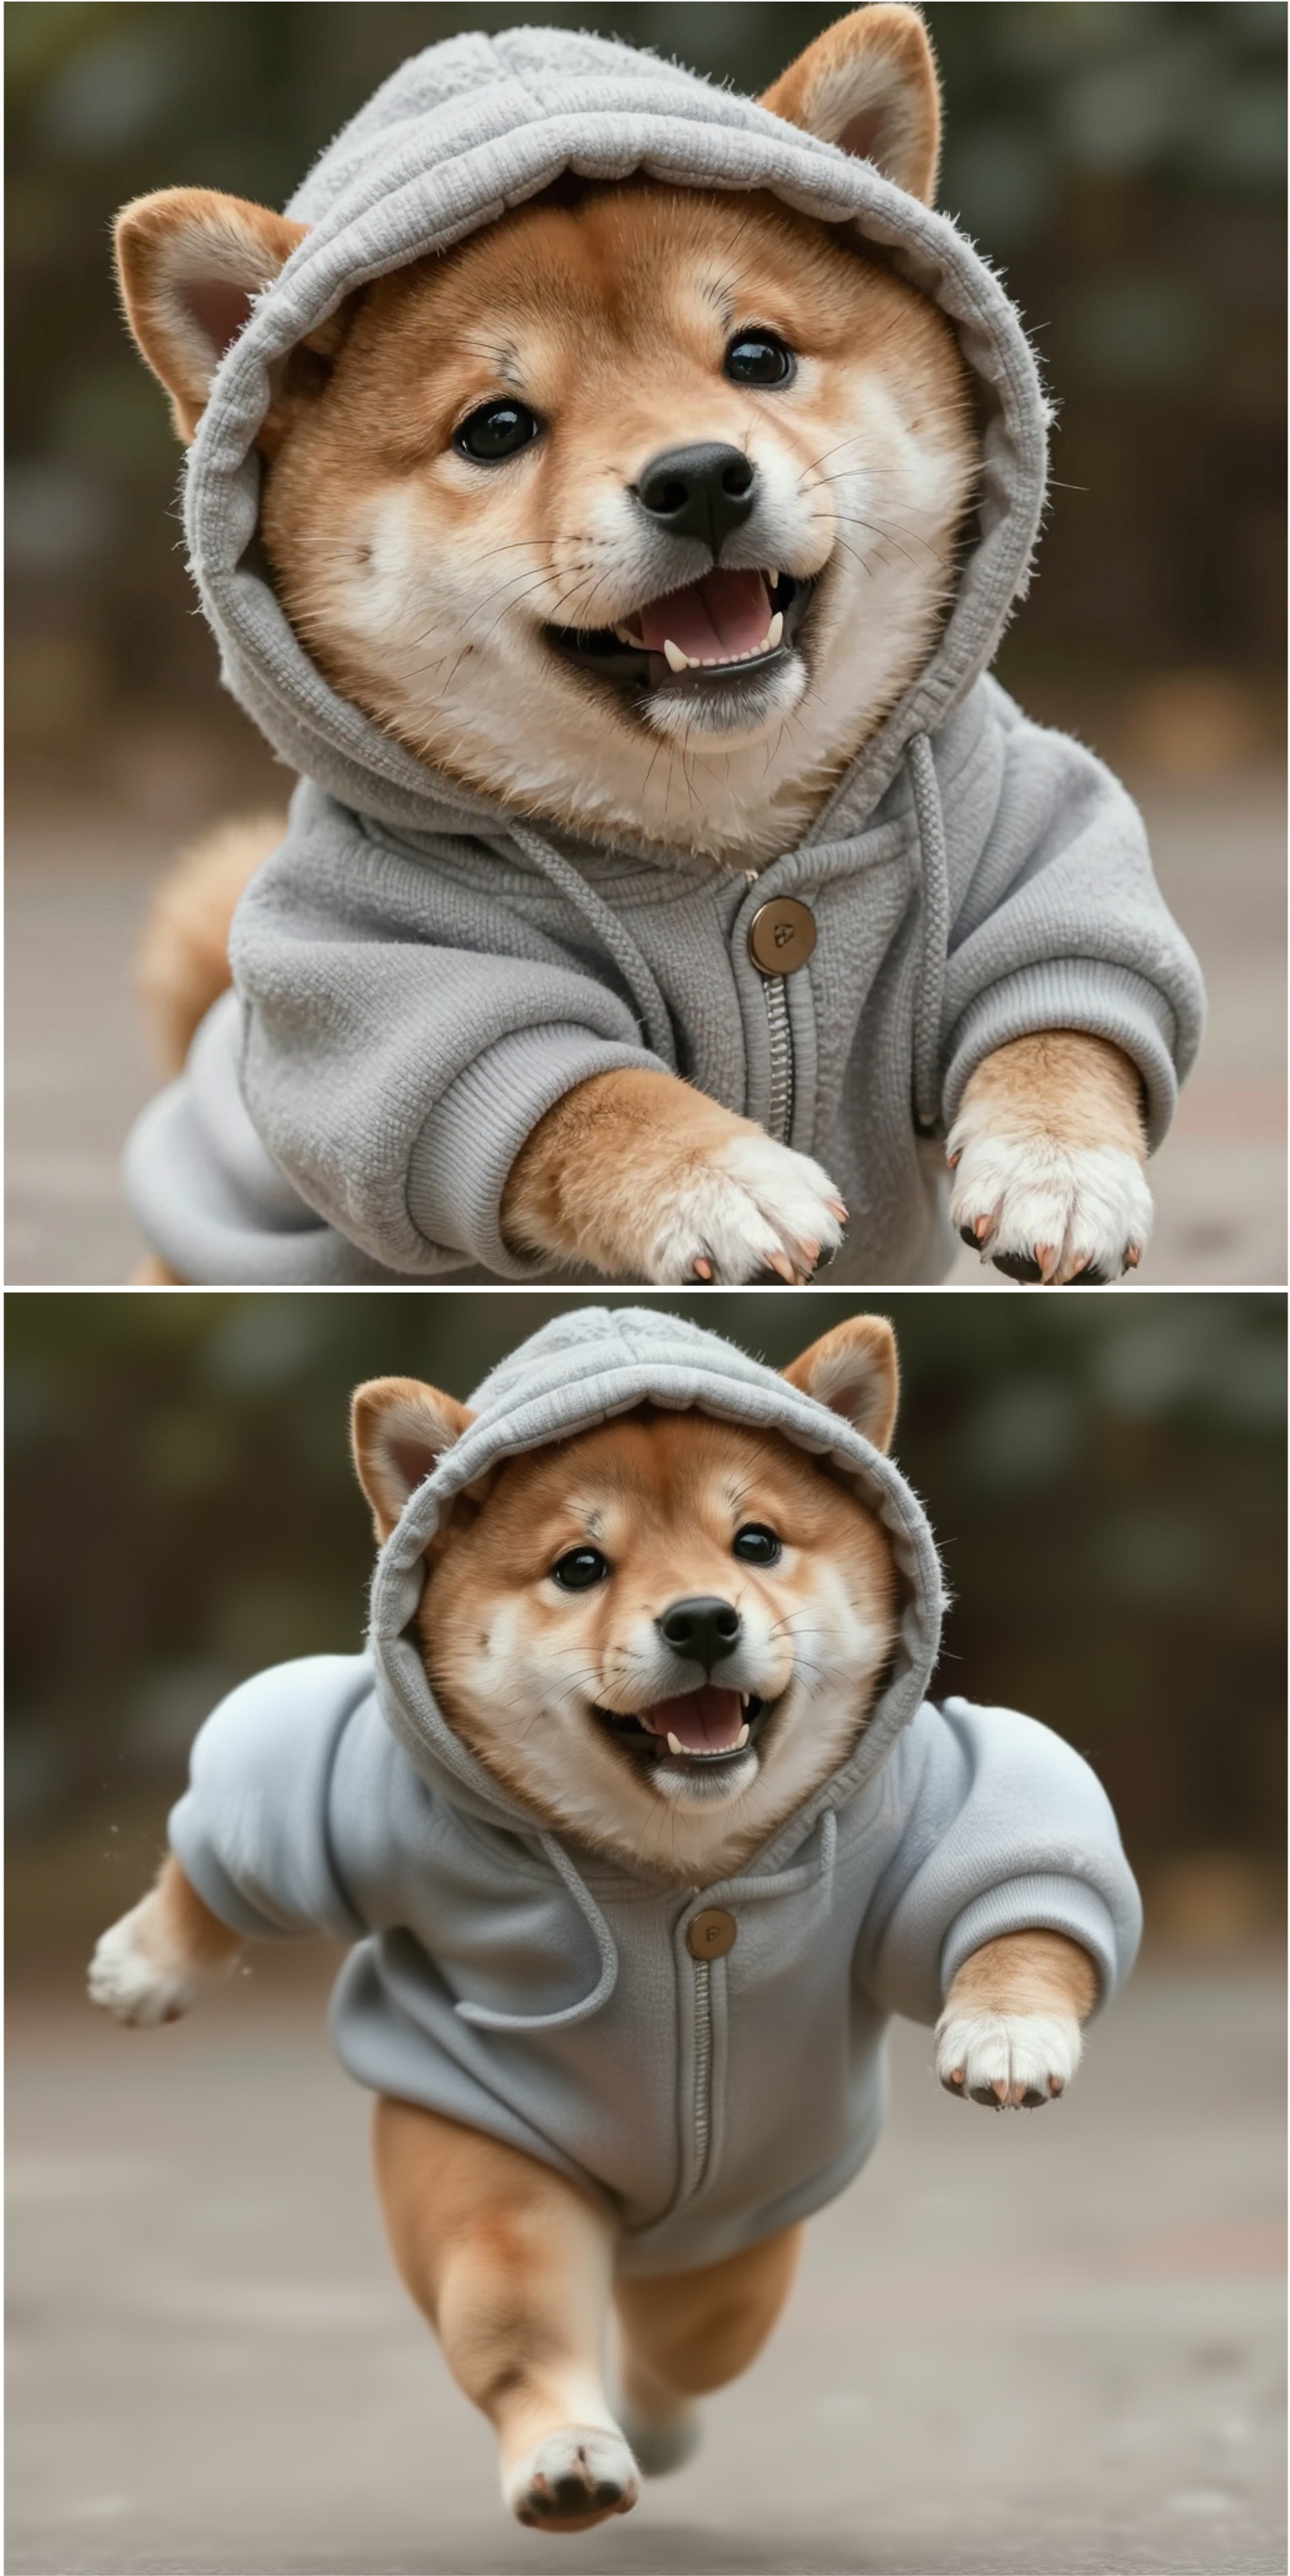
Z-Image-Turbo excels at producing images with photography-level realism, demonstrating fine control over details, lighting, and textures. It balances high fidelity with strong aesthetic quality in composition and overall mood.
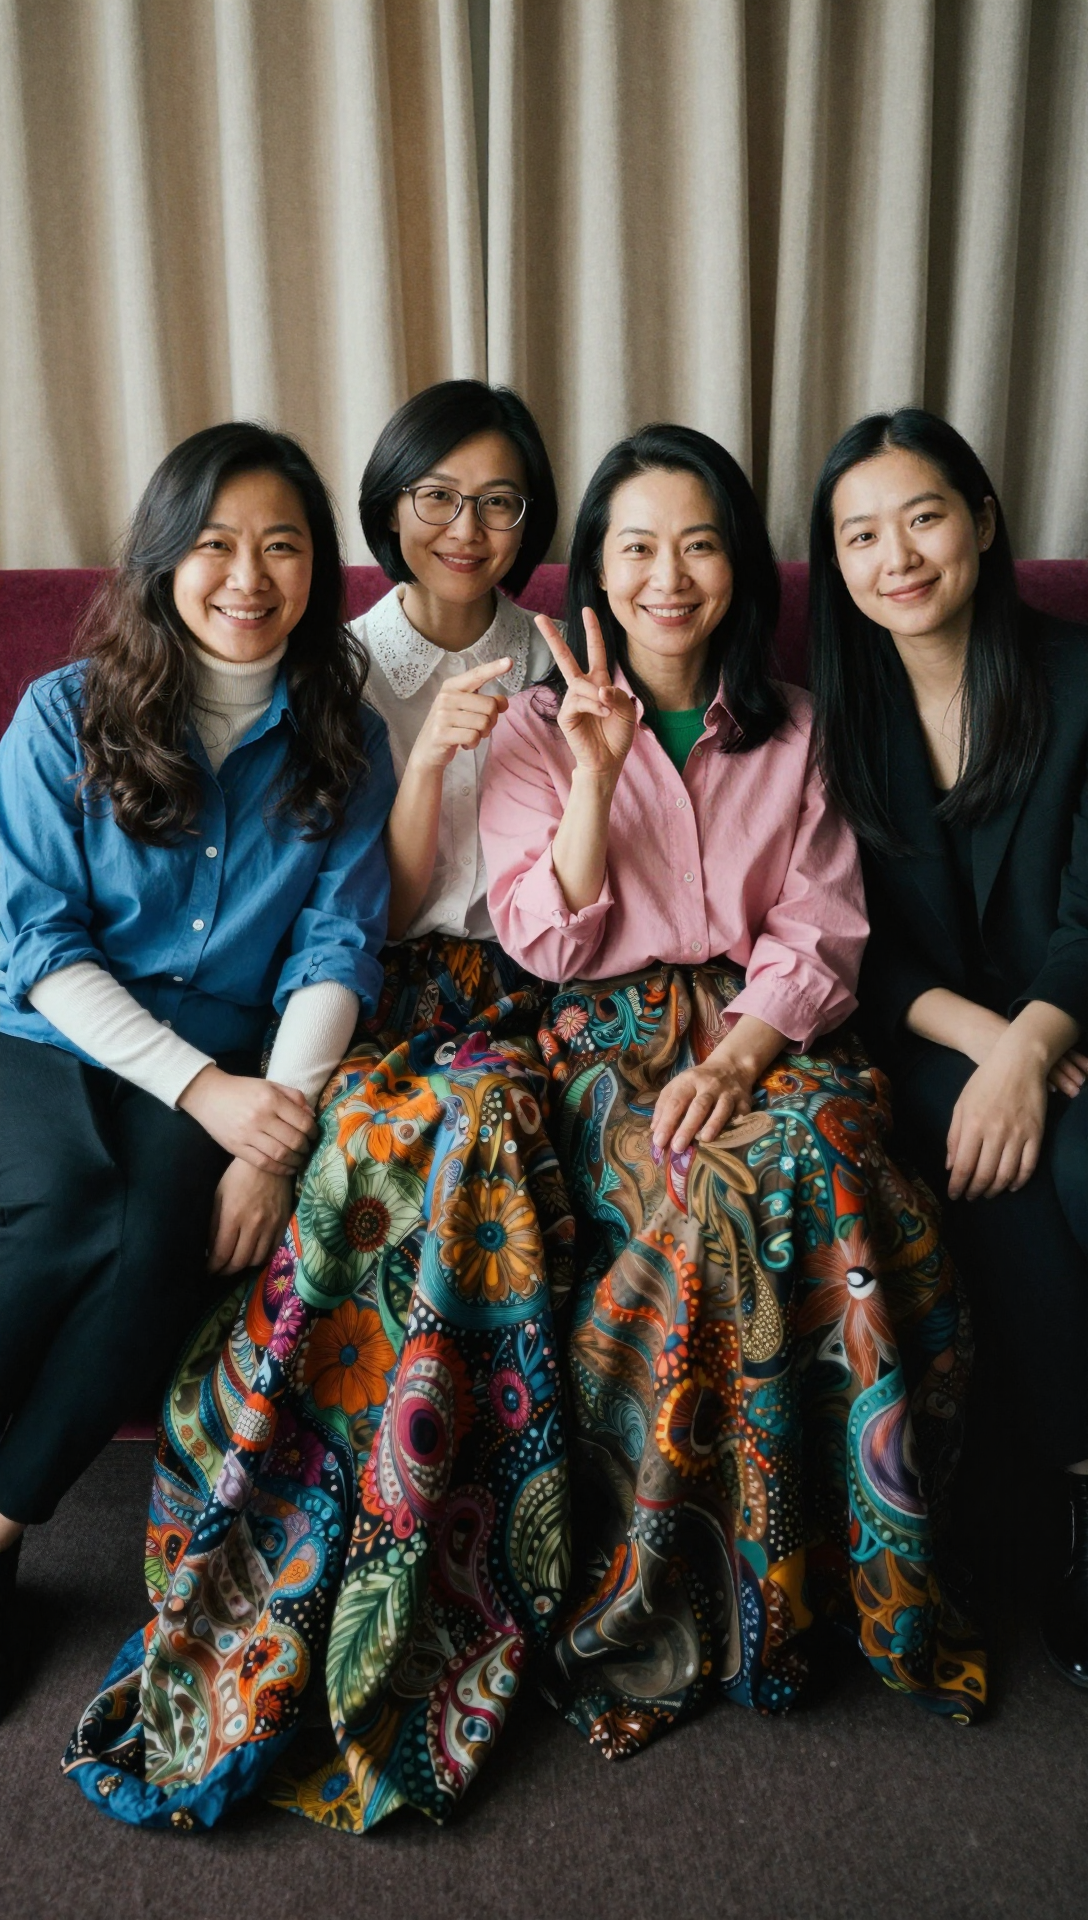
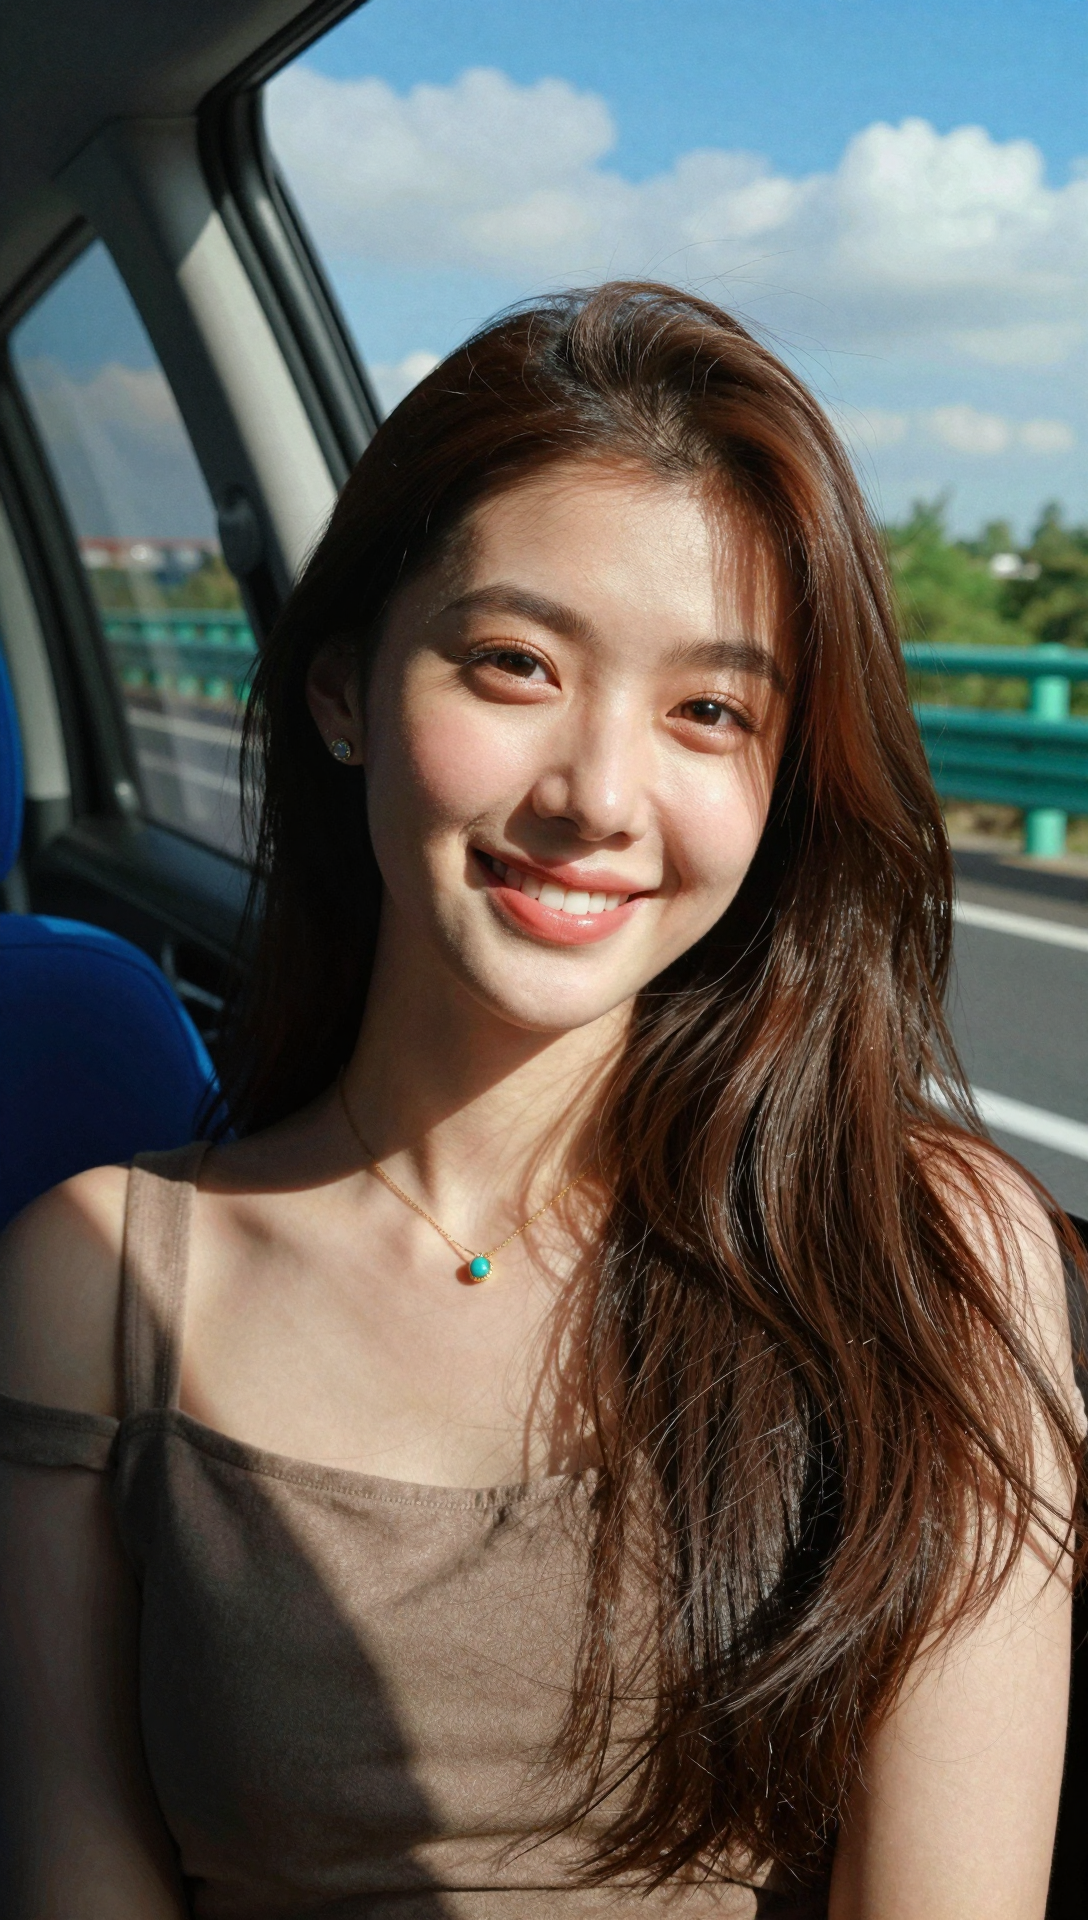
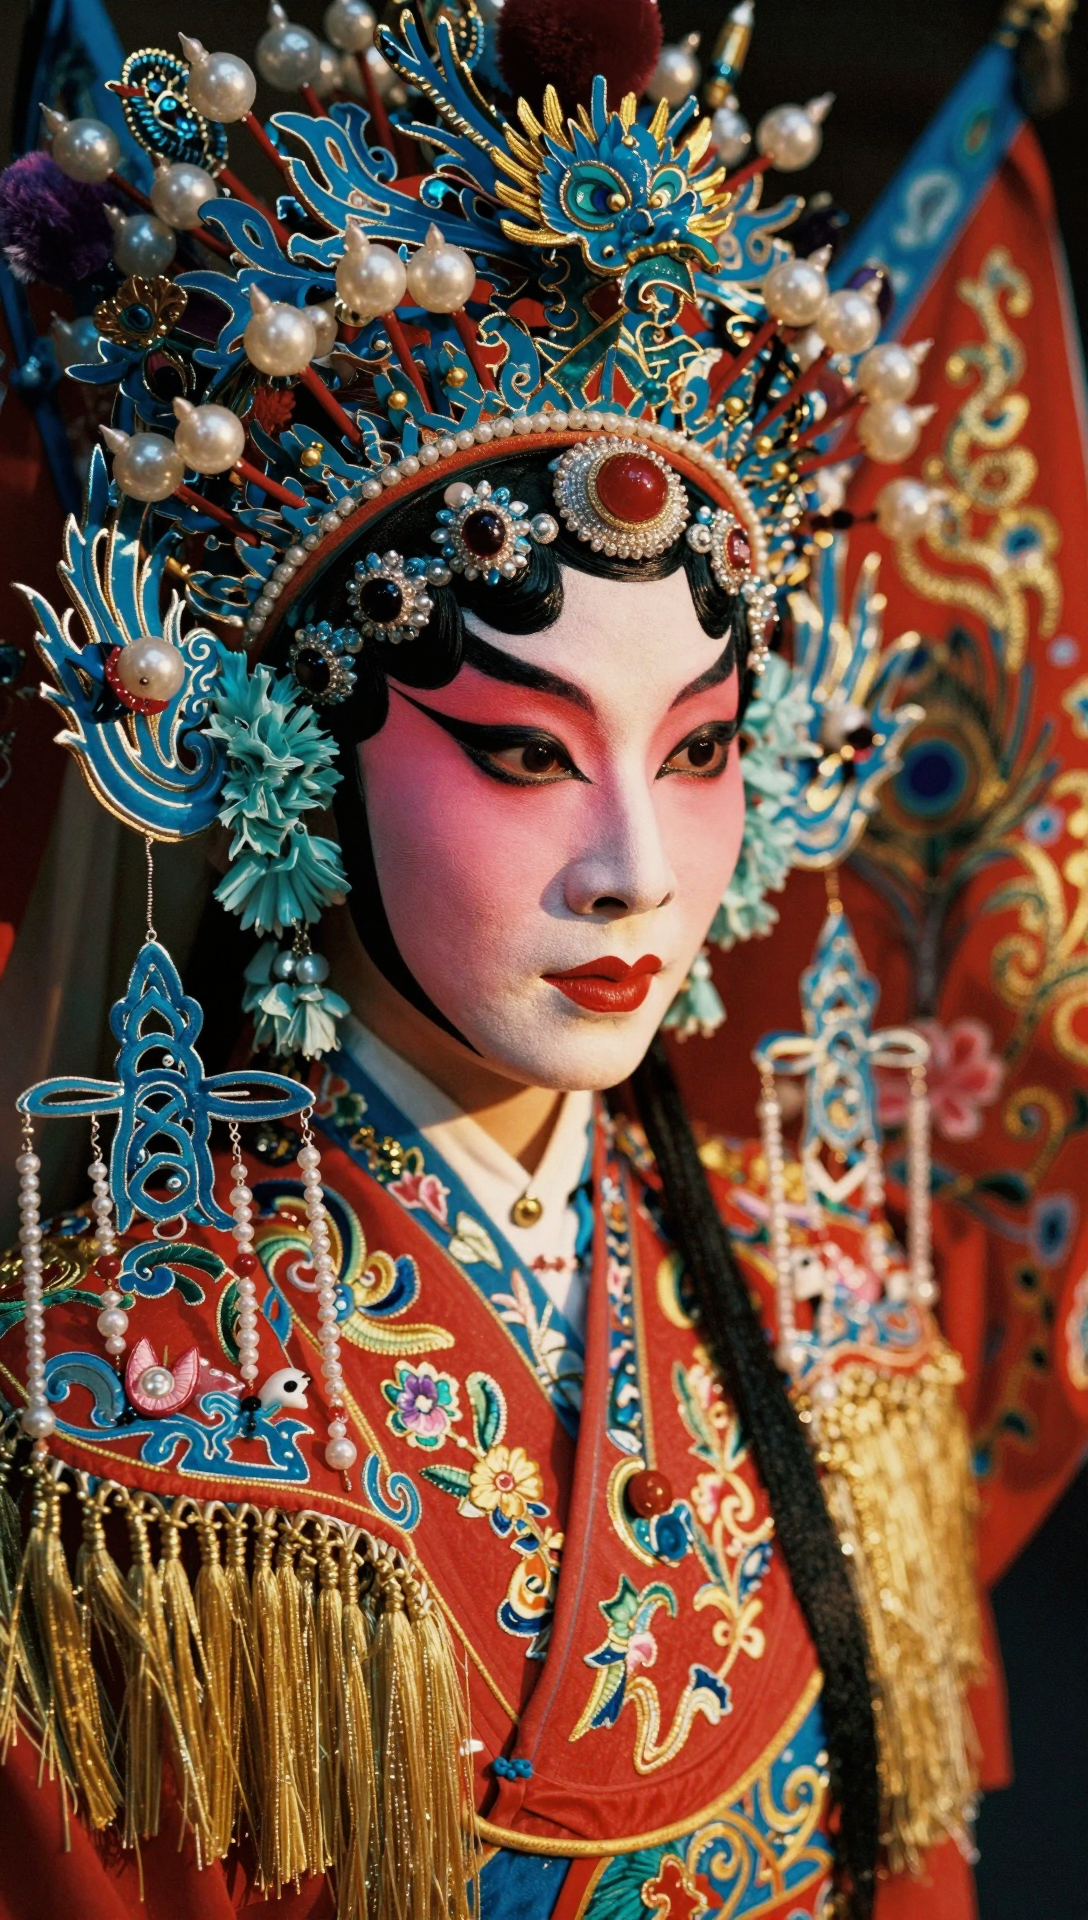
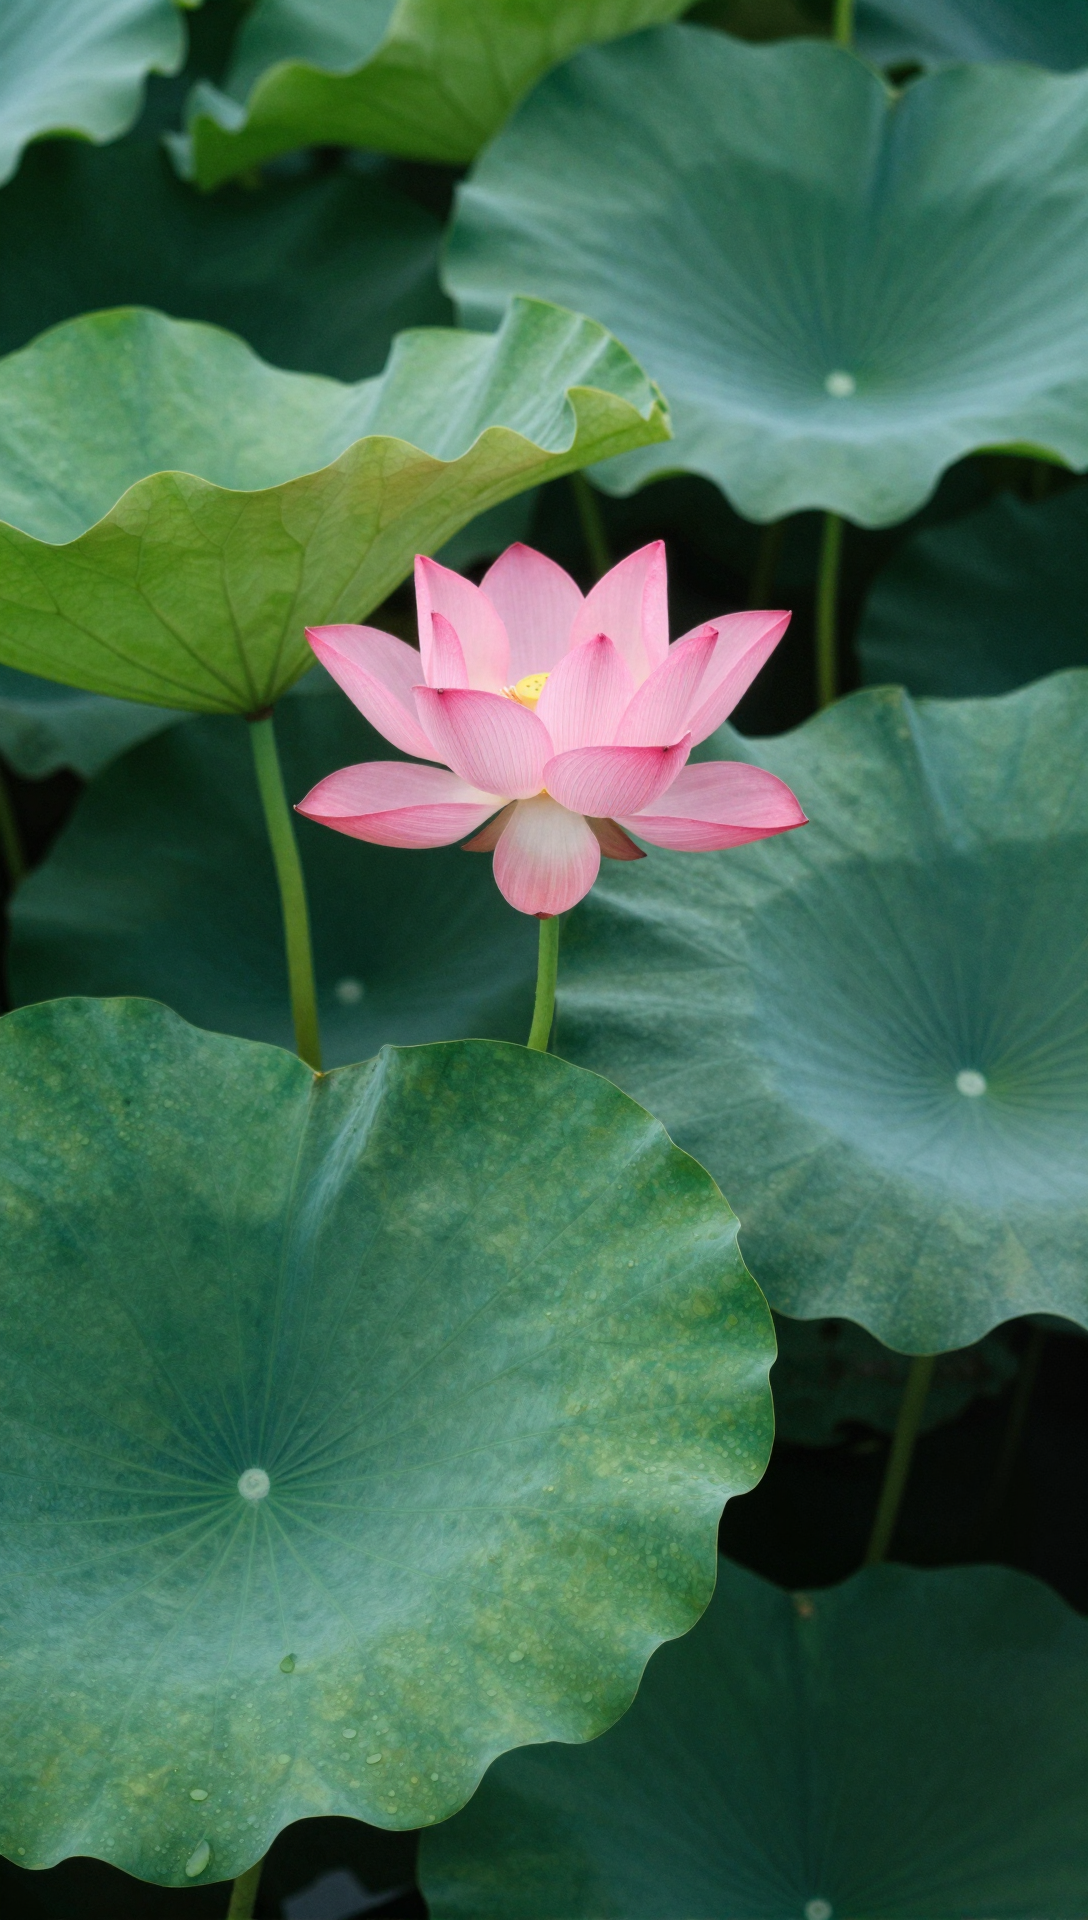
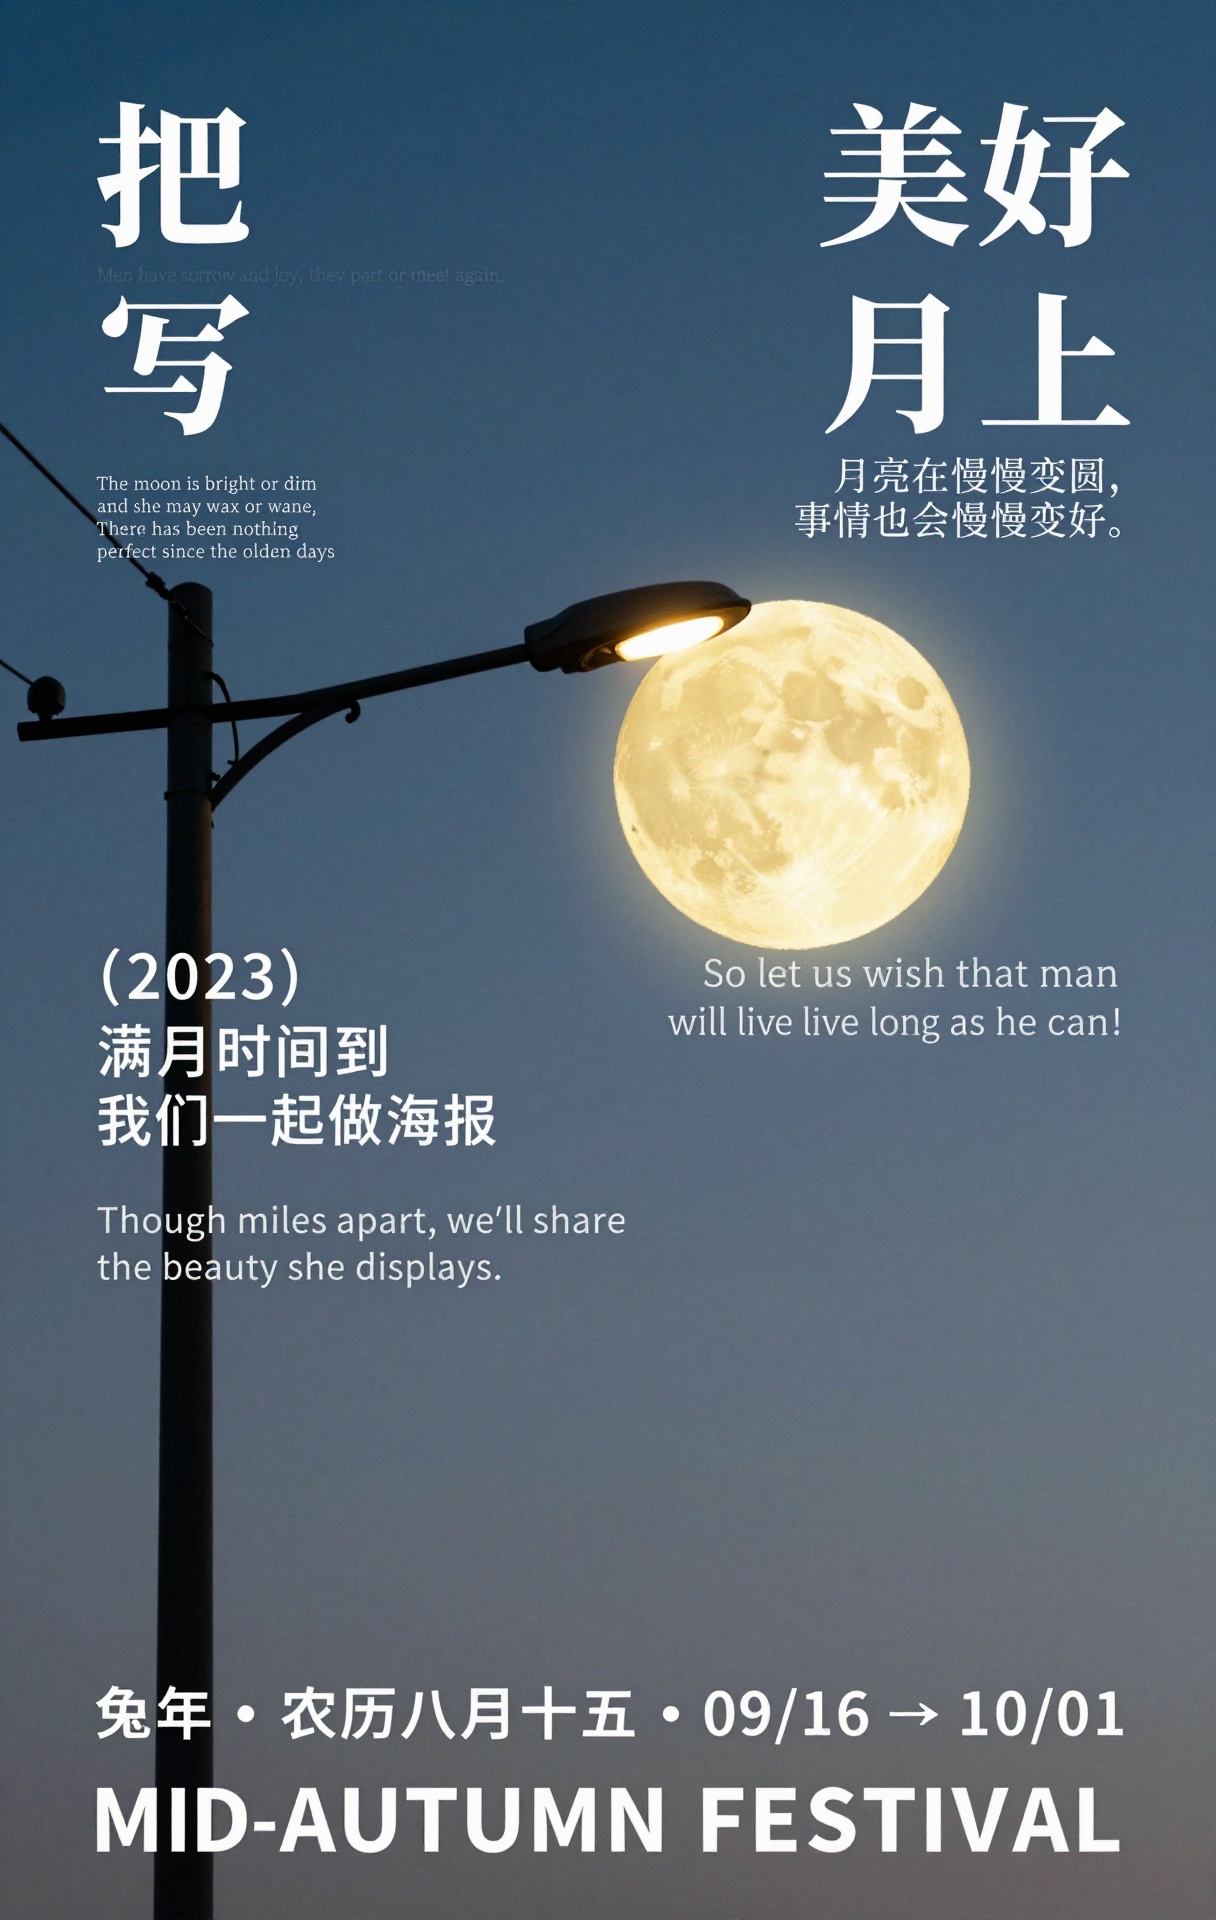
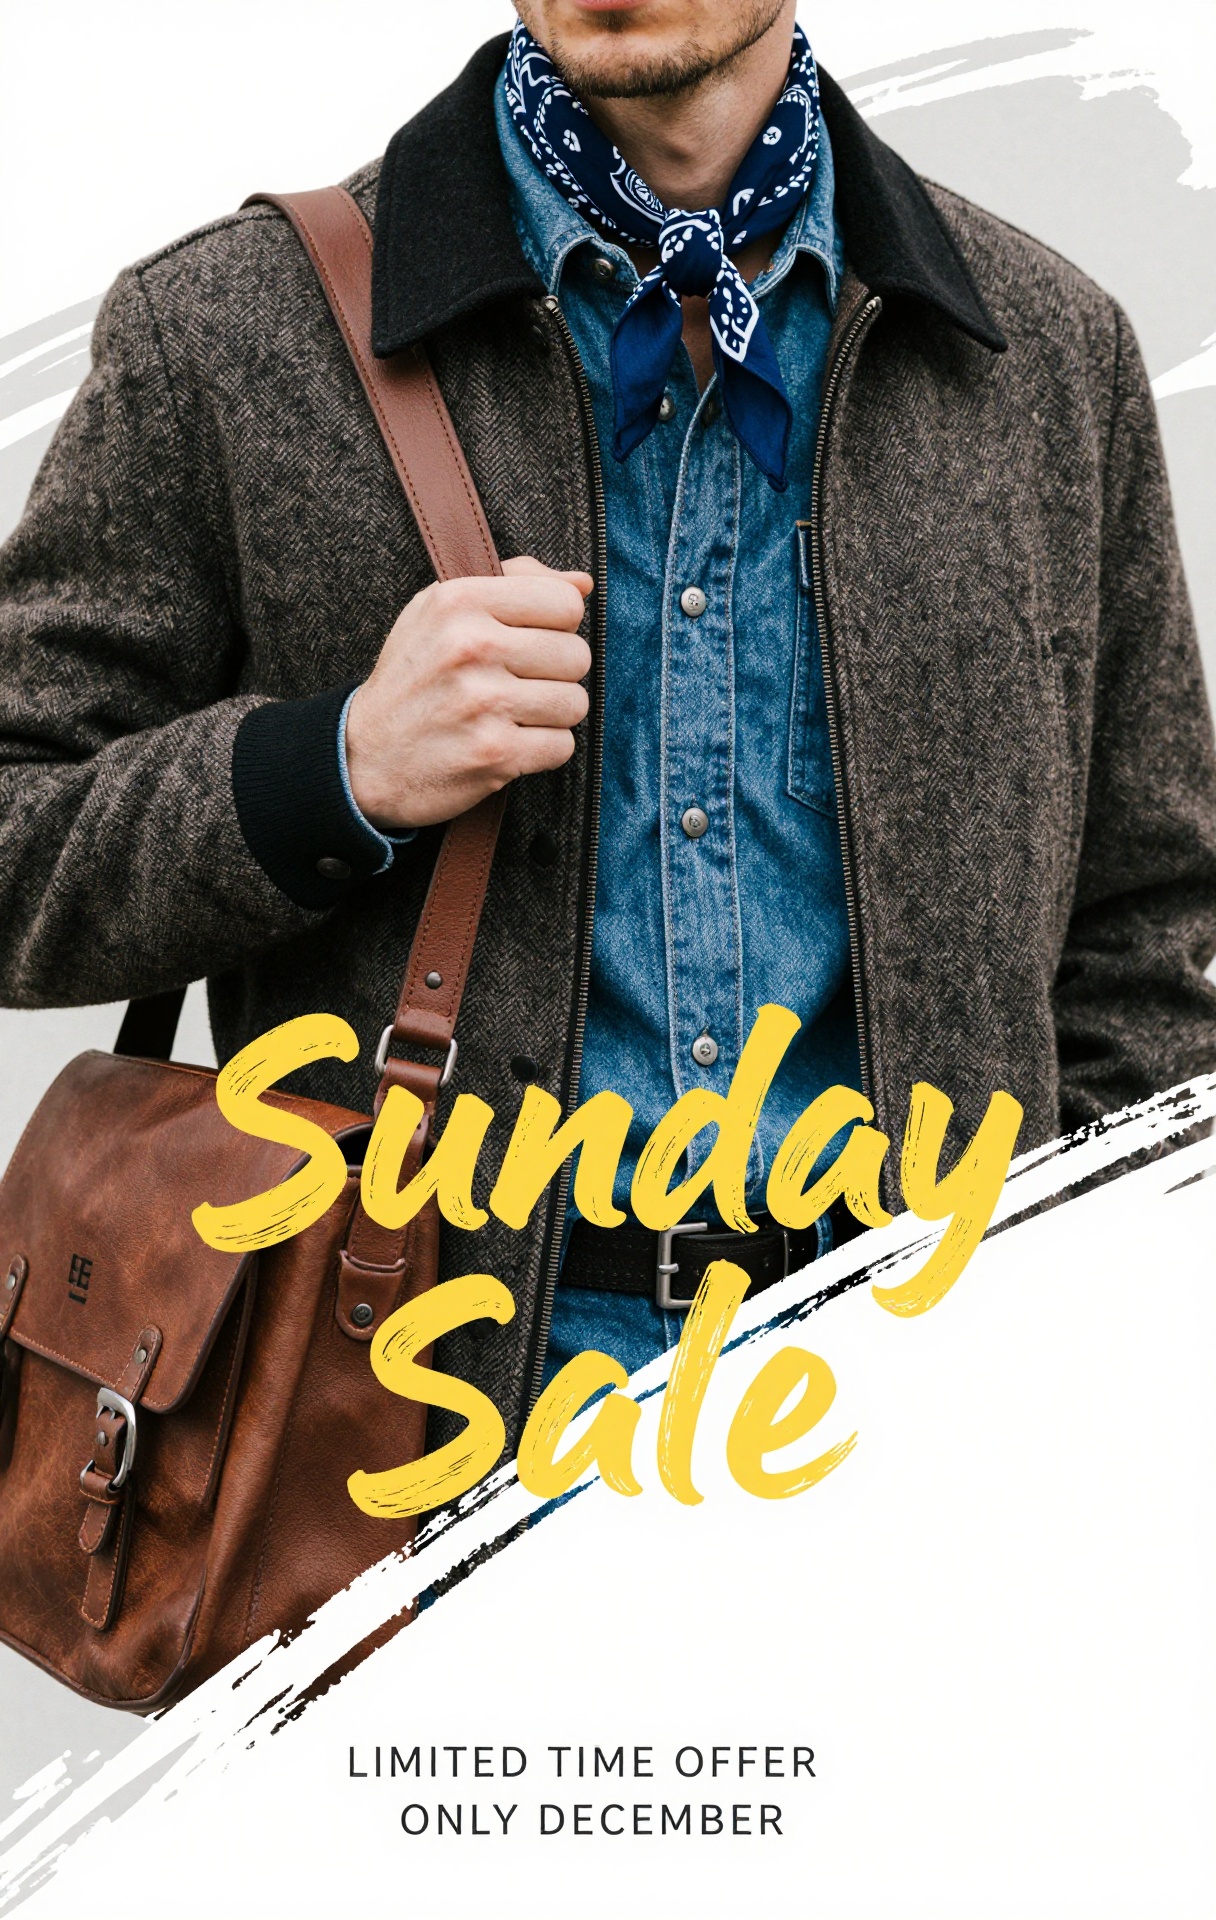
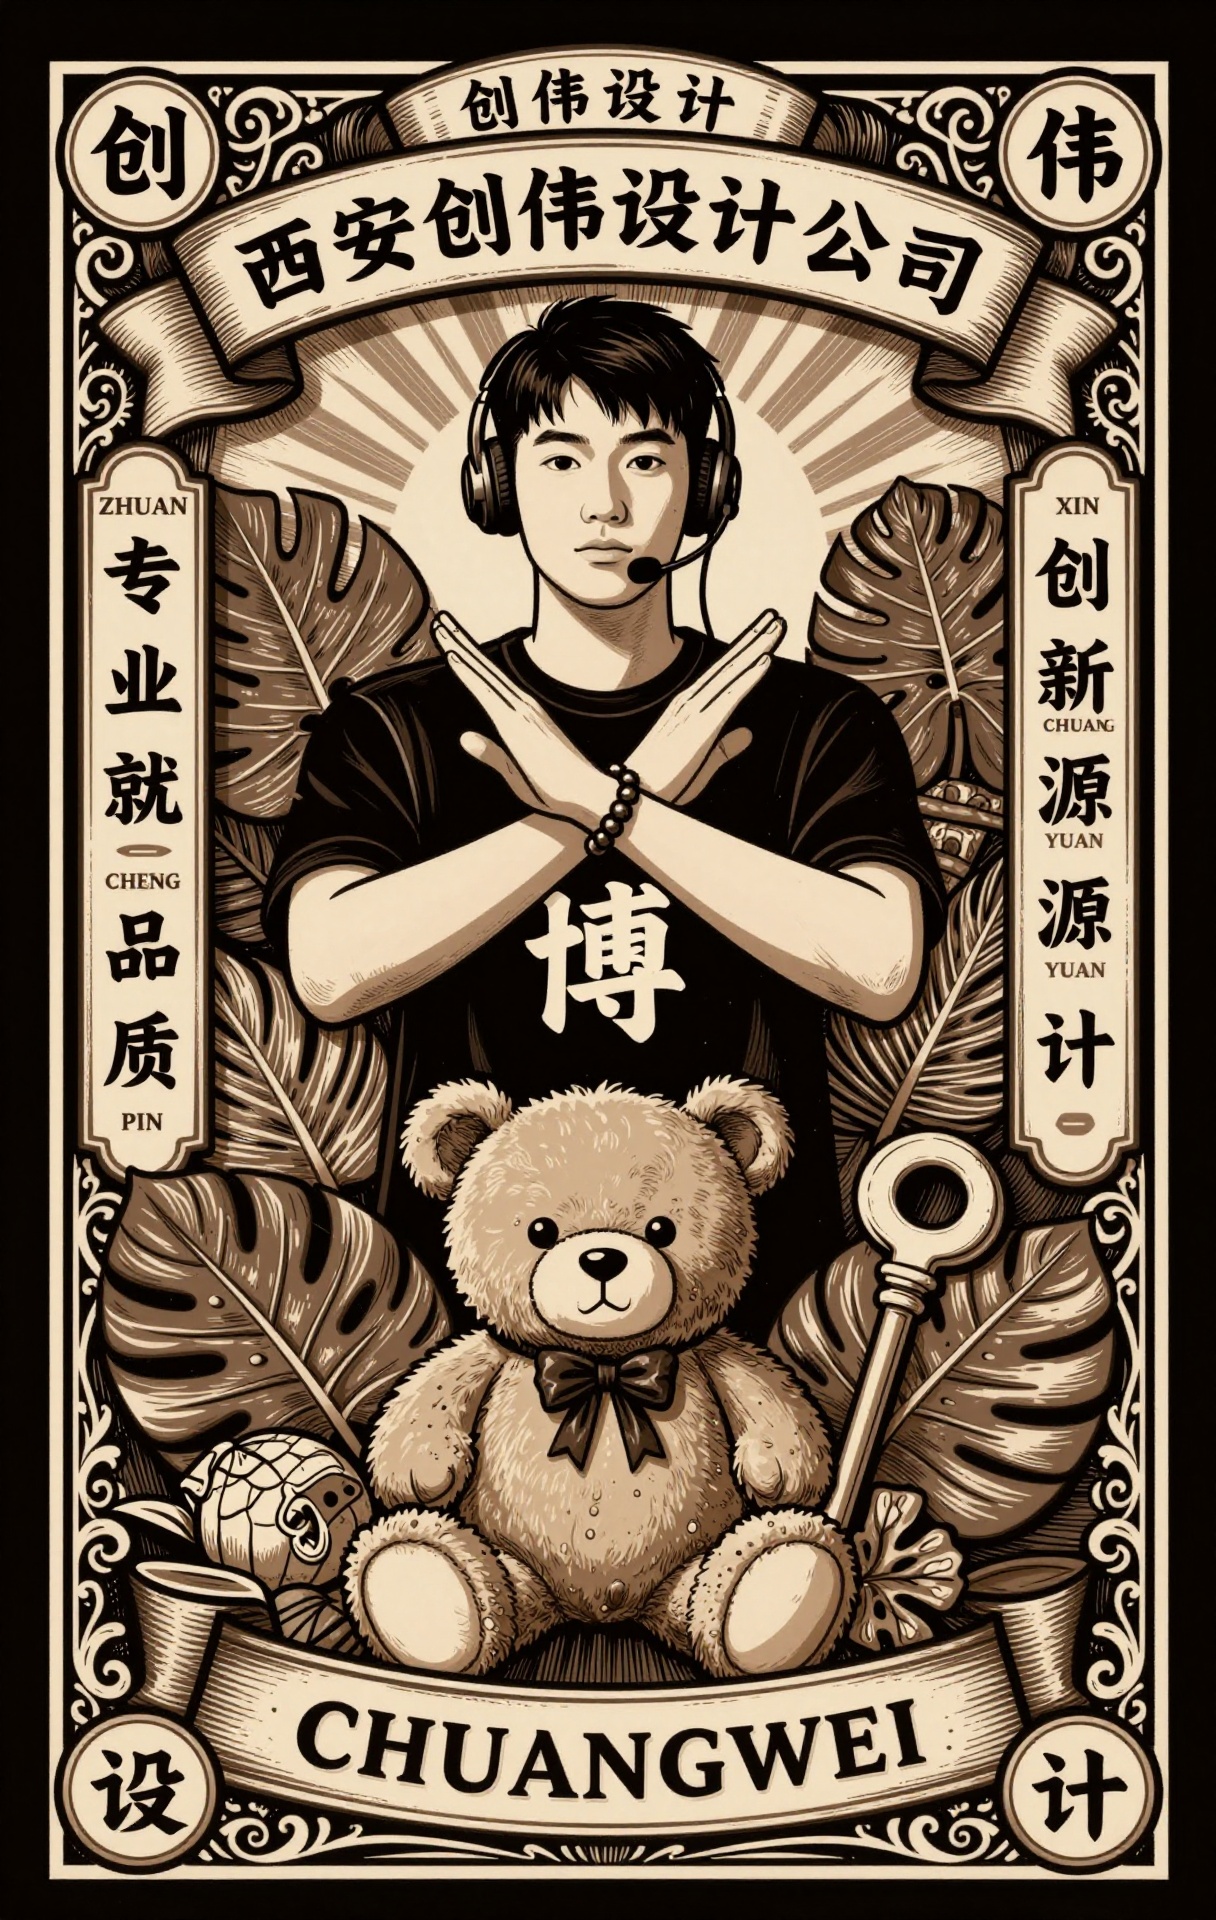
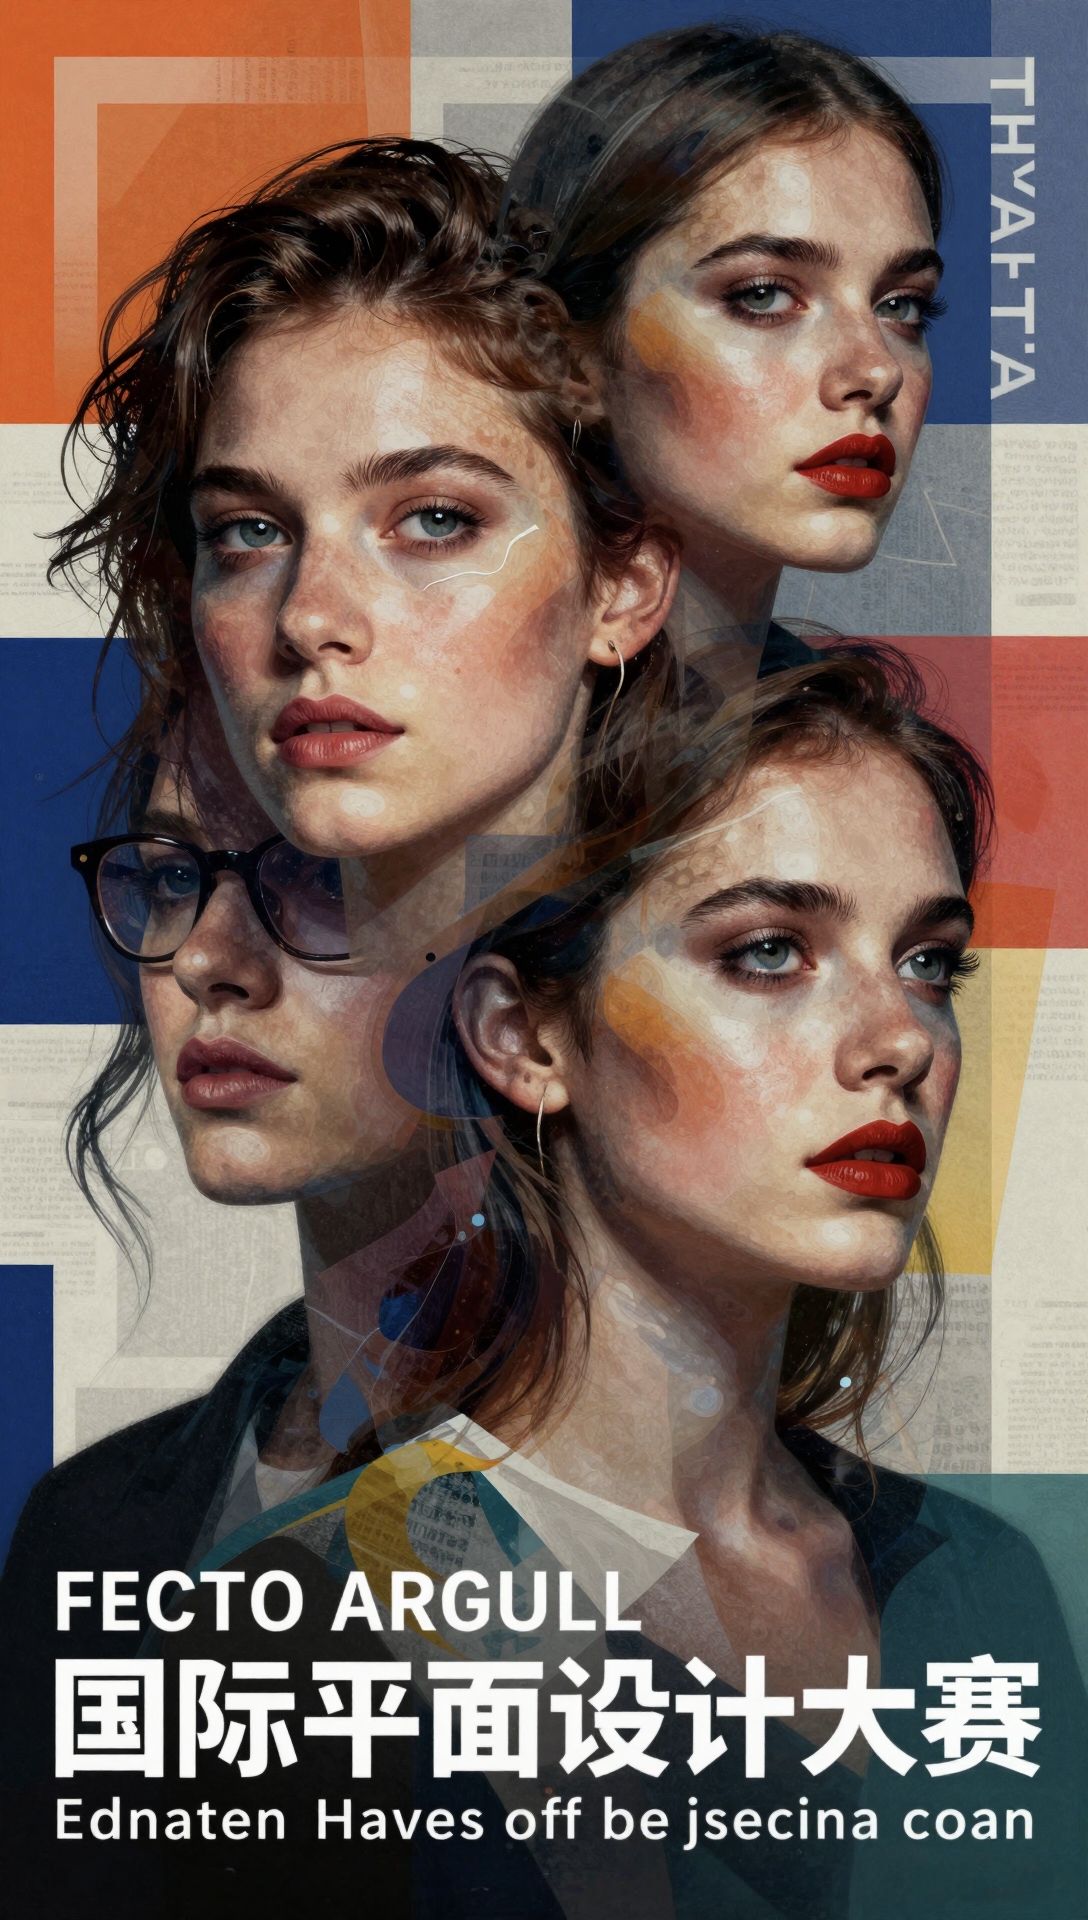
2. Excellent Bilingual Text Rendering 卓越的中英双语文本渲染
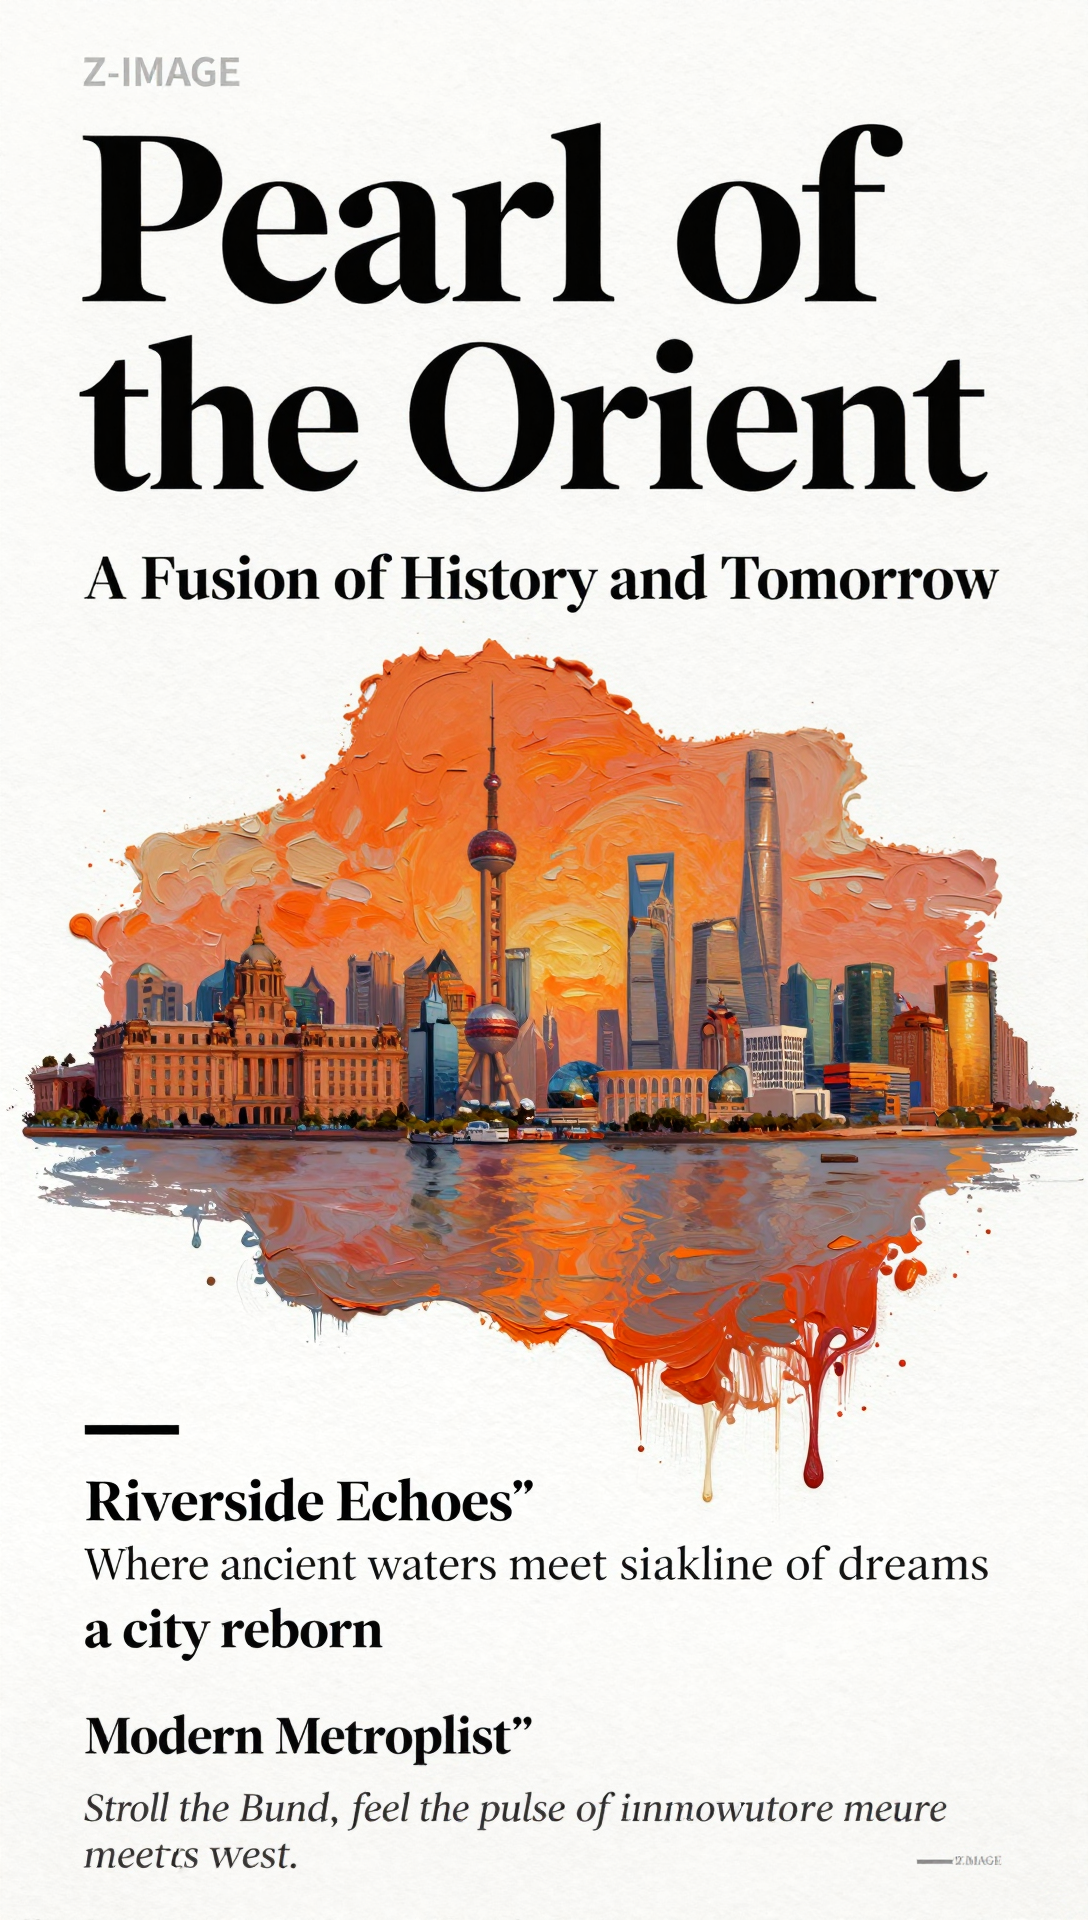
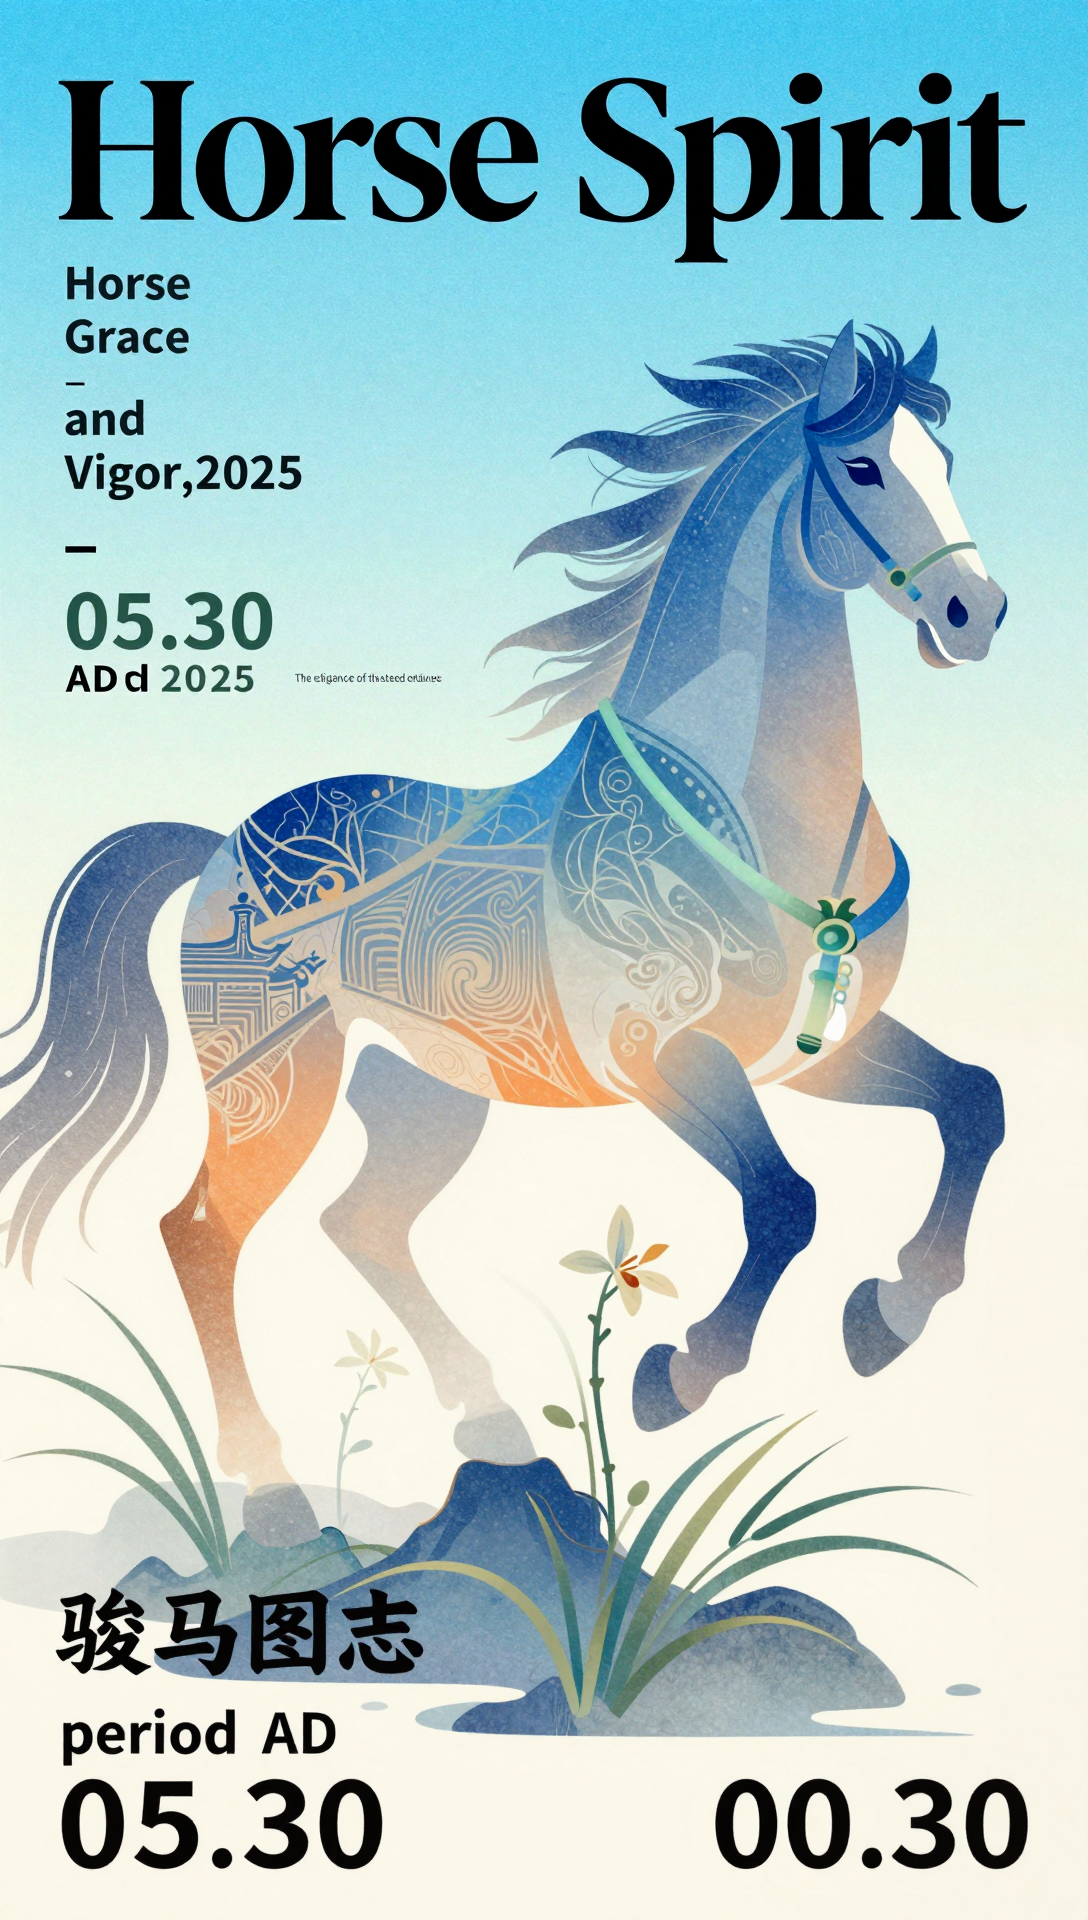
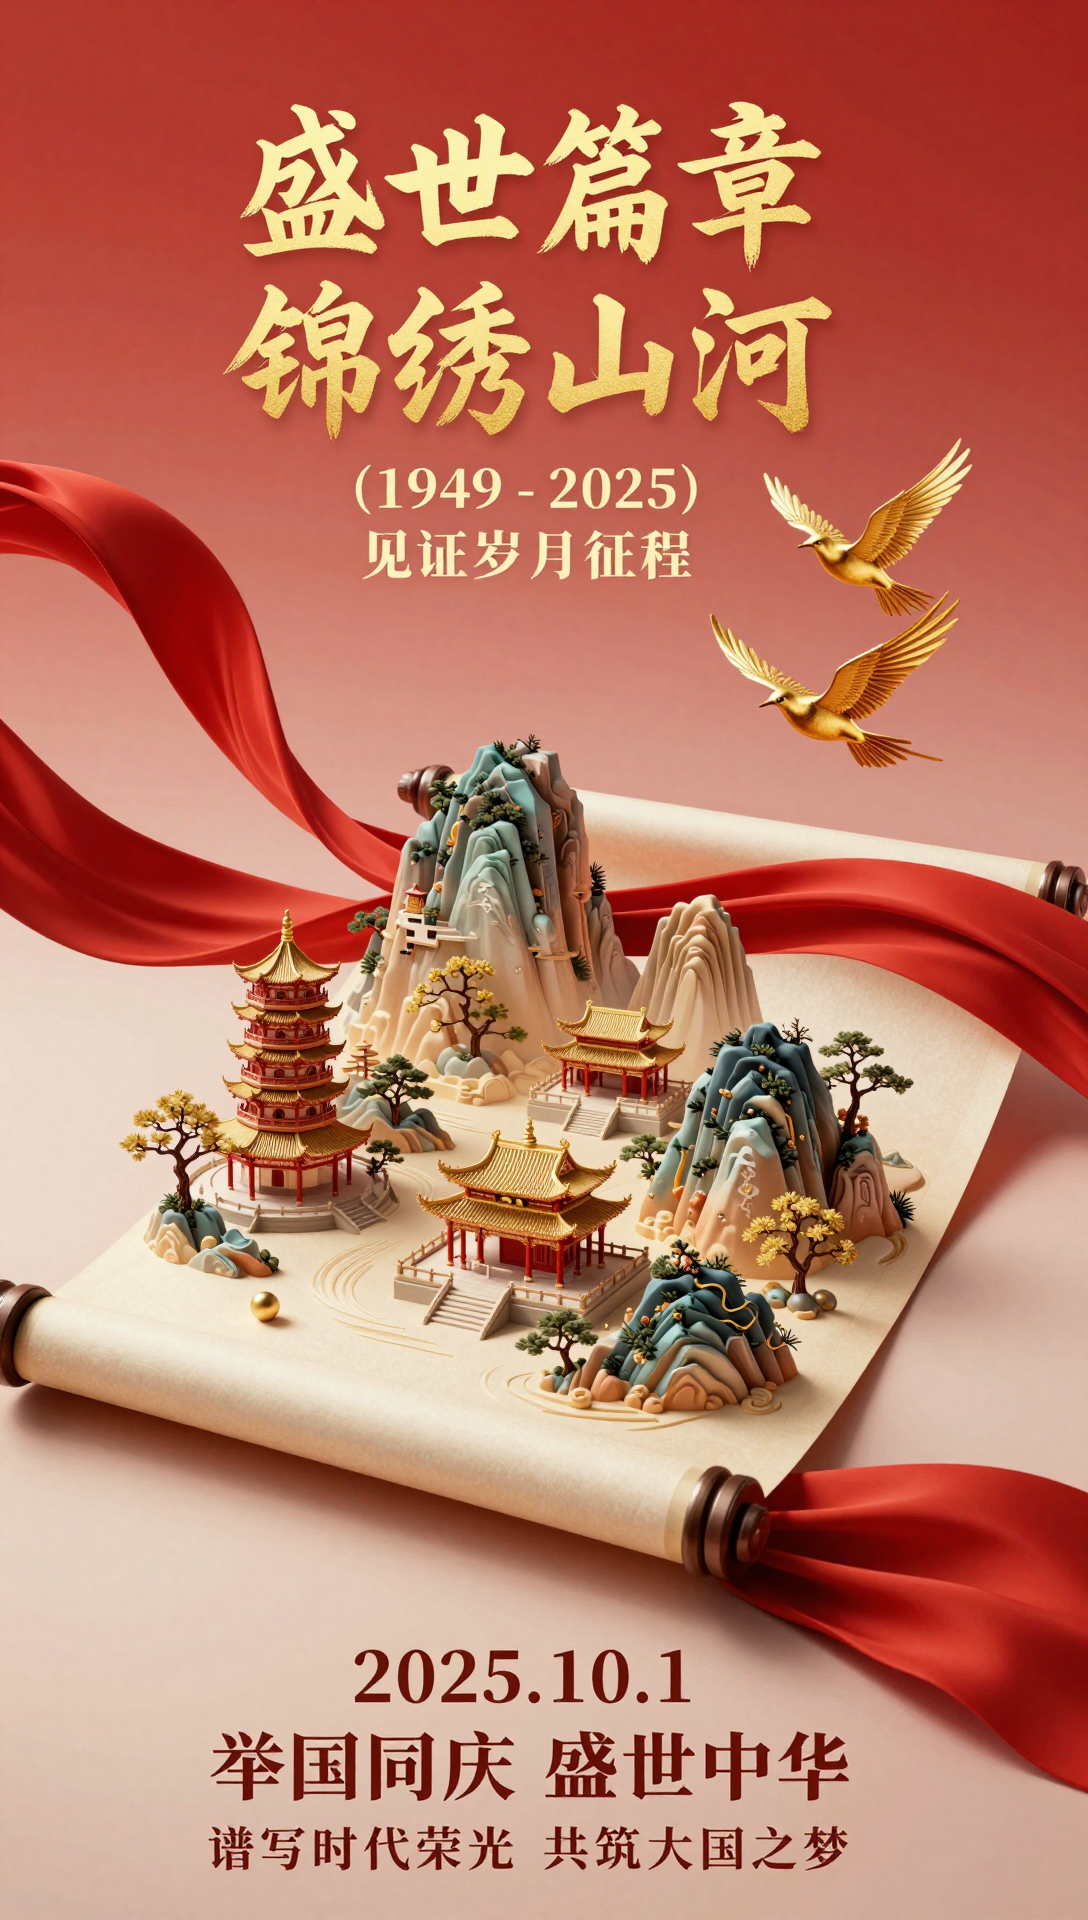
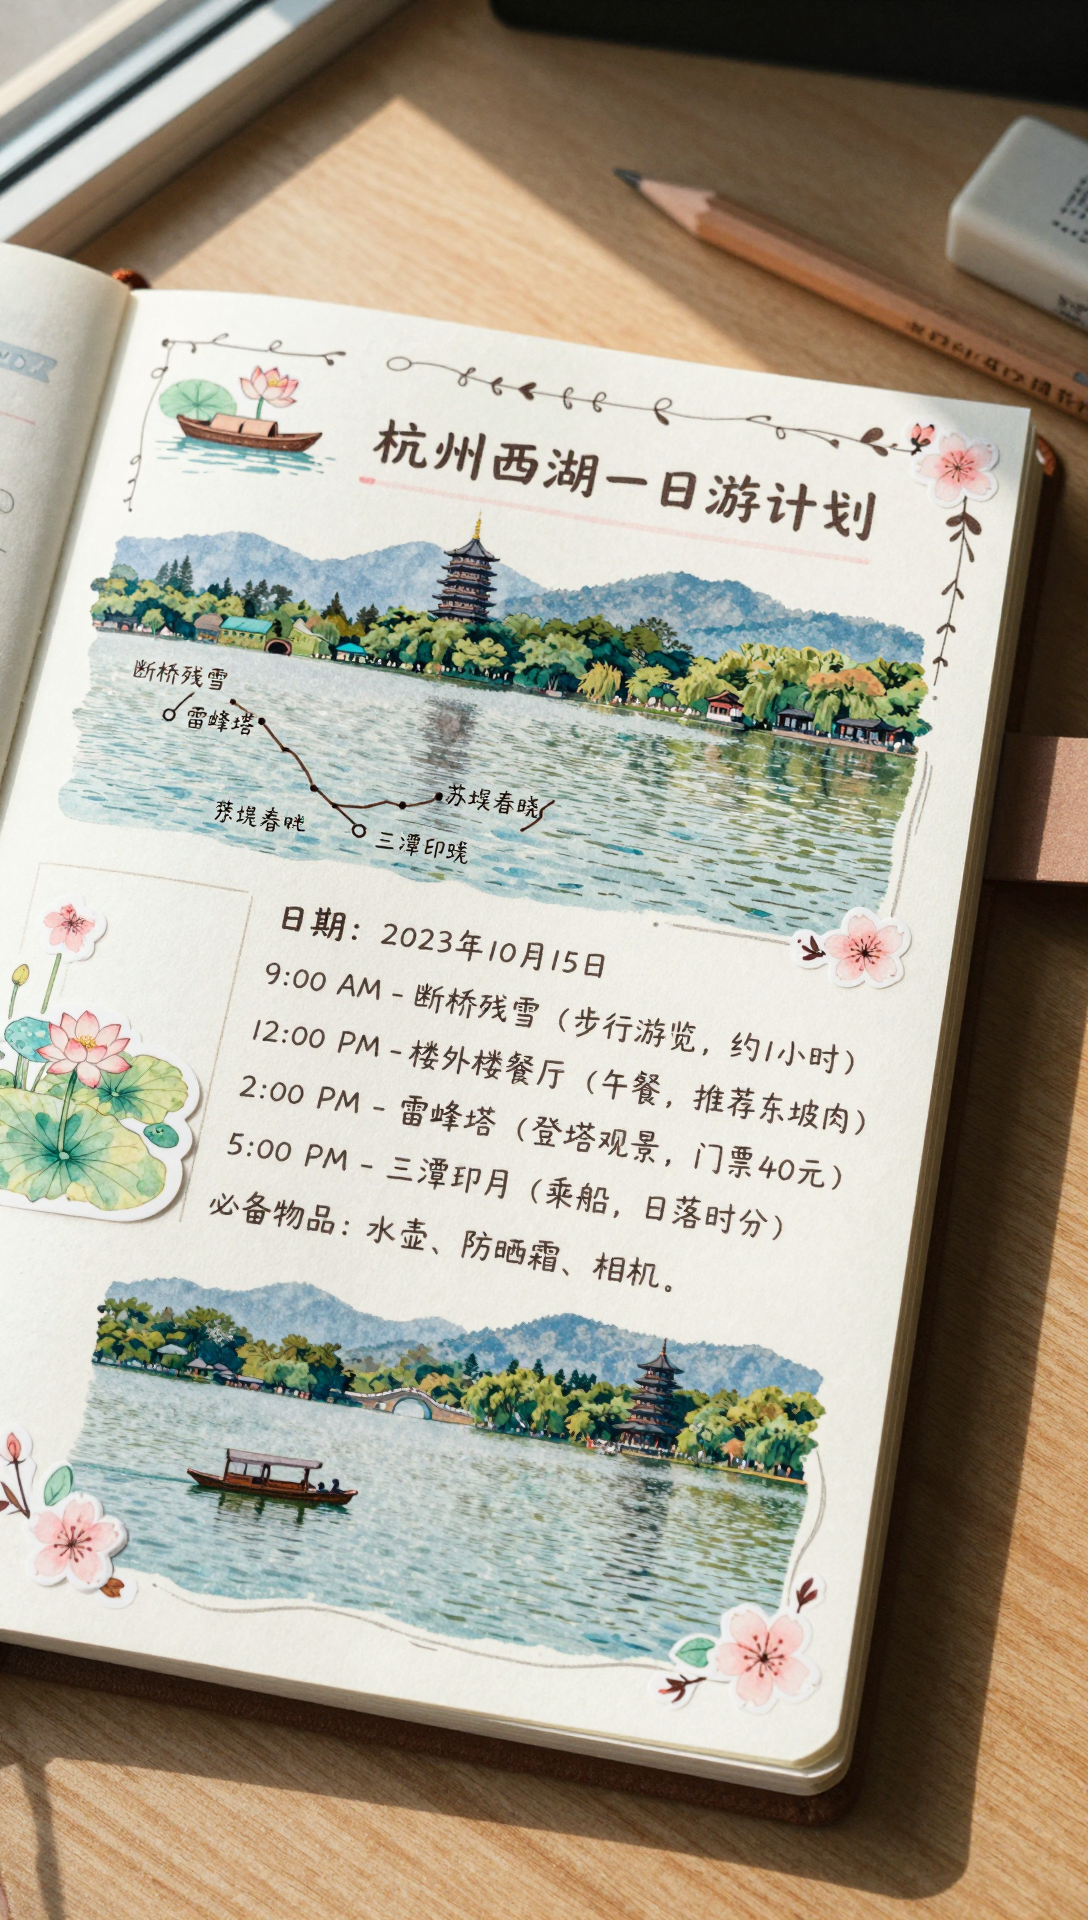
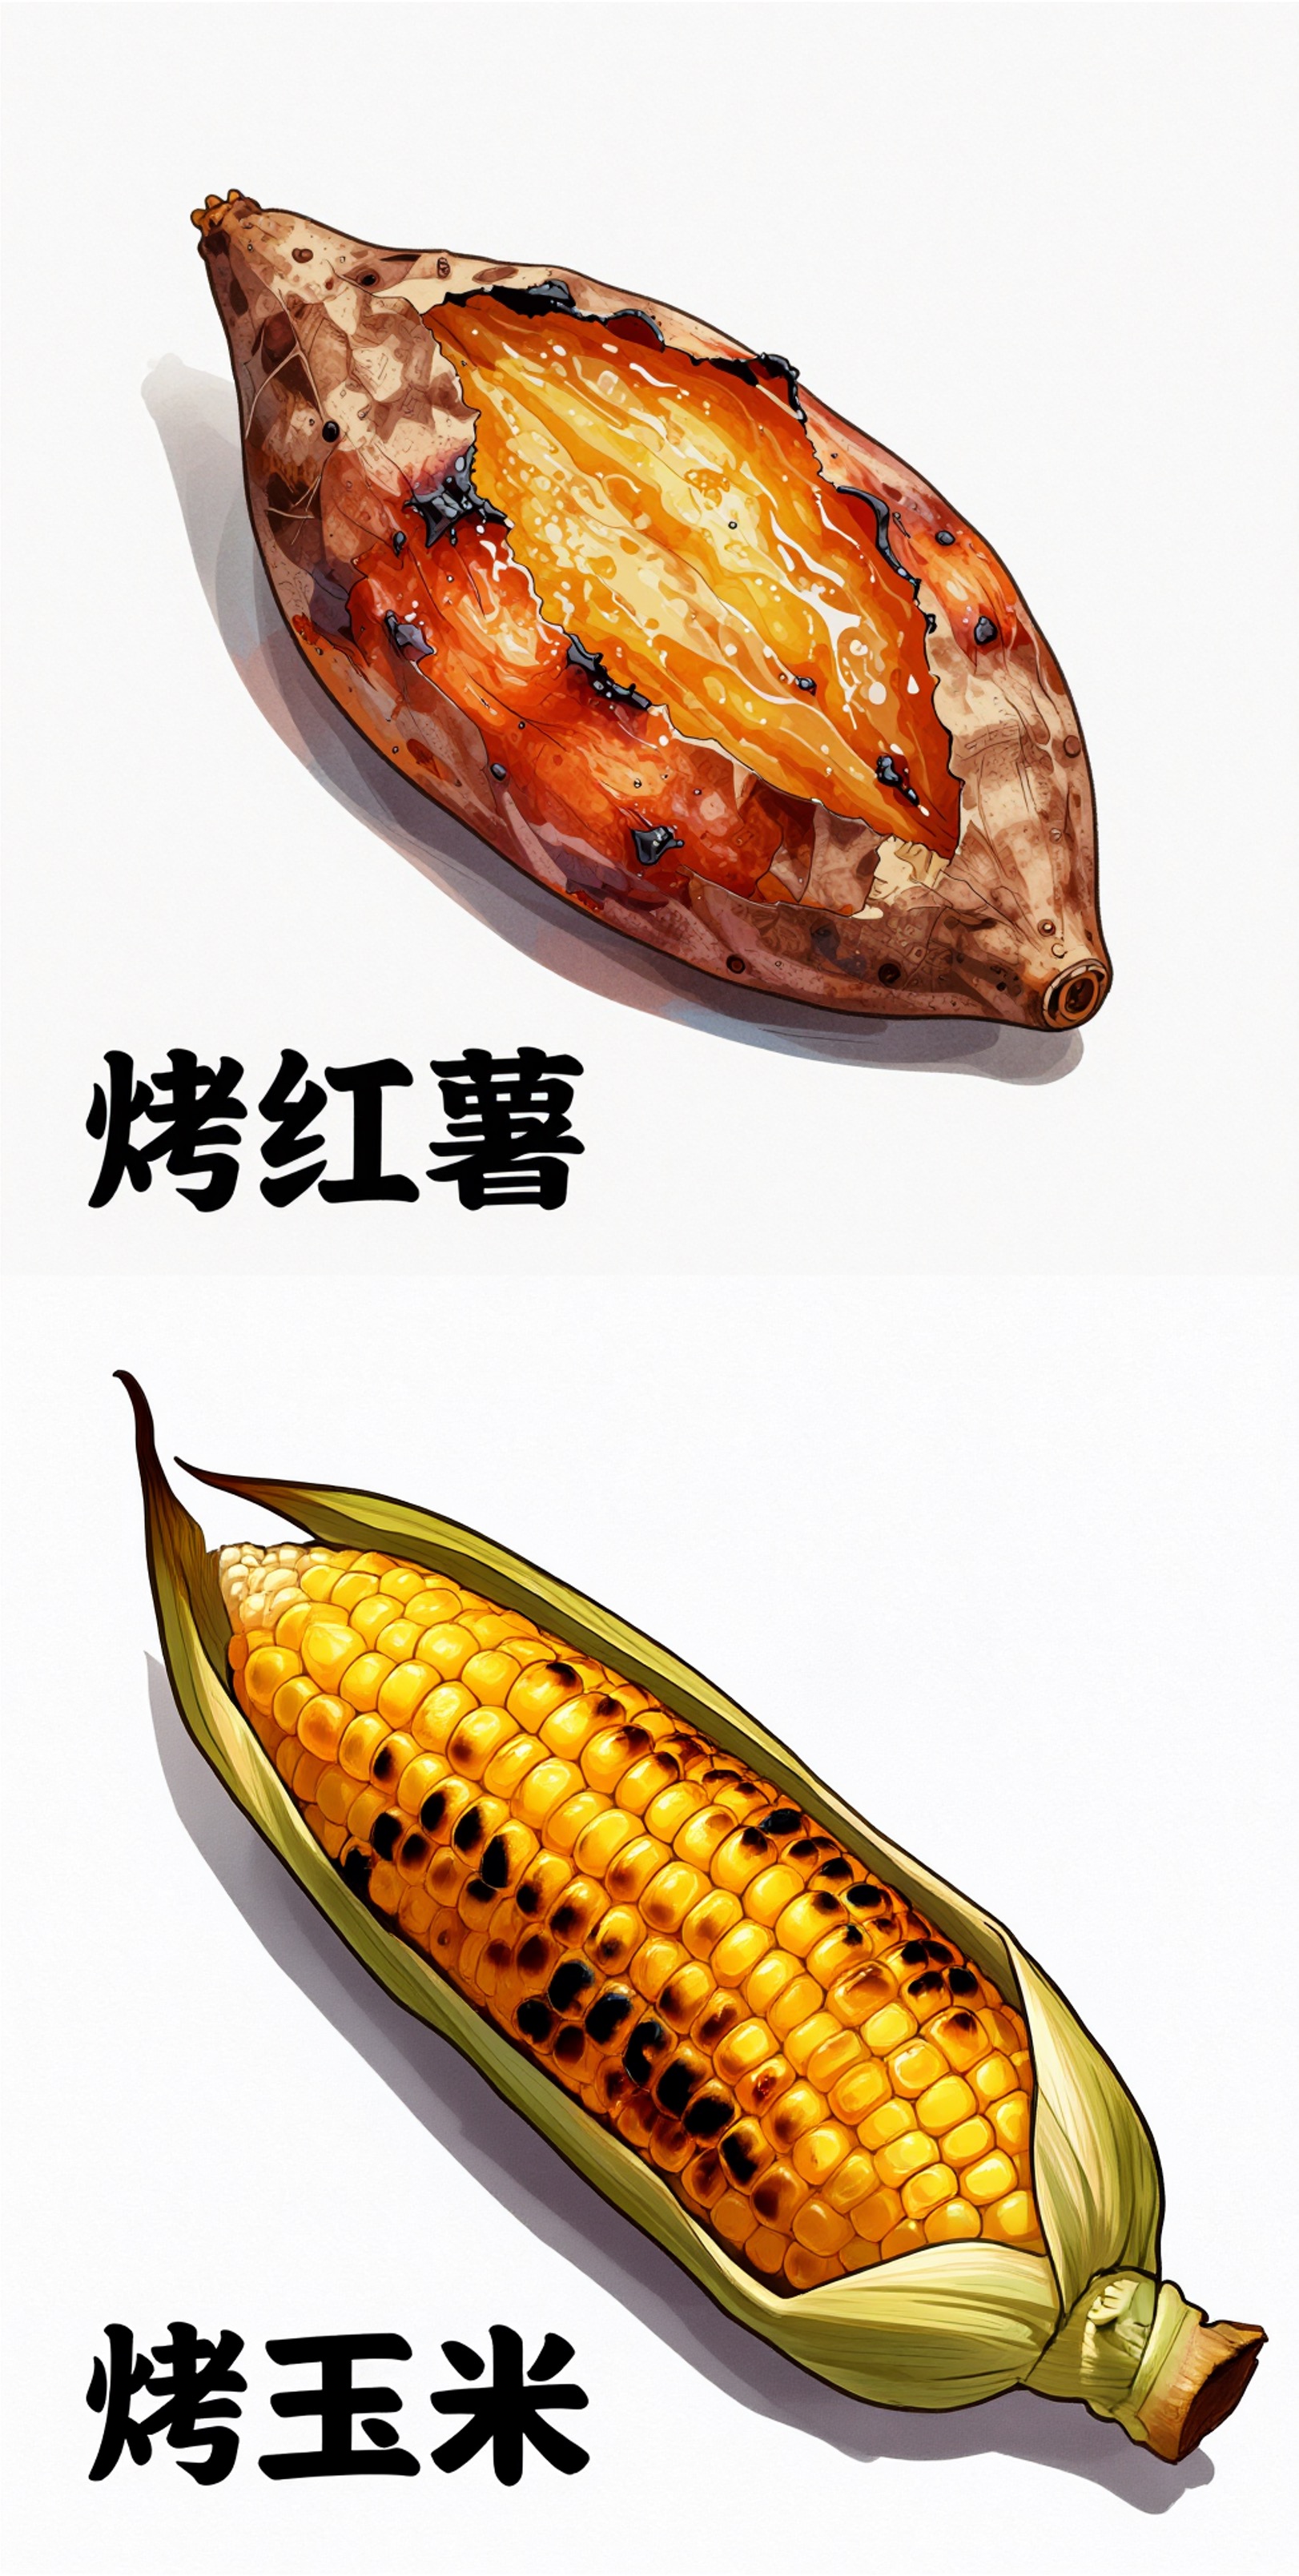
Z-Image-Turbo can accurately render Chinese and English text while preserving facial realism and aesthetic composition, with results comparable to top-tier closed-source models. Even in challenging scenarios with small font sizes, it delivers designs that are both textually precise and visually compelling.
3. Rich World Knowledge 广博的知识与文化理解
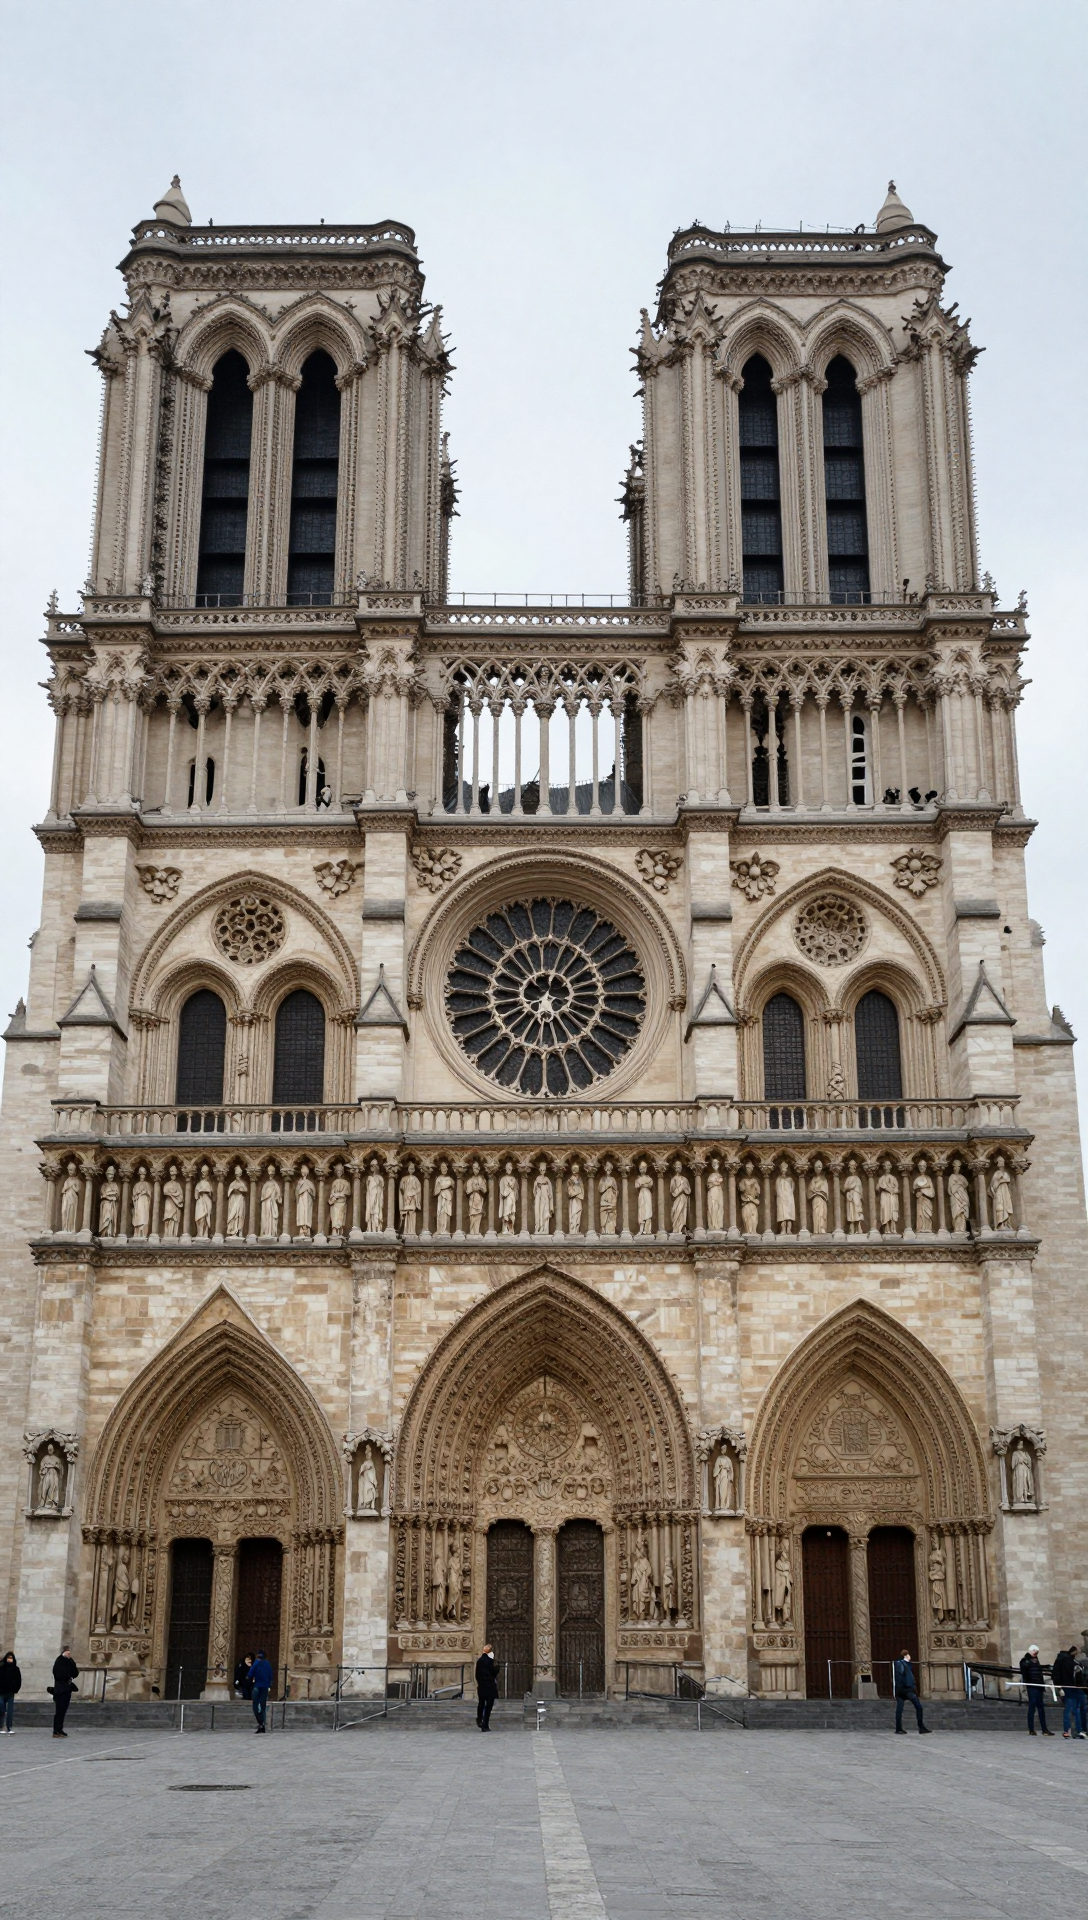
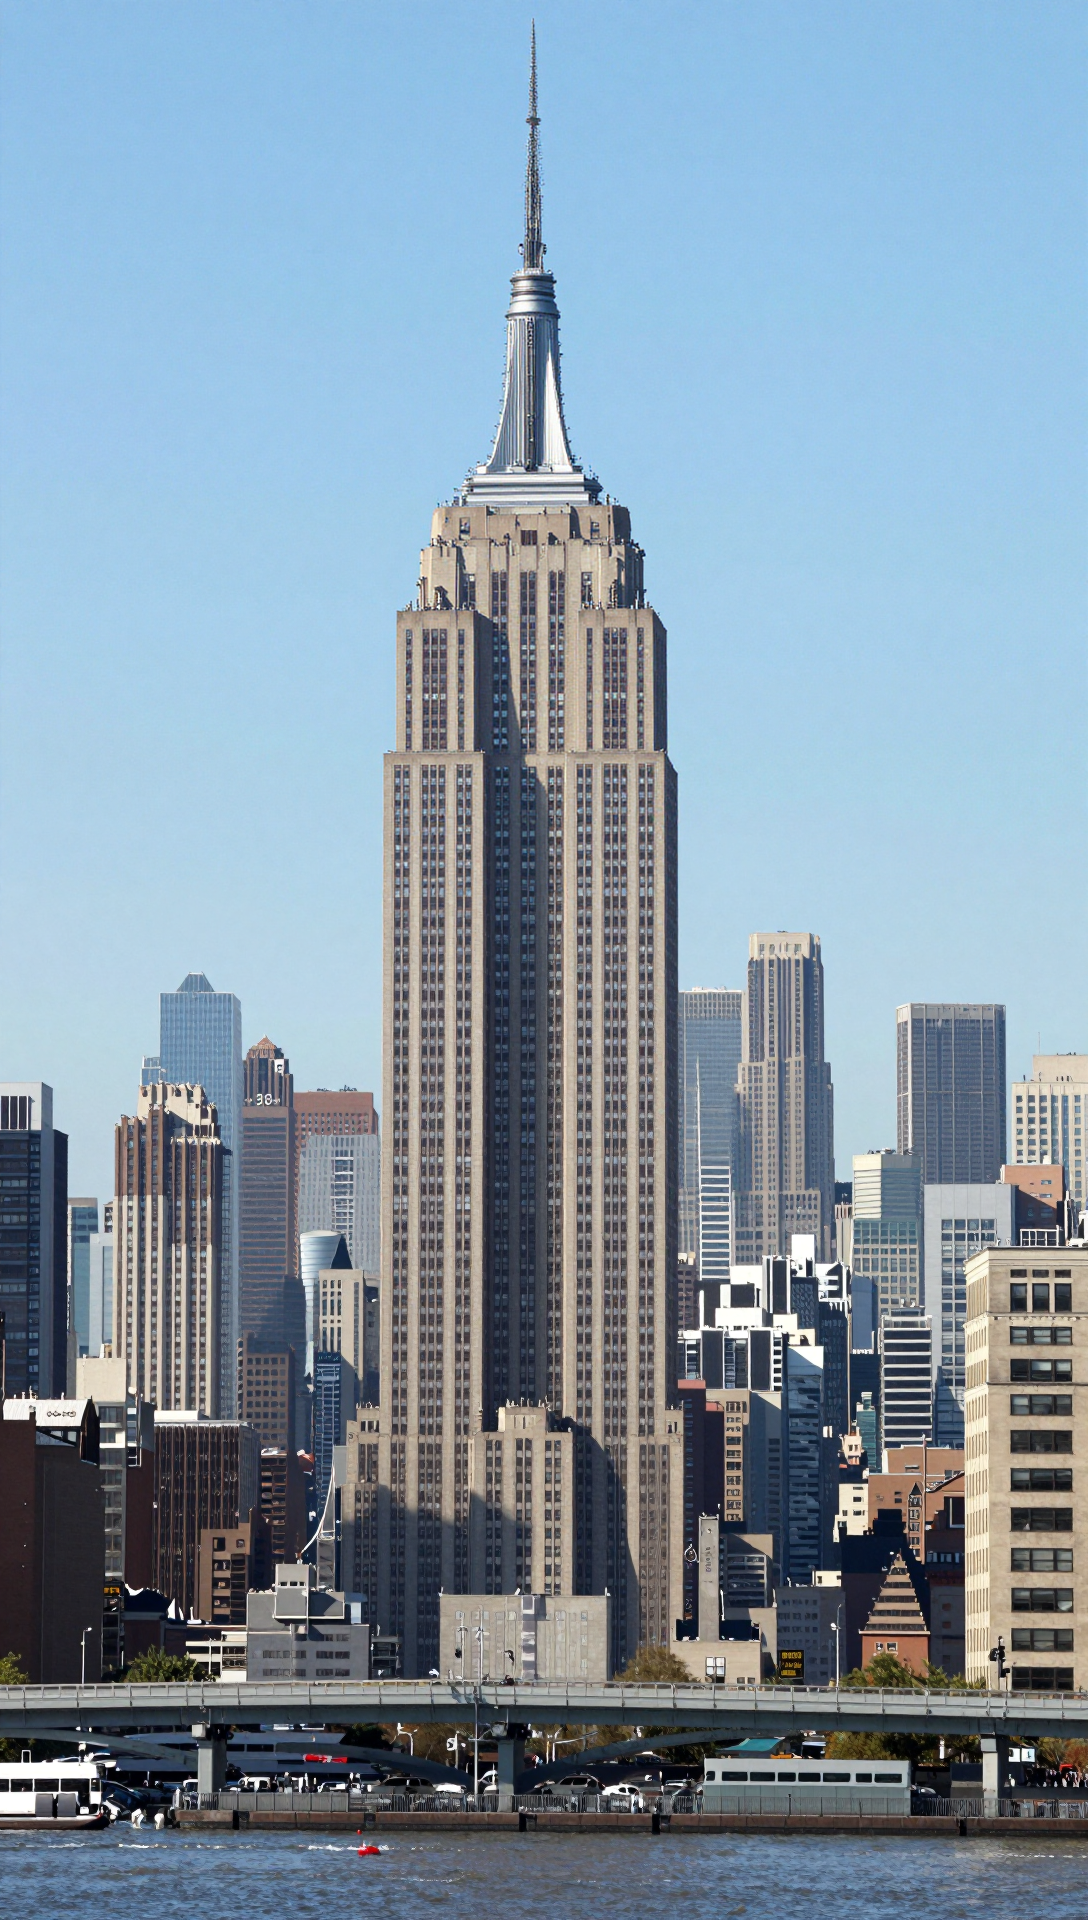
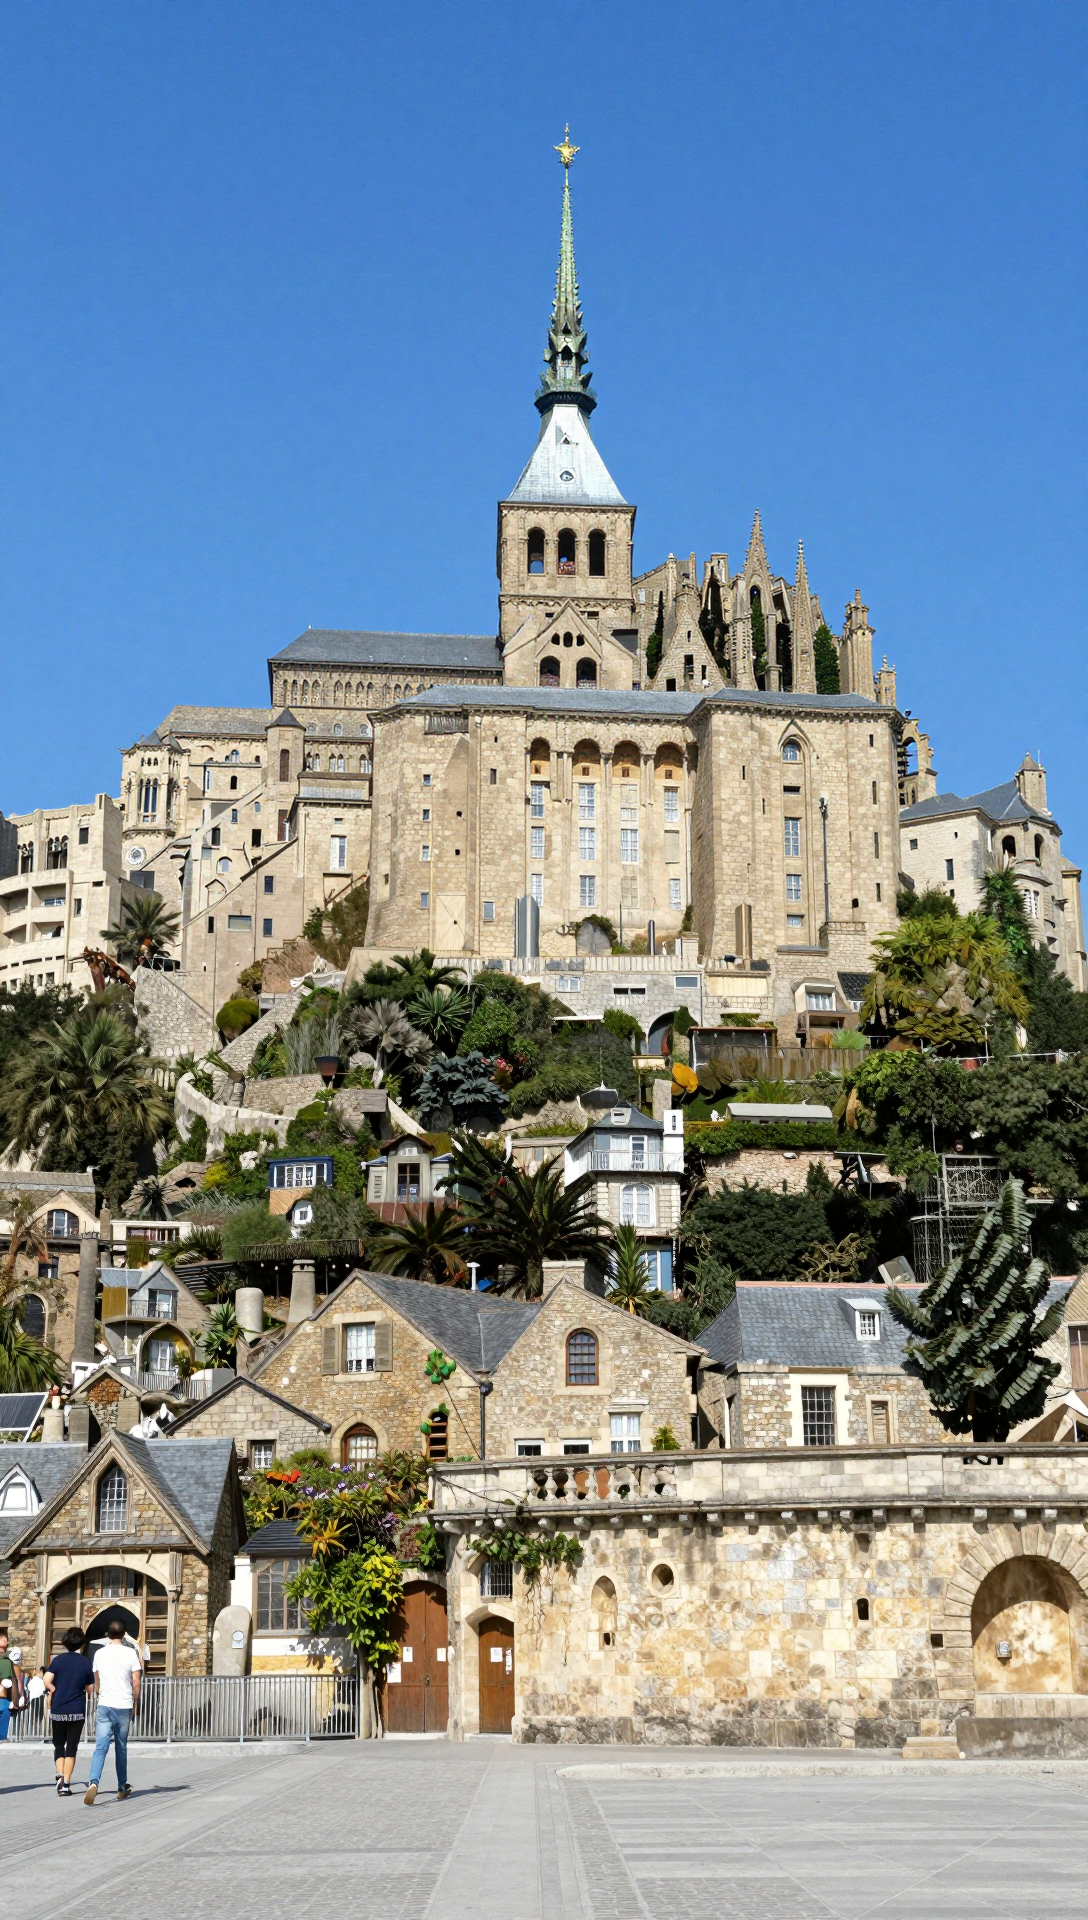
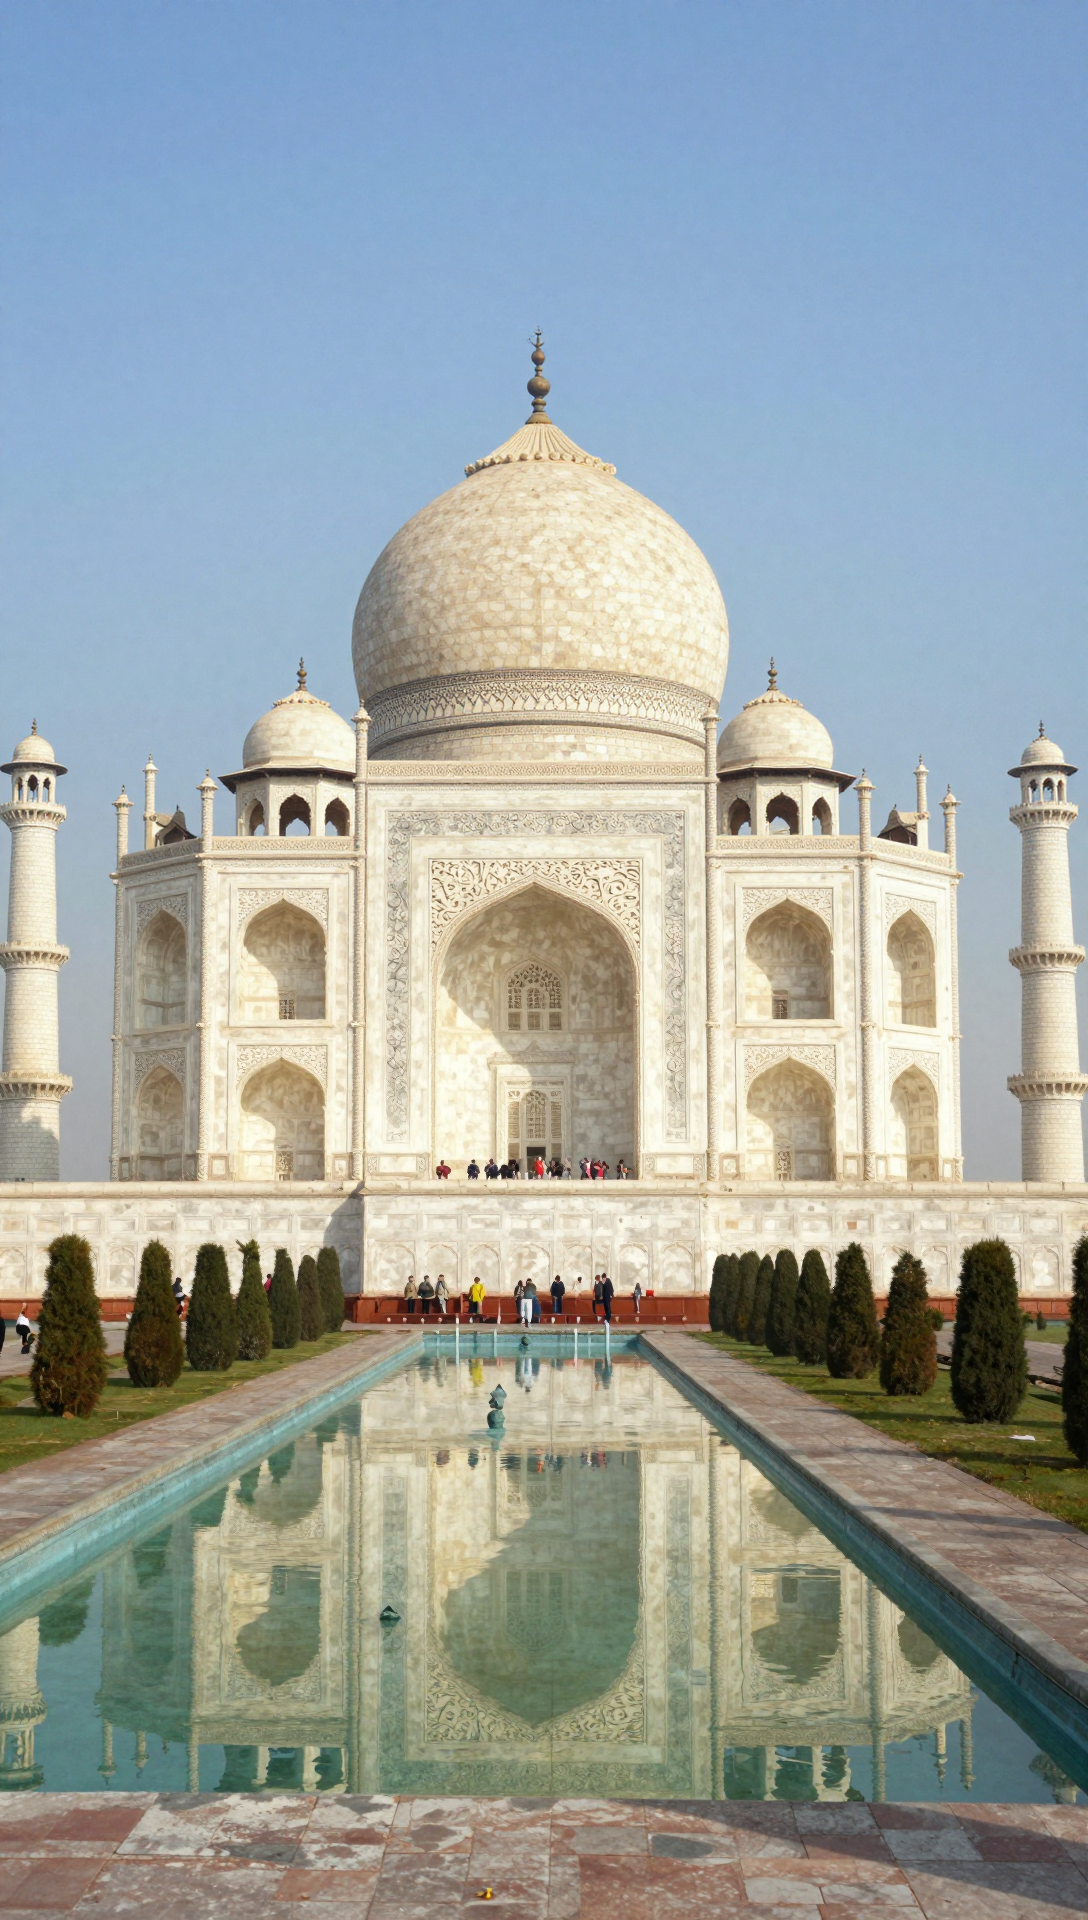
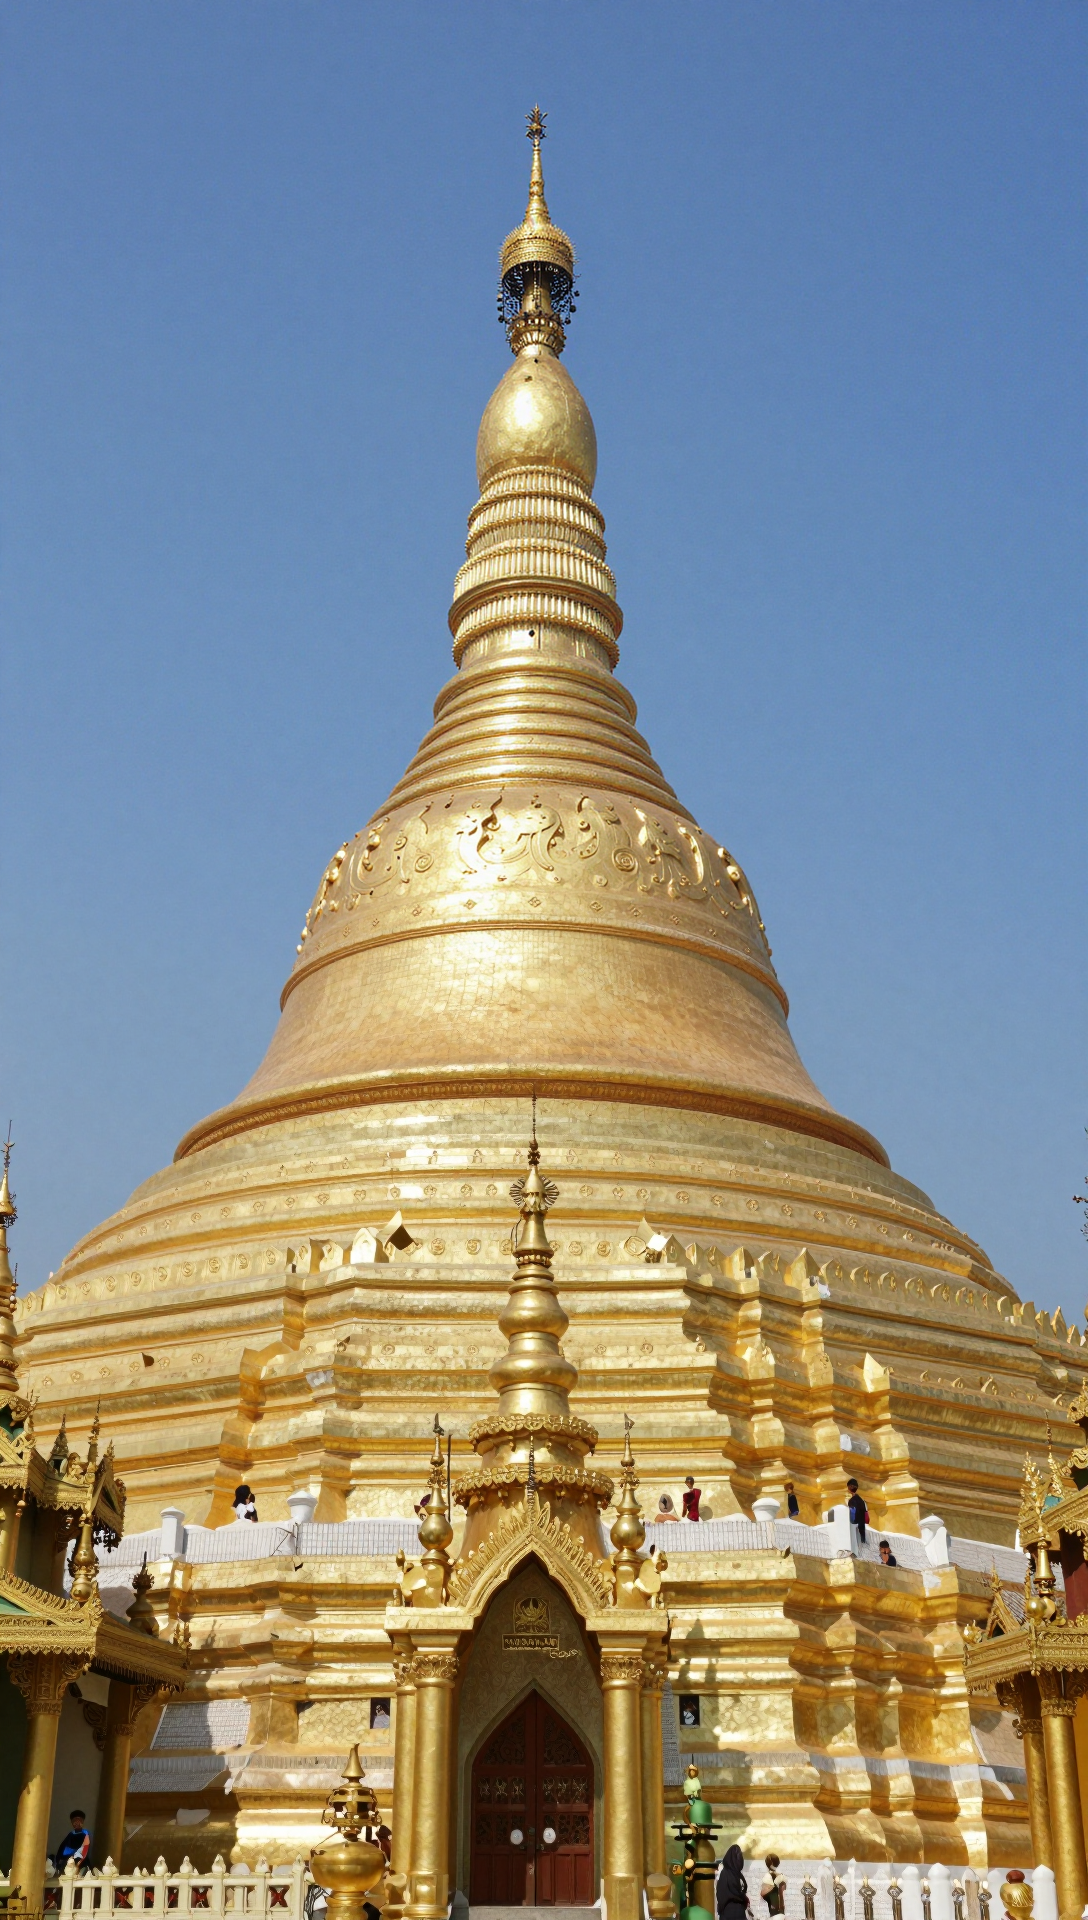
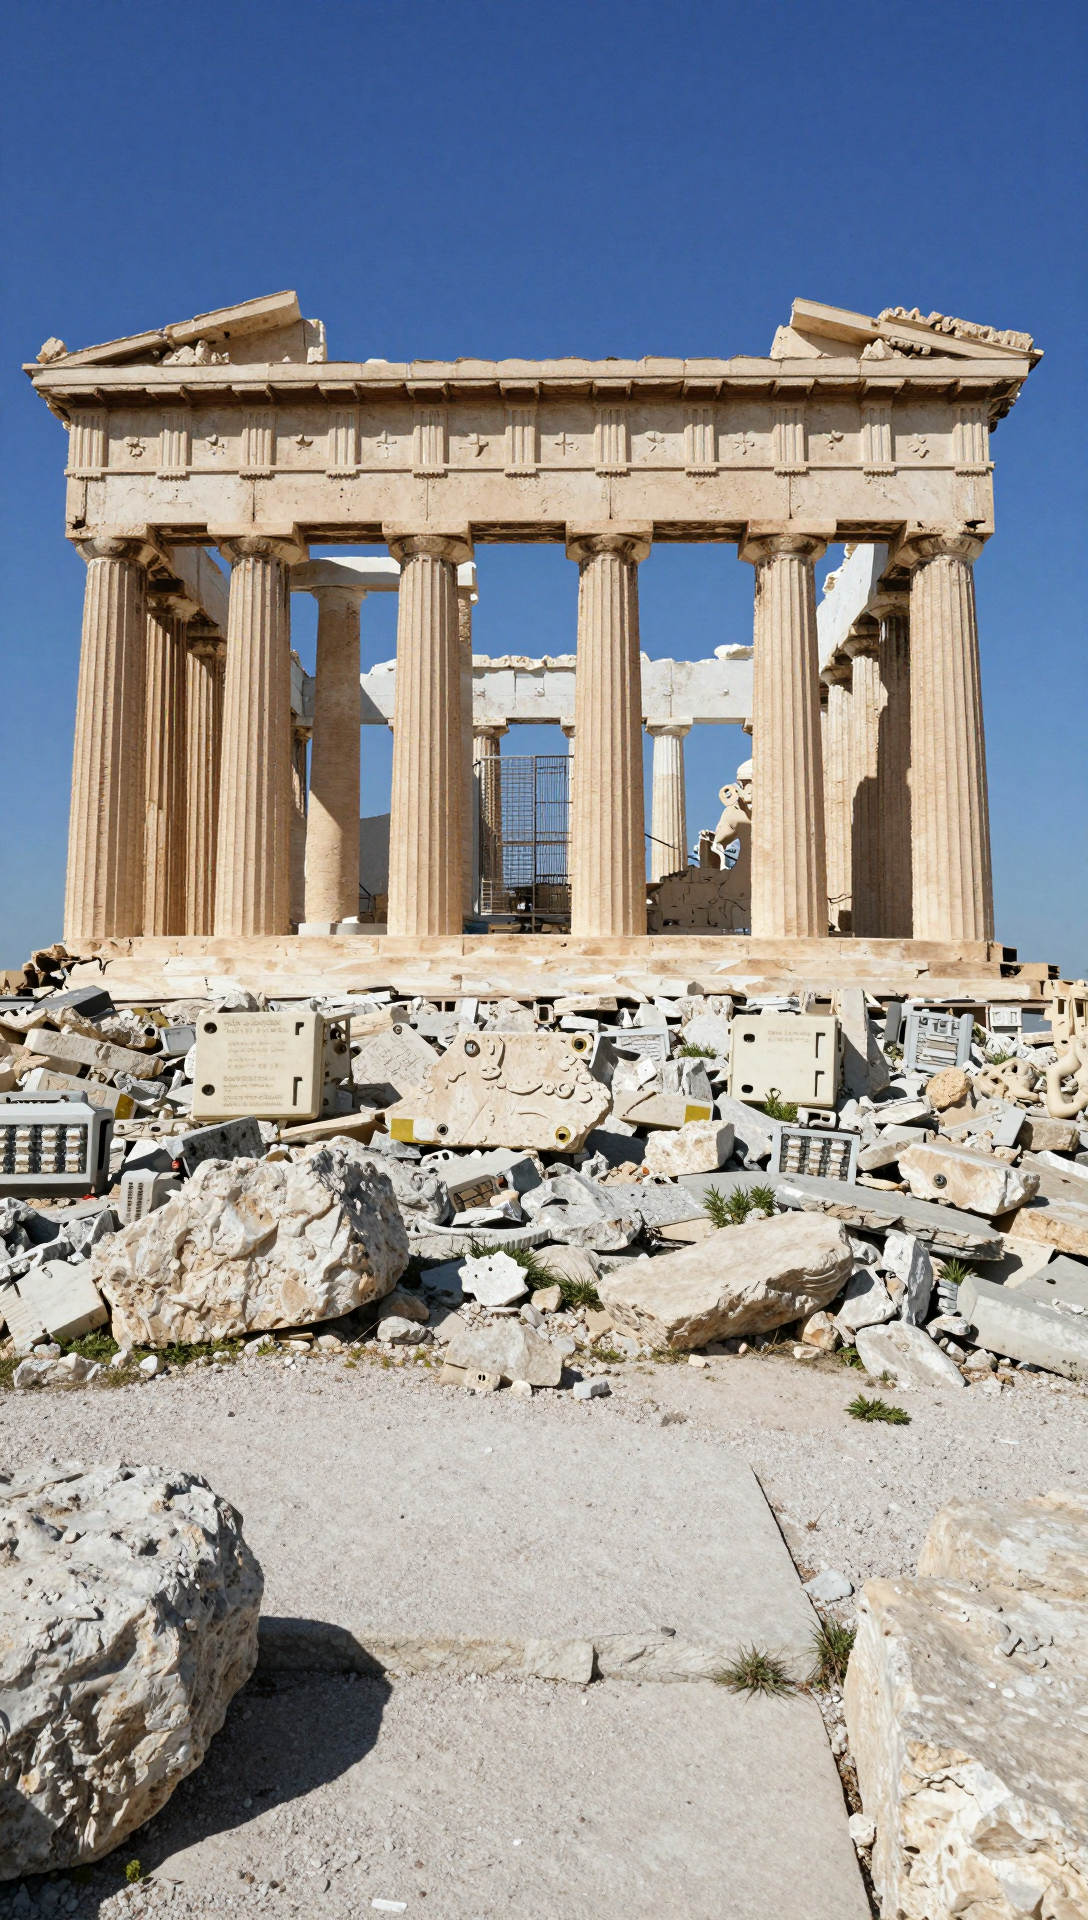
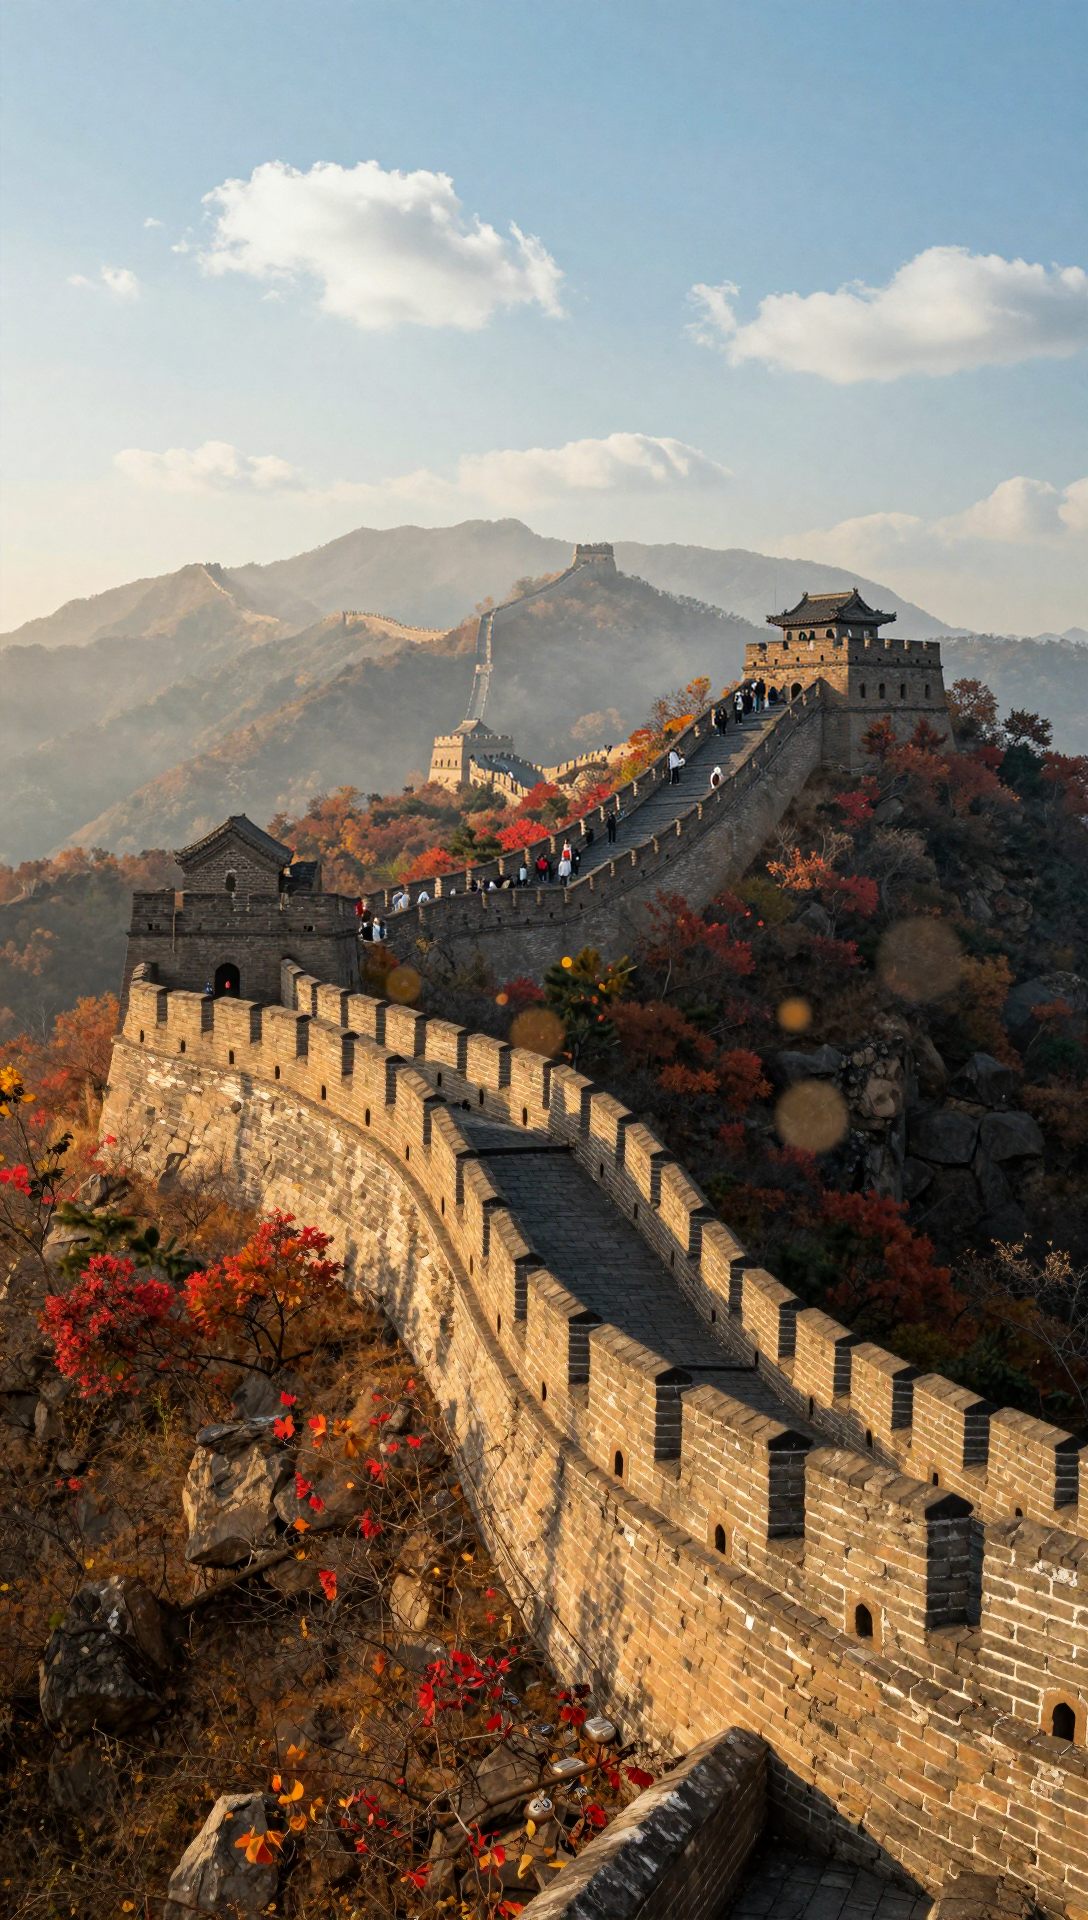
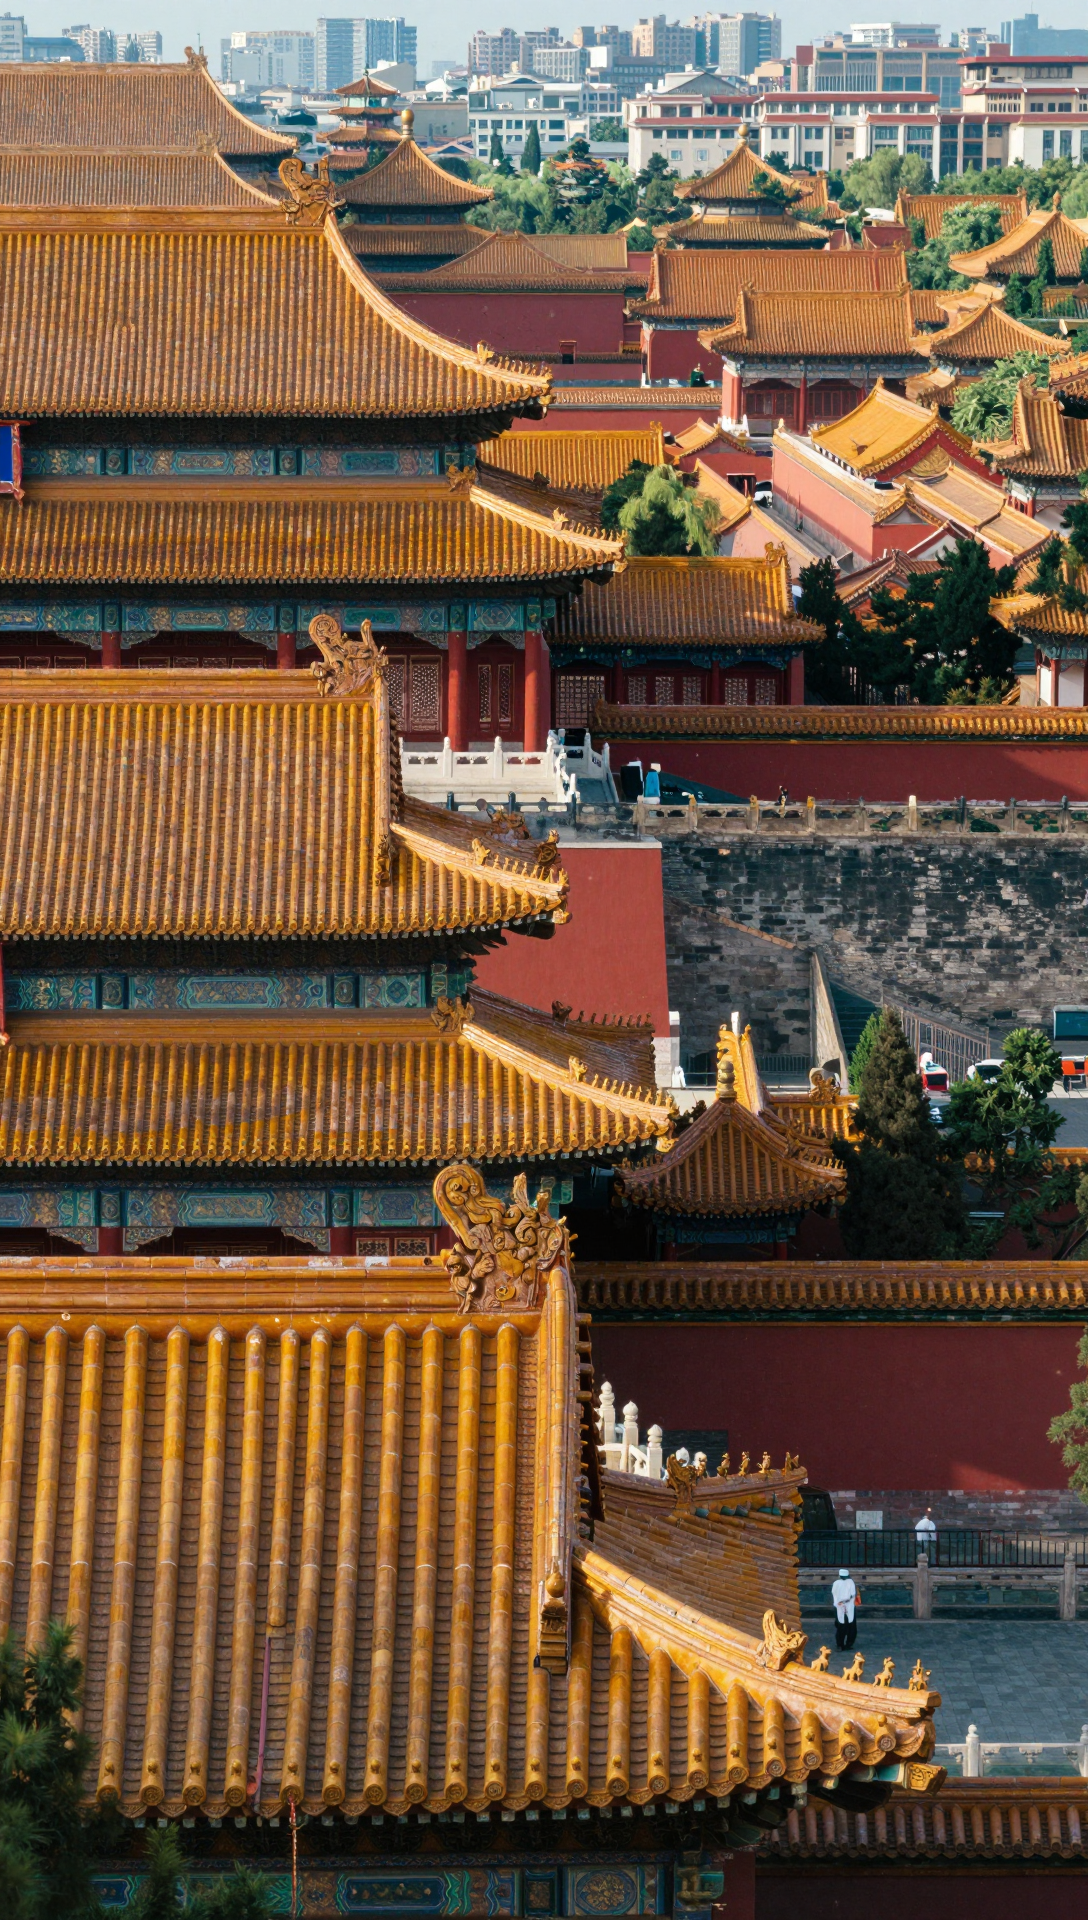
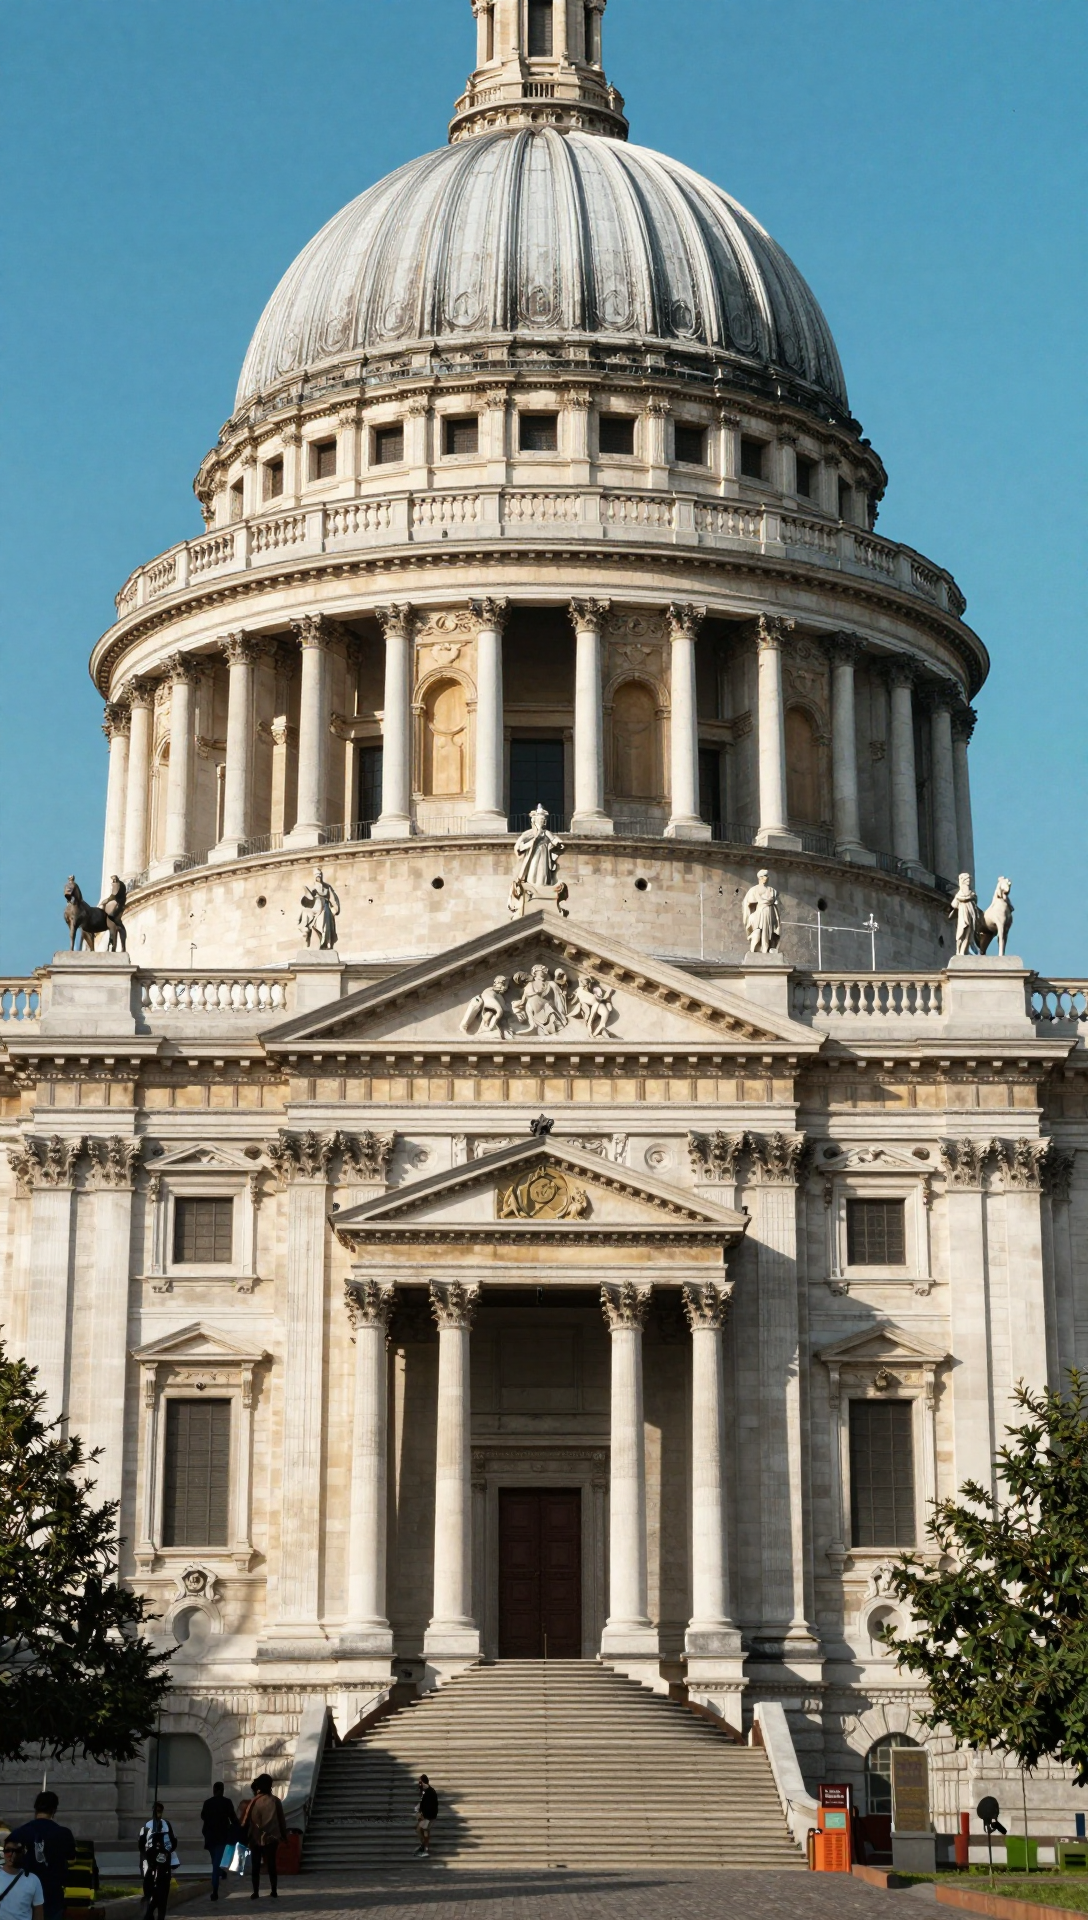
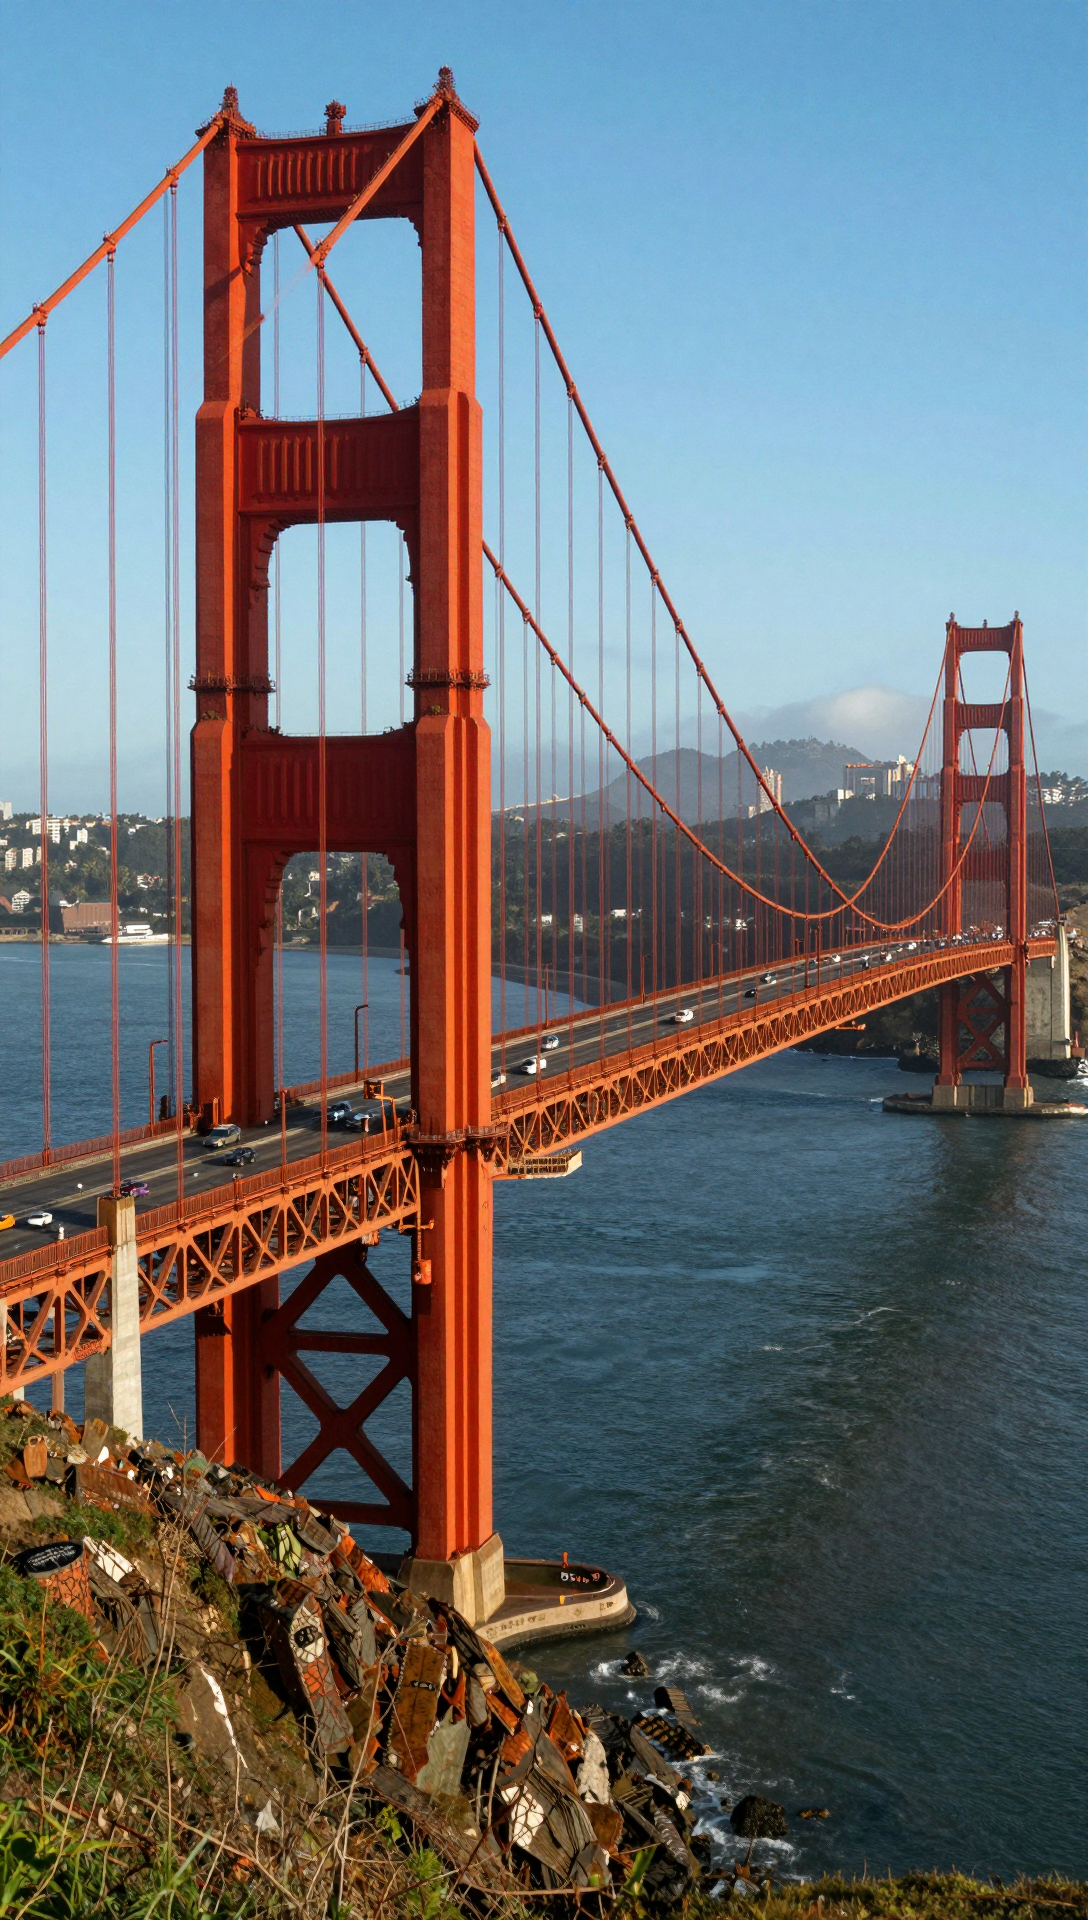
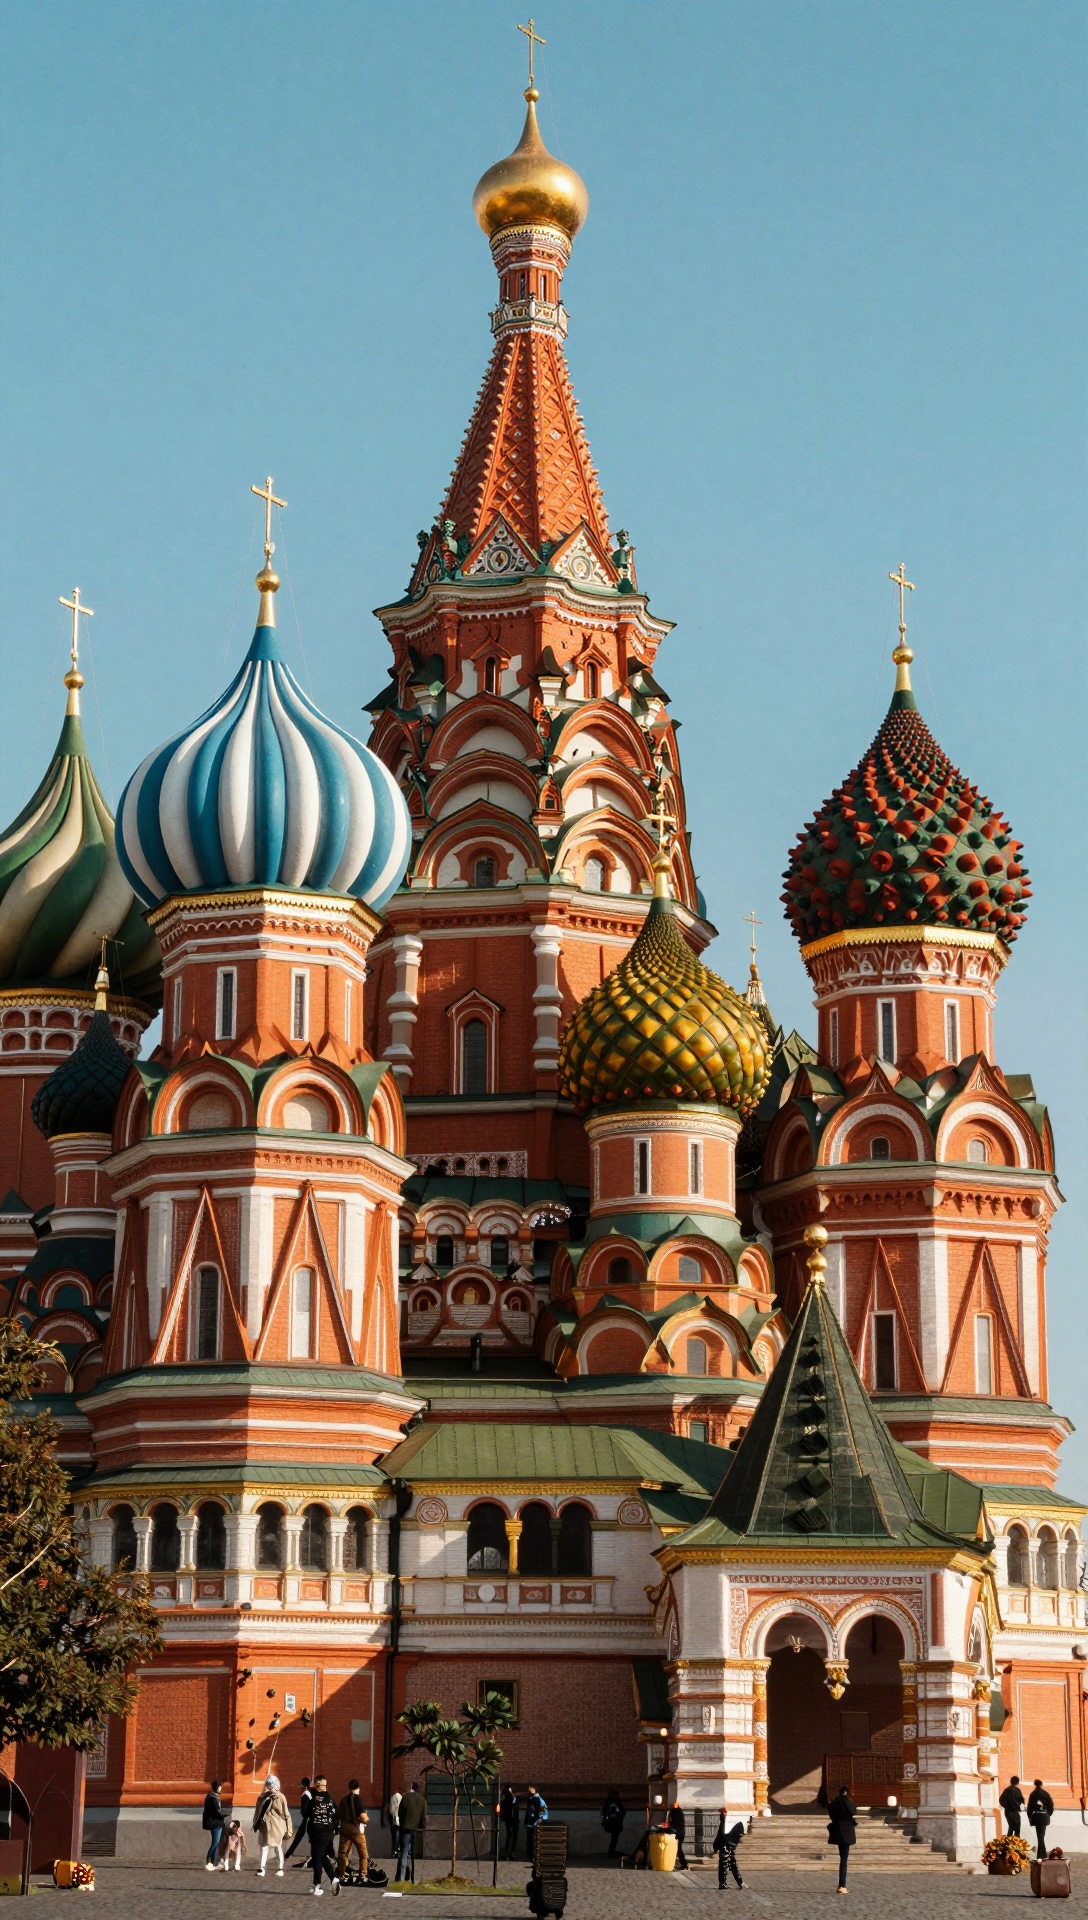
Z-Image possesses a vast understanding of world knowledge and diverse cultural concepts. This allows it to accurately generate famous landmarks, well-known characters, and specific real-world objects.
4. Deep Semantic Understanding 引入先验知识的深度语义理解
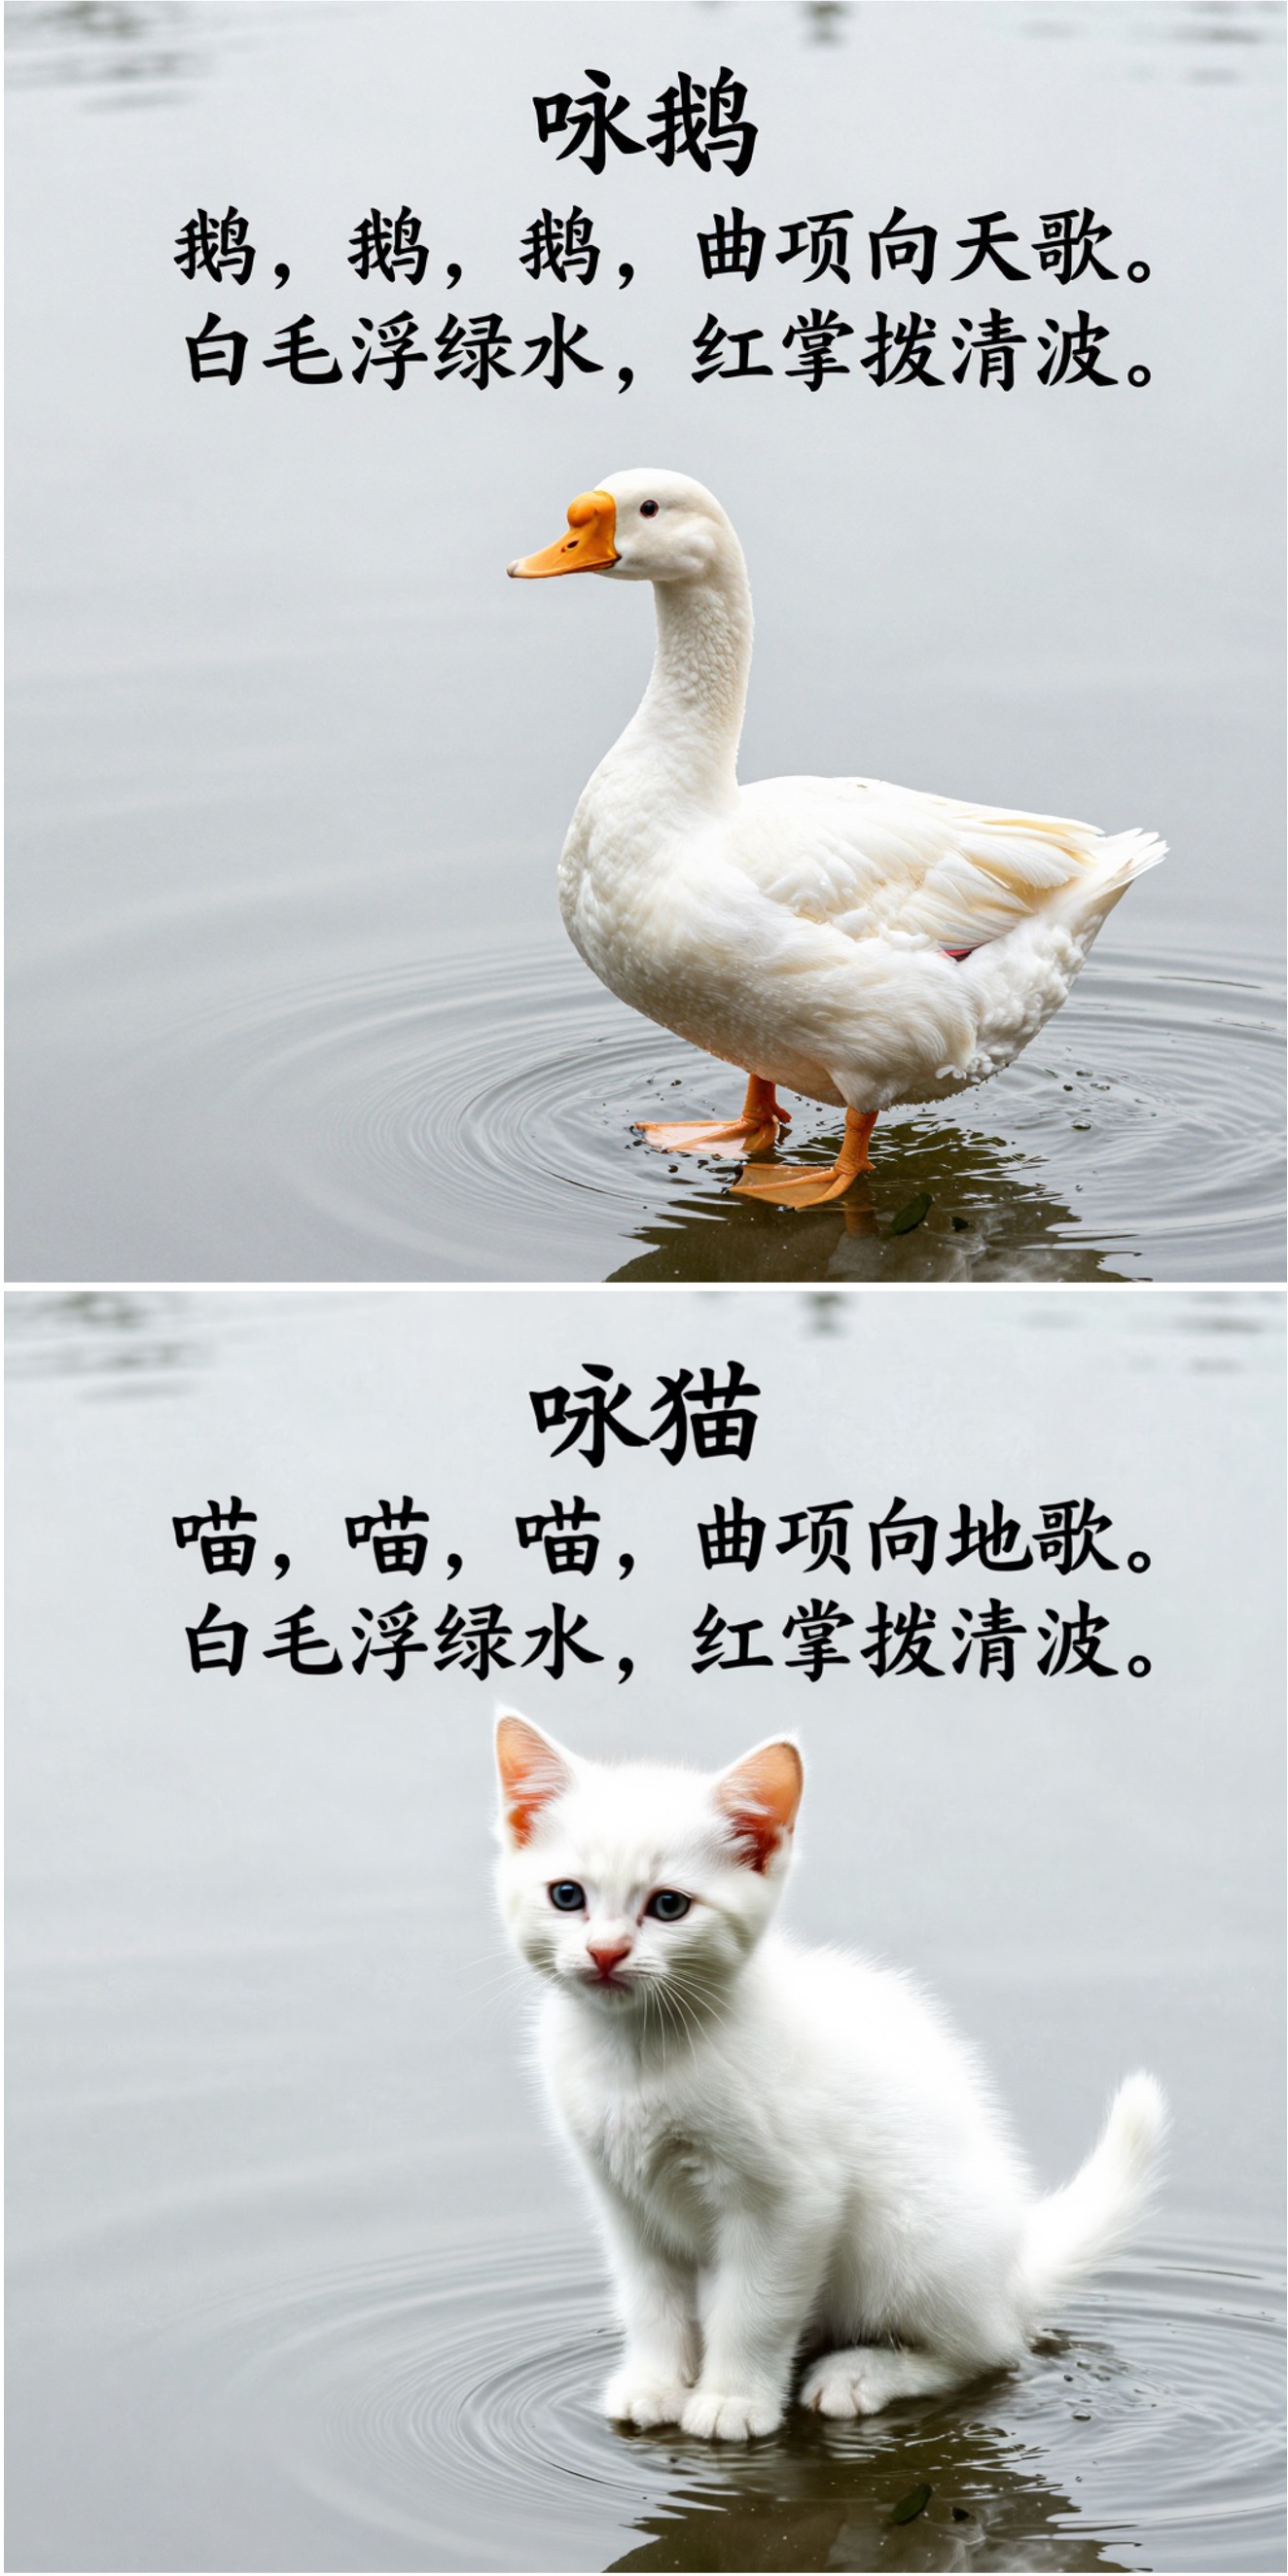
The powerful prompt enhancer (PE) uses a structured reasoning chain to inject logic and common sense, enabling the model to handle complex tasks like the "chicken-and-rabbit problem" or visualizing classical Chinese poetry.
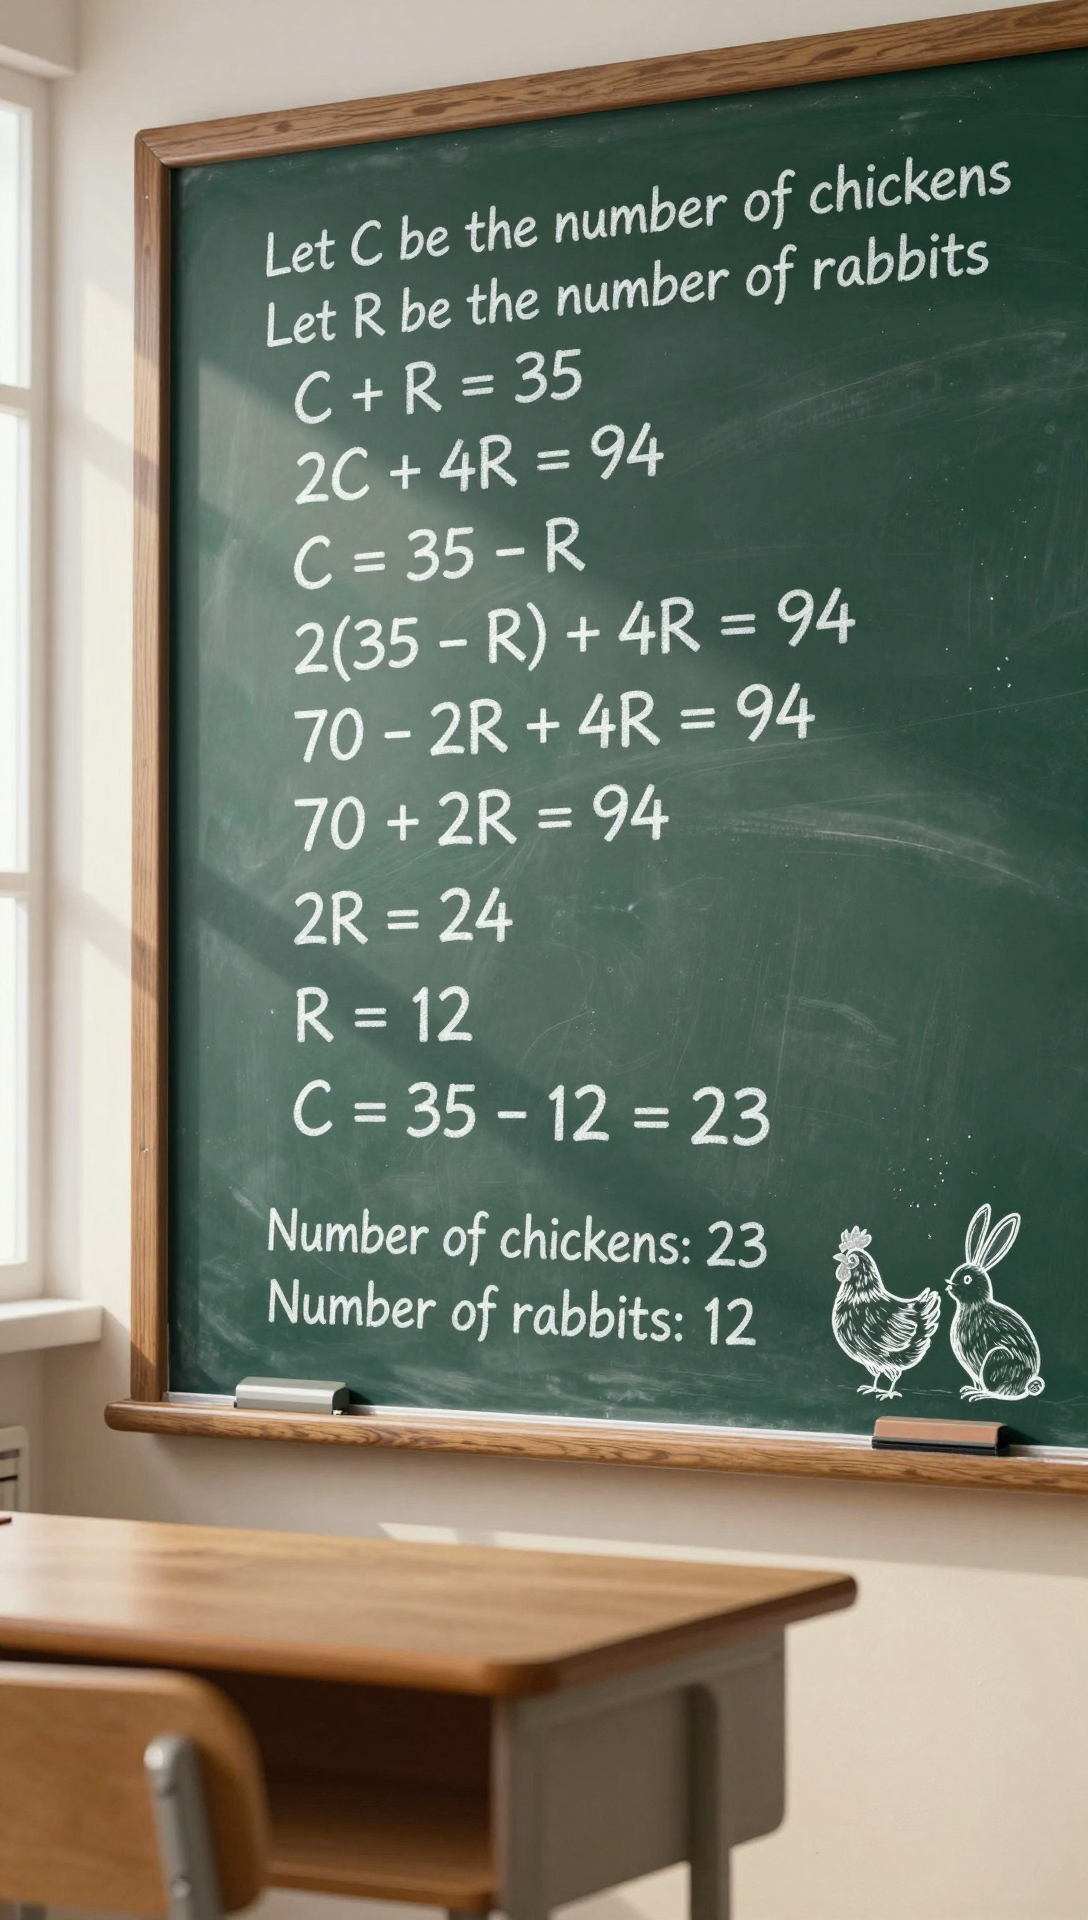
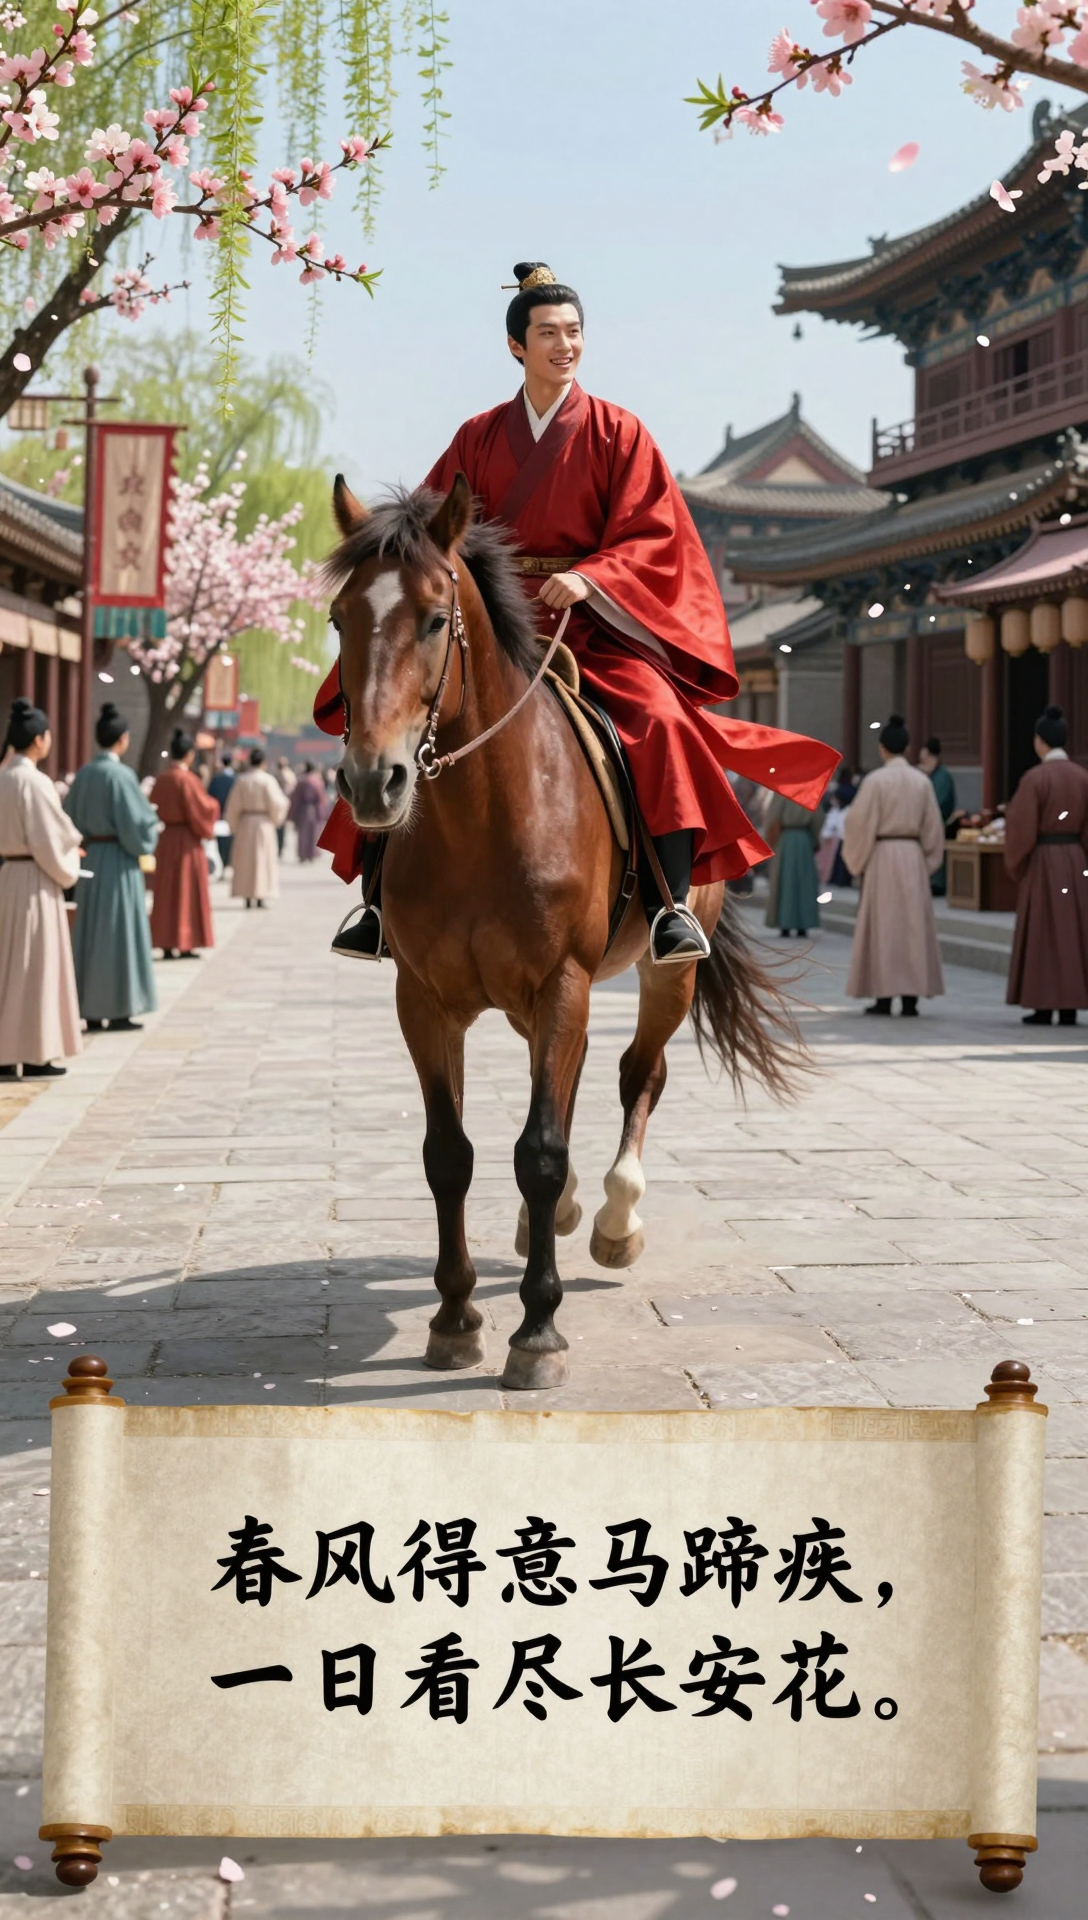
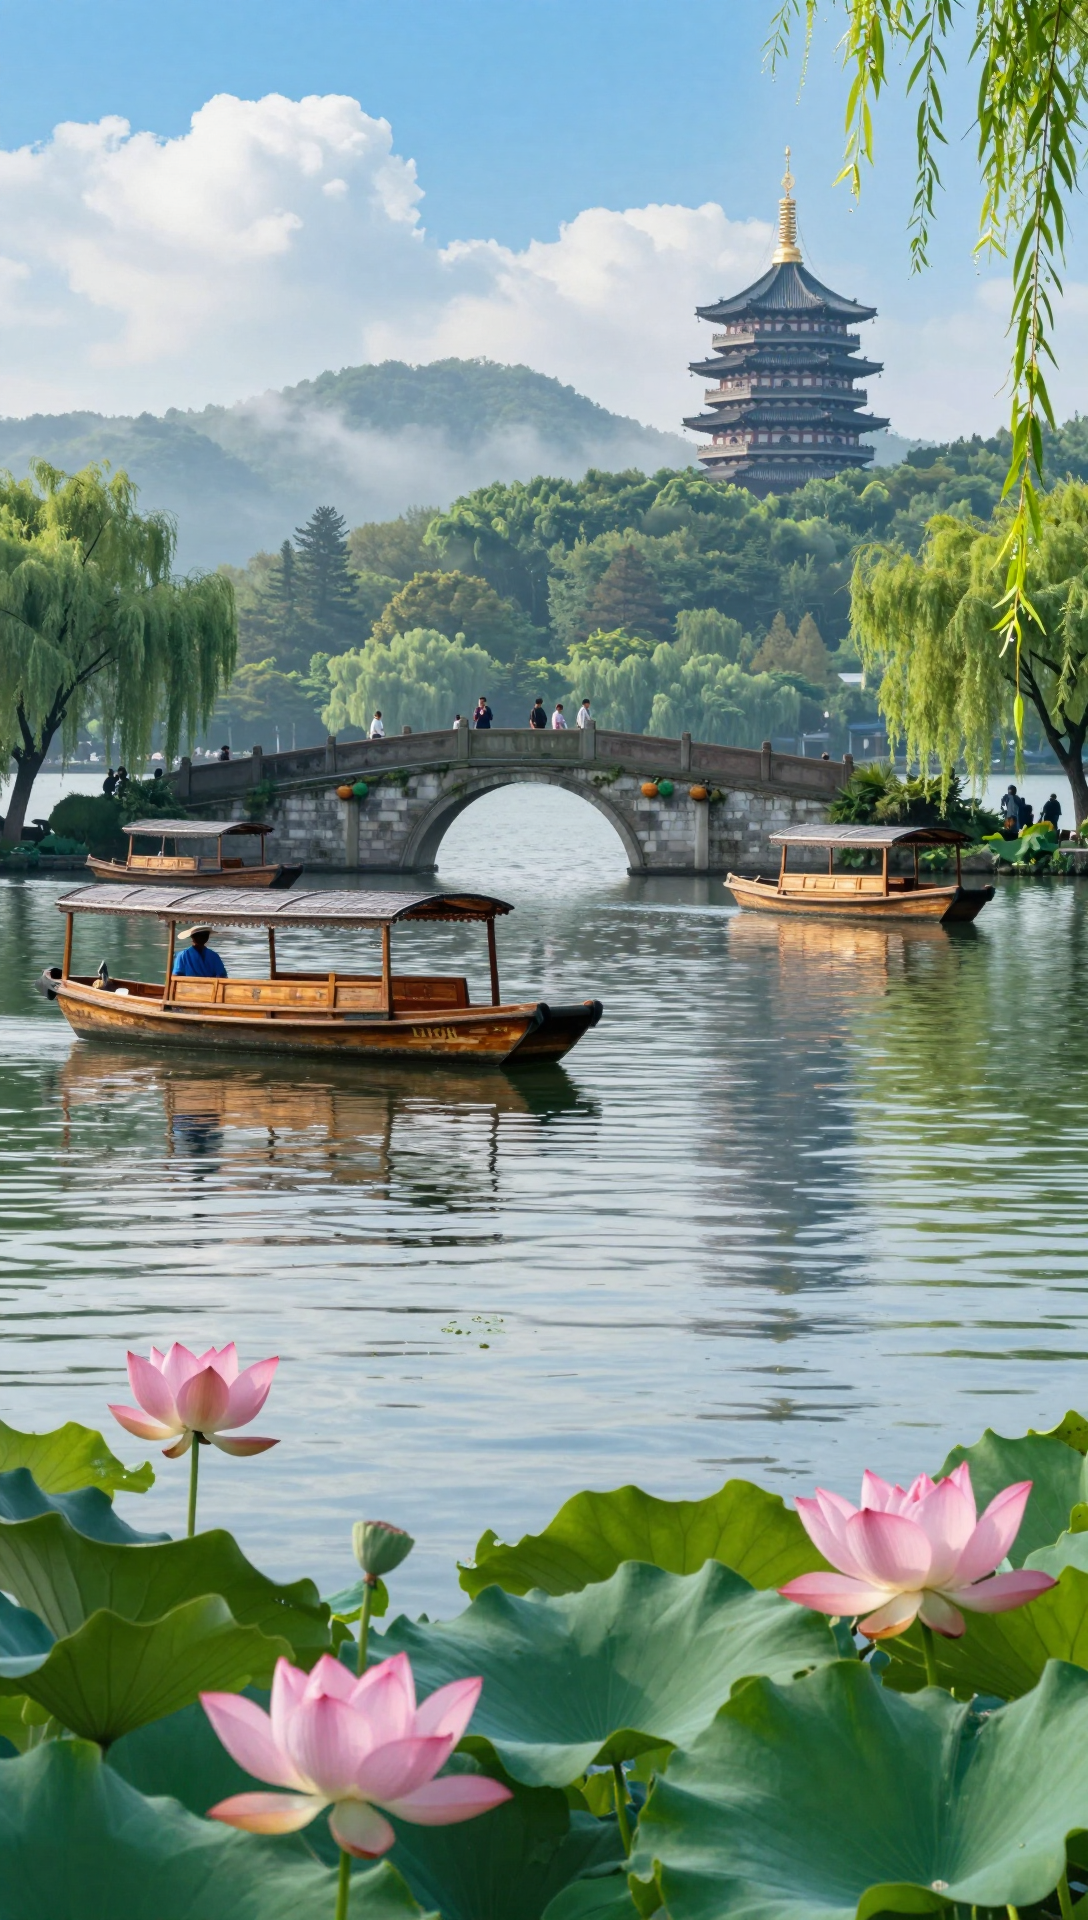
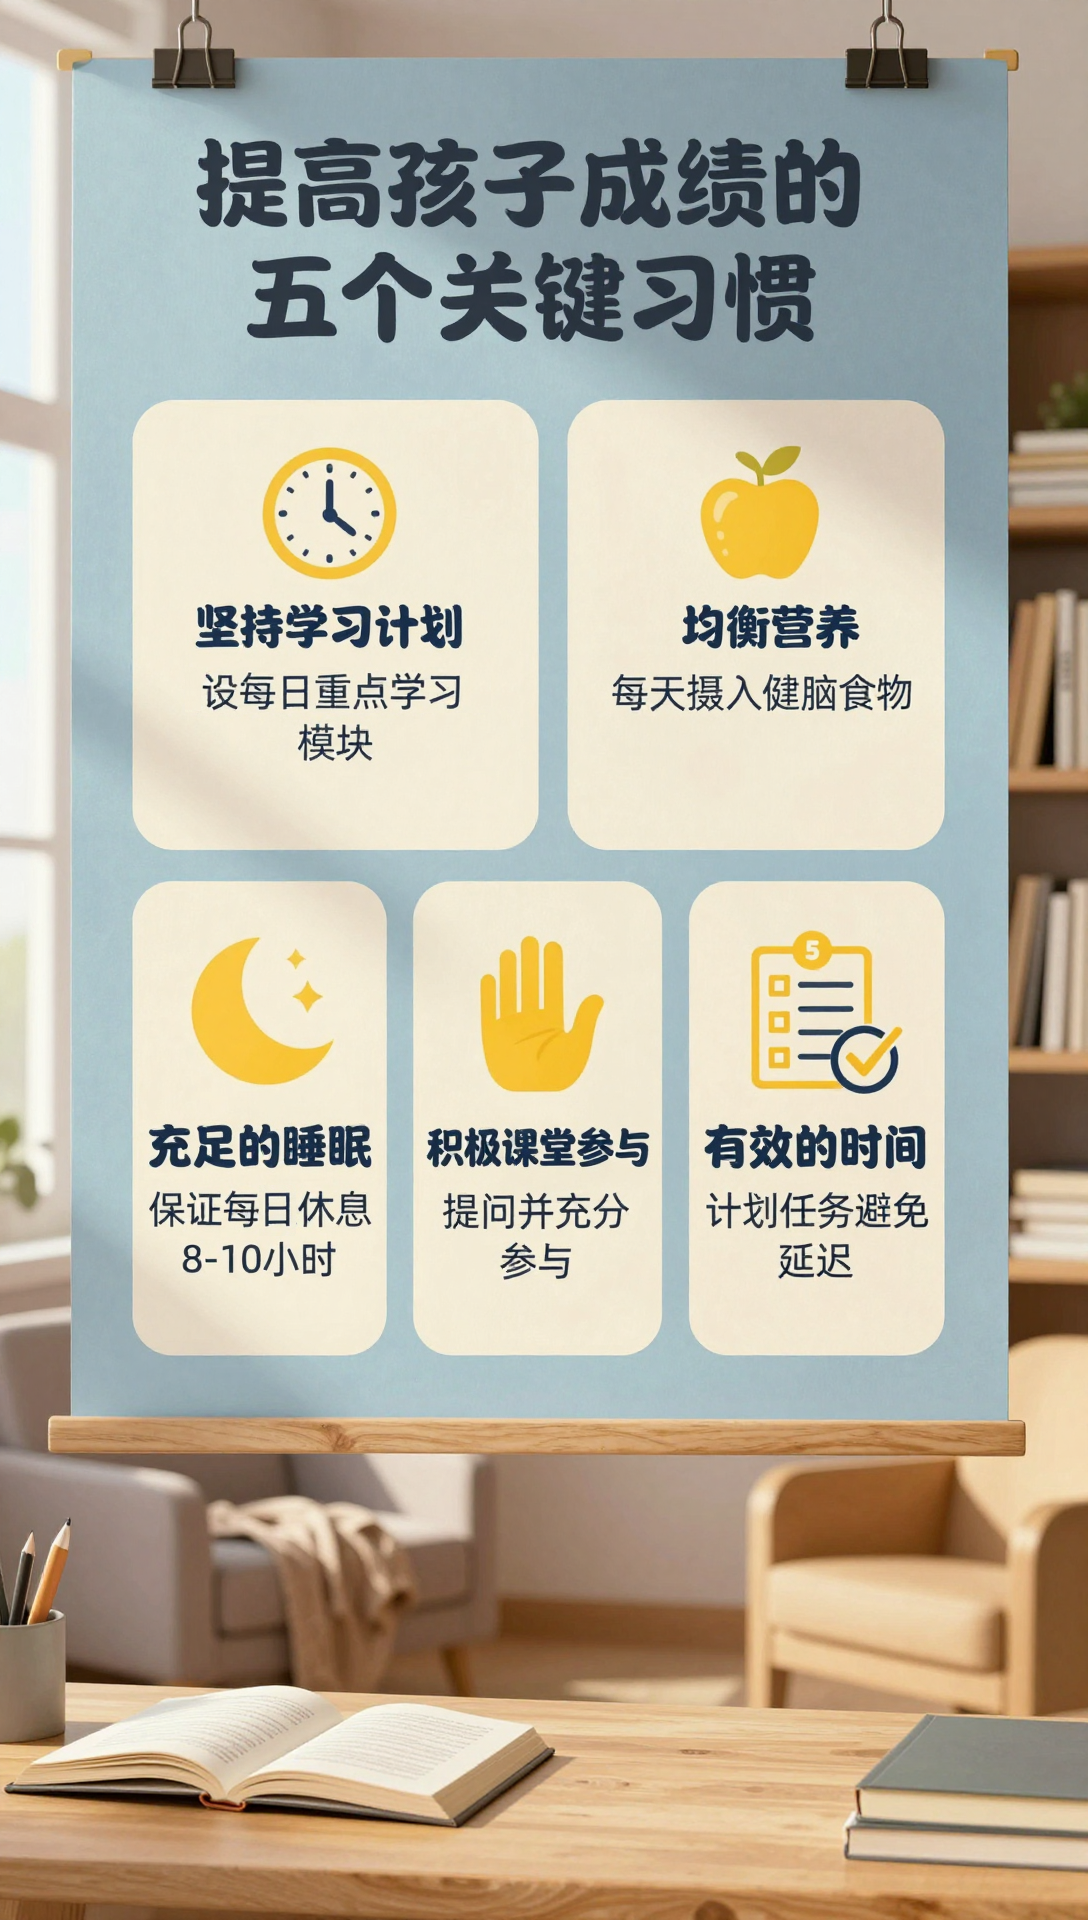
5. Strong Instruction-Following 强大的指令遵循与创意编辑
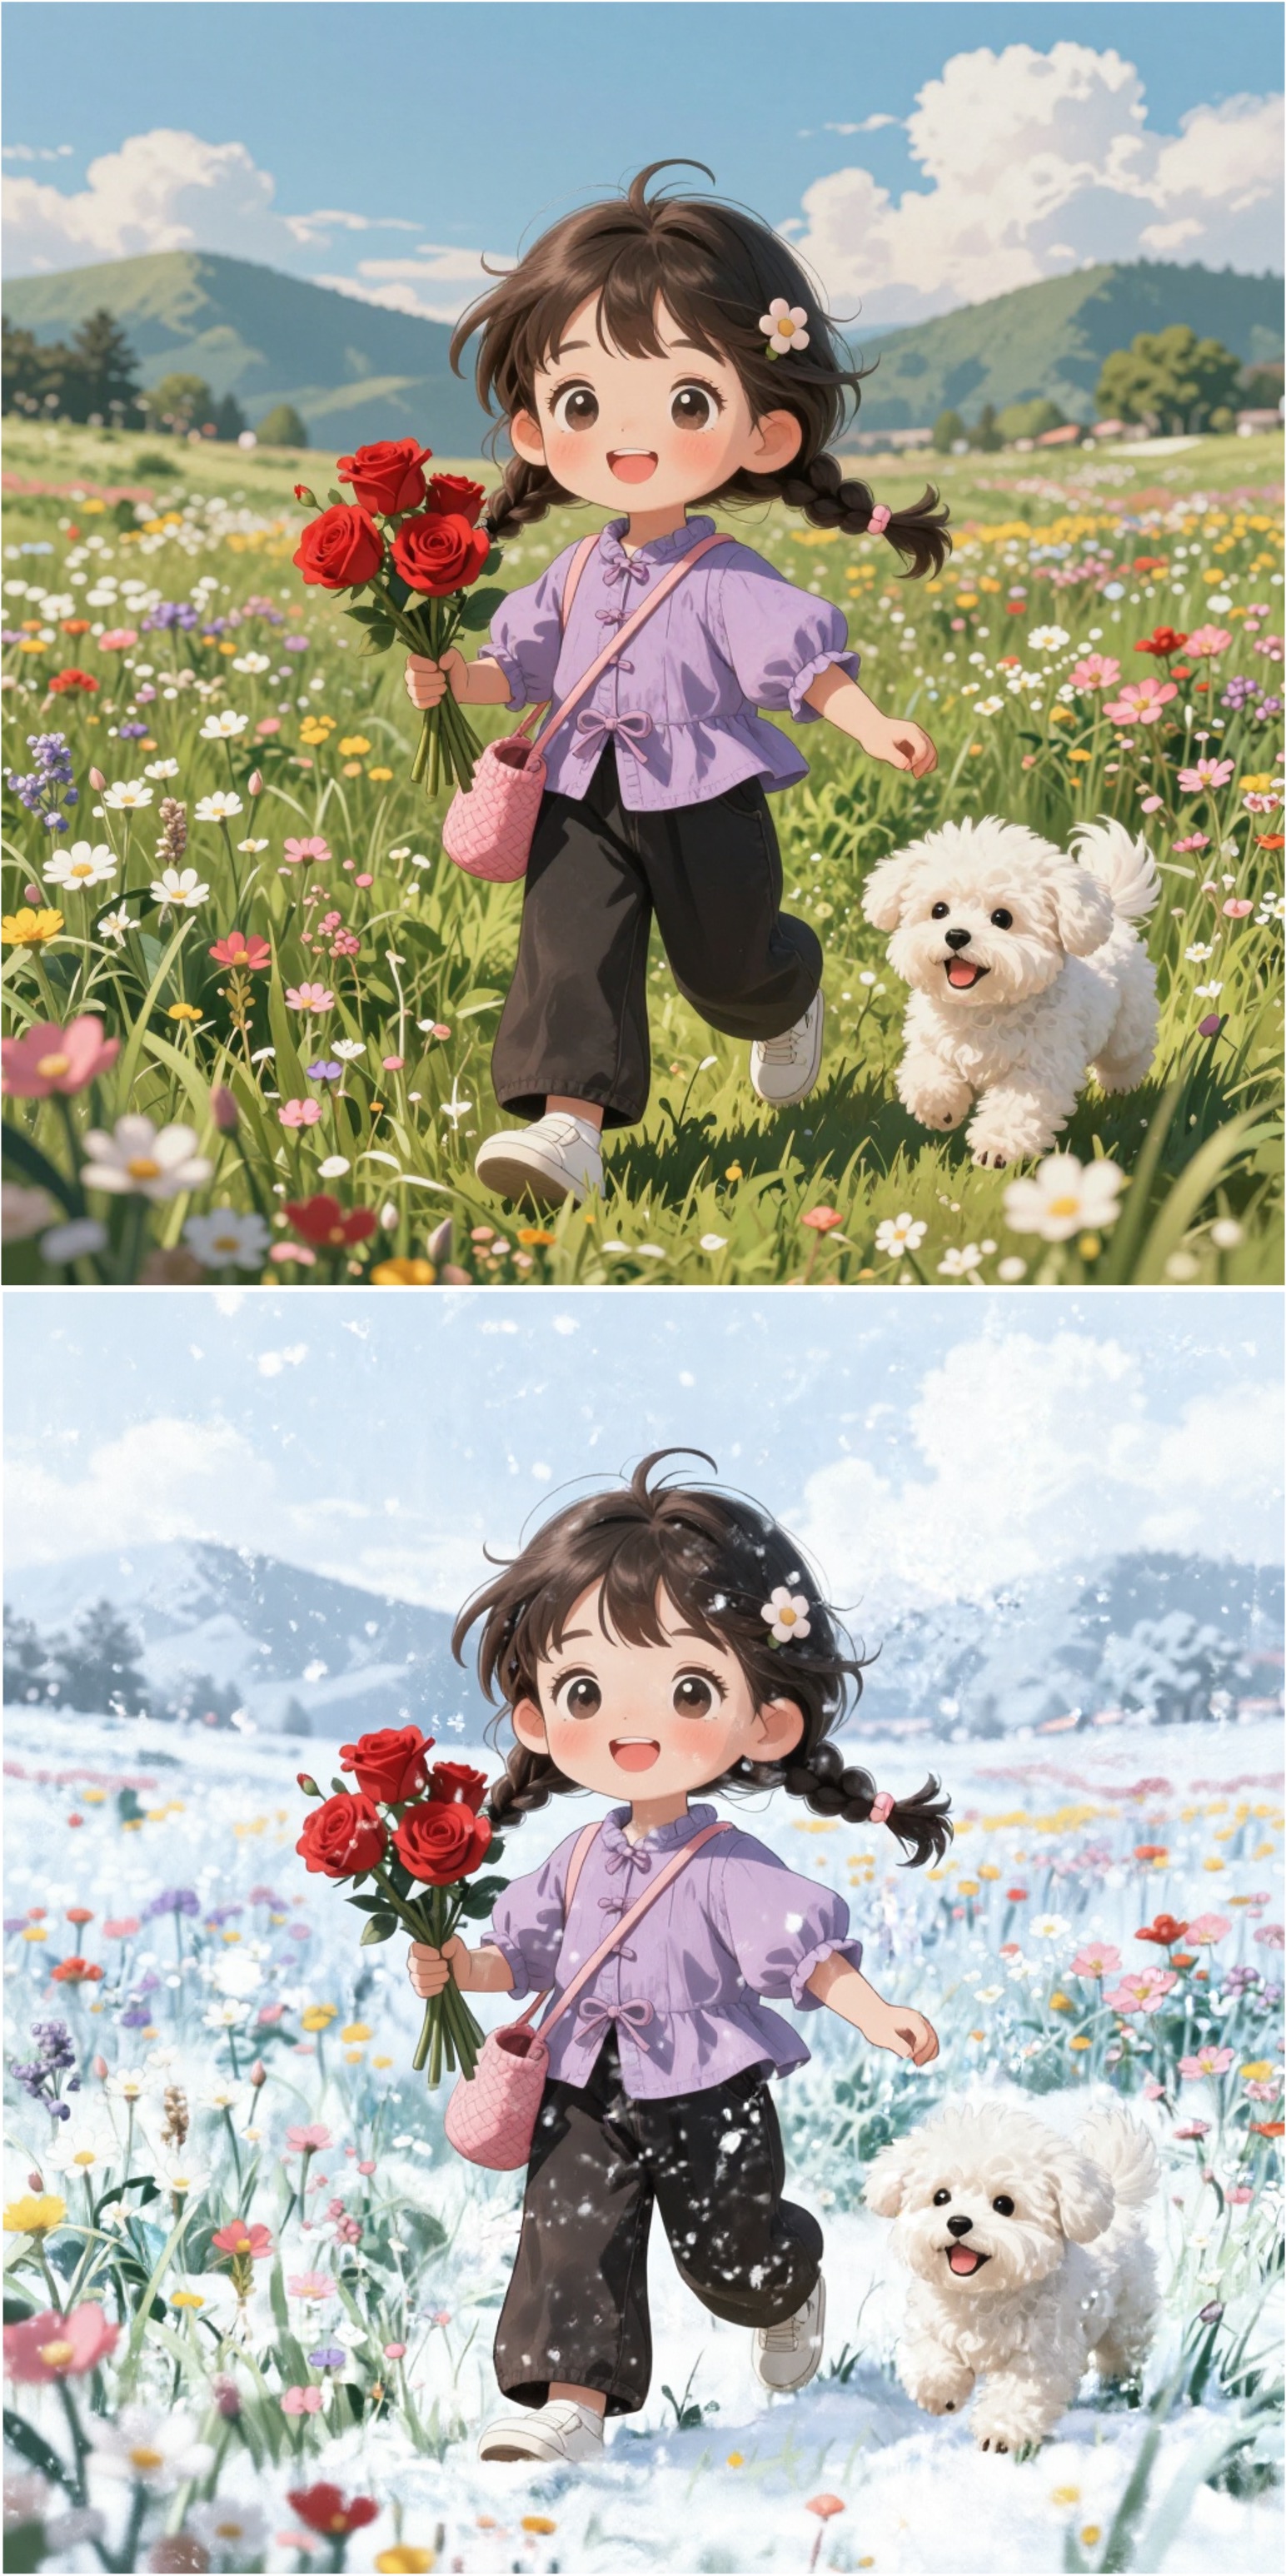
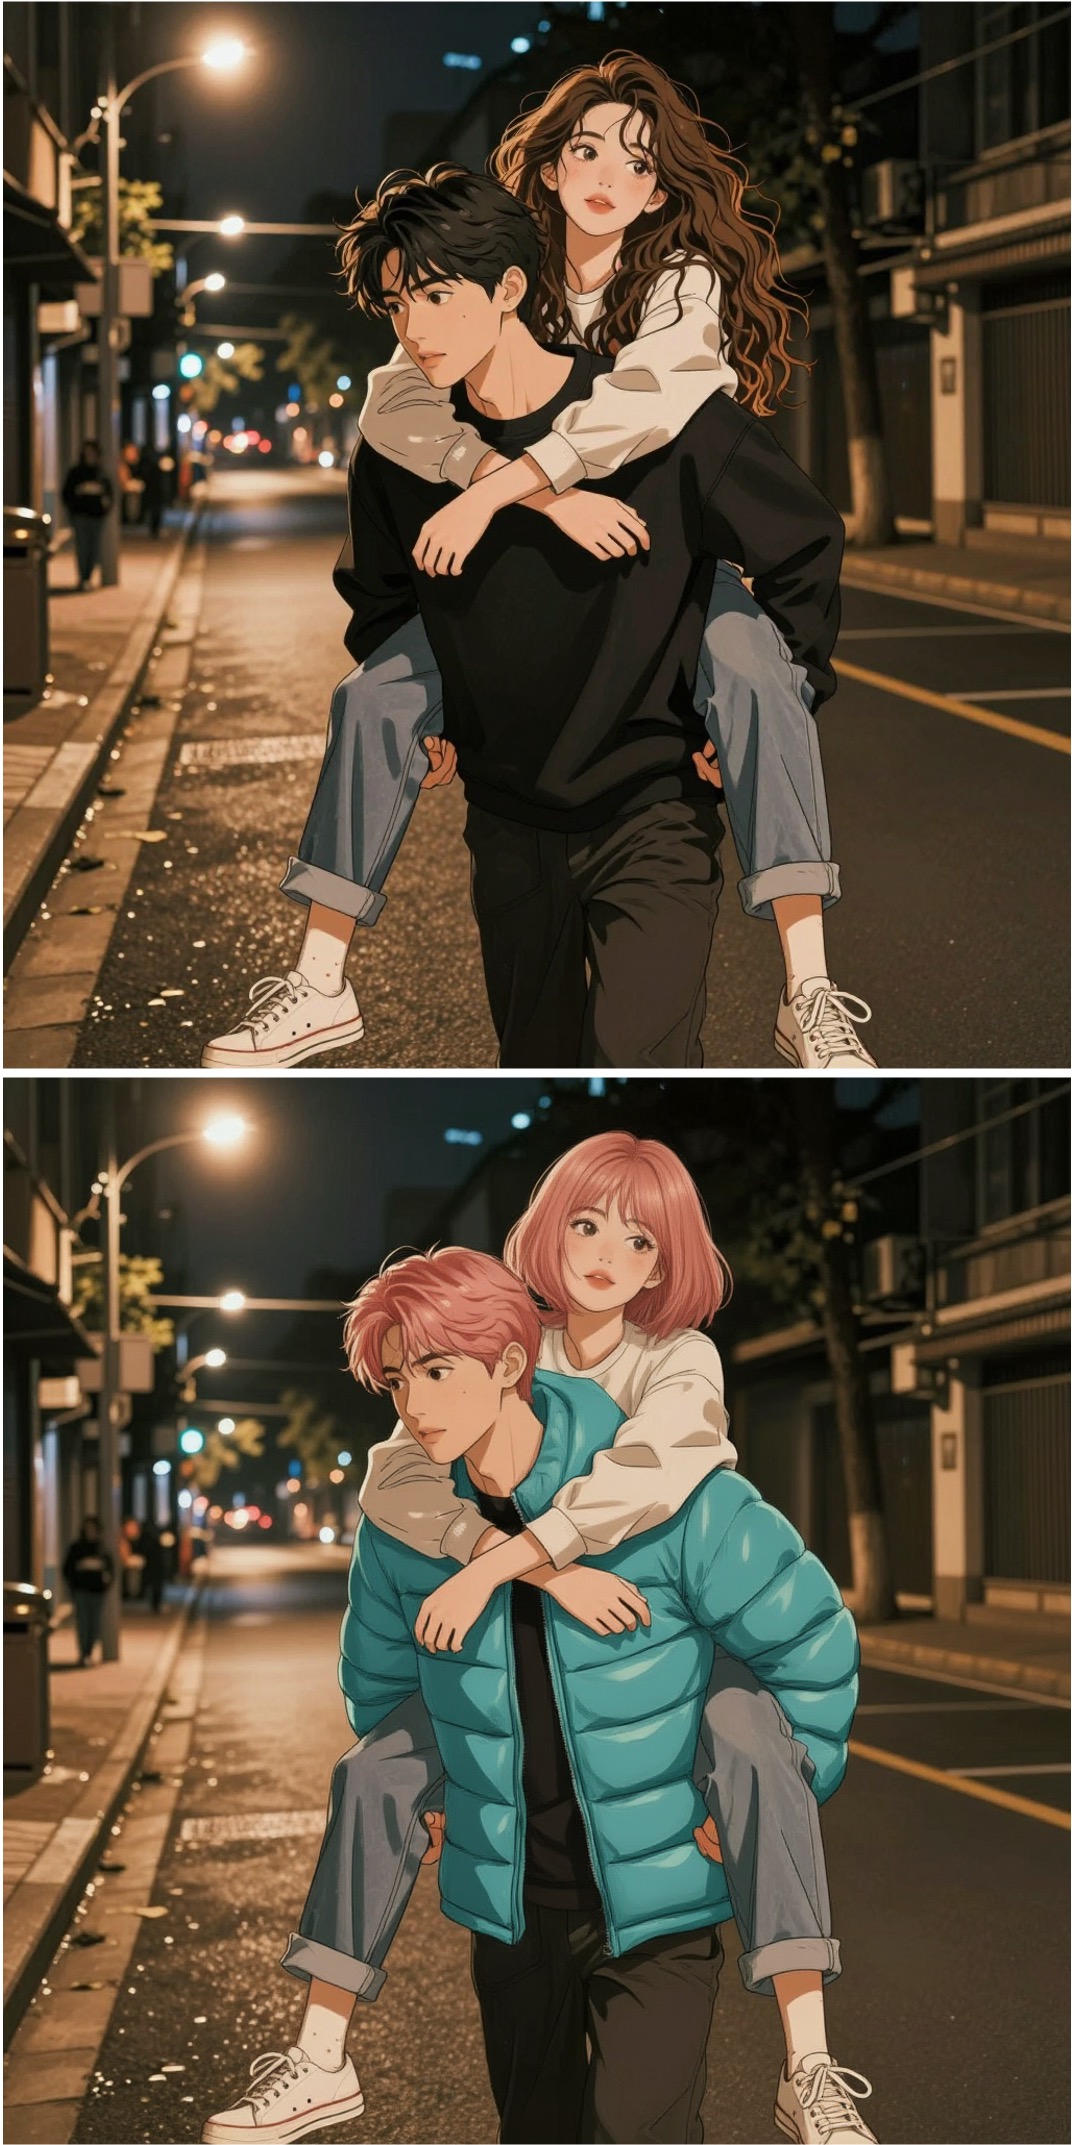
Z-Image-Edit can precisely execute complex instructions, such as simultaneously modifying a character's expression and pose while adding specified text. It maintains strong consistency even during significant transformations.
Summary 总结
Z-Image demonstrates that top-tier performance is not solely dependent on massive models and computational resources. This lowers the technical and cost barriers for researchers and developers, paving the way for more accessible and innovative applications.
Citation 引用
Welcome to cite our work. 欢迎引用我们的工作。
@misc{z-image-2025,
  title={Z-Image: An Efficient Image Generation Foundation Model with Single-Stream Diffusion Transformer},
  author={Tongyi Lab},
  year={2025},
  publisher={GitHub},
  journal={GitHub repository},
  howpublished={\url{https://github.com/Tongyi-MAI/Z-Image}}
}